Suffix Automaton (SAM)
Some Notation
- \(\Sigma\): Character set. The size of the character set is \(|\Sigma| = k\).
- \(s\): String. The length of the string is \(|s| = n\), indexed starting from \(0\).
- \(t_0\): Initial state.
- \(\operatorname{endpos}(t)\): The set of ending positions of substring \(t\) in string \(s\).
- \(\operatorname{link}(v)\): Suffix link of state \(v\).
- \(\operatorname{len}(v)\): Length of the longest substring corresponding to state \(v\).
- \(\operatorname{longest}(v)\): The longest substring corresponding to state \(v\).
- \(\operatorname{minlen}(v)\): Length of the shortest substring corresponding to state \(v\).
- \(\operatorname{shortest}(v)\): The shortest substring corresponding to state \(v\).
Overview of Suffix Automaton
Suffix automaton (SAM) is a powerful data structure that can solve many string-related problems.
For example, the following string problems can be solved in linear time using SAM:
- Searching for all occurrences of a string in another string;
- Counting the number of distinct substrings in a given string.
Intuitively, the SAM of a string can be understood as a compressed form of all substrings of the given string. It is noteworthy that SAM stores all this information in a highly compressed form. For a string of length \(n\), its space complexity is only \(O(n)\). Moreover, constructing the SAM also takes only \(O(n)\) time. To be precise, a SAM has at most \(2n-1\) states and \(3n-4\) transition edges.
Definition
The SAM of a string \(s\) is the smallest DFA that accepts all suffixes of \(s\).
In other words:
- SAM is a directed acyclic graph. Vertices are called states, and edges are called transitions between states.
- The graph has a source vertex \(t_0\), called the initial state, from which all other states are reachable.
- Each transition is labeled with some character. All transitions from a given state have distinct labels.
- There exist one or more terminal states. If we start from the initial state \(t_0\) and eventually reach a terminal state, then the concatenation of labels along the path must be a suffix of string \(s\). Conversely, every suffix of \(s\) can be represented by a path from \(t_0\) to some terminal state.
- Among all automata satisfying the above conditions, SAM has the smallest number of states.
The key property of SAM lies precisely in this minimality. In fact, directly constructing an AC automaton for all suffixes of \(s\) also yields a DFA that accepts all suffixes of \(s\). However, in the worst case, such an automaton would have \(\Theta(n^2)\) states, which is unacceptable in terms of complexity. As shown in the example below, many states in the DFA built from all suffixes are duplicated and can be merged. SAM pushes the merging of states to the extreme, thereby controlling the size of the resulting DFA to \(O(n)\). In this sense, SAM is a "compressed" AC automaton for all suffixes of the string.
Substrings and Paths
The simplest and most important property of SAM is that it contains information about all substrings of string \(s\). Any path starting from the initial state \(t_0\), if we write down all the labels along the path, forms a substring of \(s\). Conversely, each substring of \(s\) corresponds to some path starting from \(t_0\).
To simplify the expression, we say a substring corresponds to this path (starting from \(t_0\) and whose labels form this substring). Conversely, we say any path corresponds to the string formed by its labels.
There may be more than one path reaching a given state, so we say a state corresponds to a set of strings, each corresponding to one of these paths.
Simple Examples
We will show here some simple suffix automata for strings.
We use blue for the initial state and green for terminal states.
For string \(s=\varnothing\):

For string \(s=\texttt{a}\):
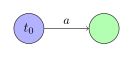
For string \(s=\texttt{aa}\):
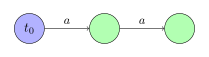
For string \(s=\texttt{ab}\):
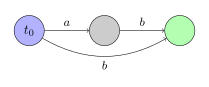
For string \(s=\texttt{abb}\):
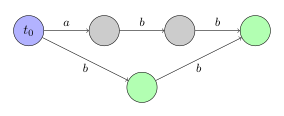
For string \(s=\texttt{abbb}\):
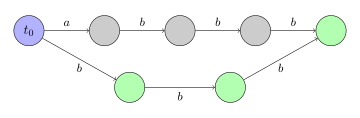
In the last example, we can see that if we directly build the AC automaton for all its suffixes, paths \(\texttt{bbb}\) and \(\texttt{abbb}\) should lead to different states, but both states are terminal, and no matter what character is added afterward, no longer matching string can be obtained. This indicates that the two states exhibit the same behavior in terms of transitions and thus can be merged into a single state. This yields the SAM as shown. The following discussion will extend this idea of merging states to all cases and show that, by properly merging states, the resulting SAM has only \(O(n)\) states and transitions.
Linear-Time Construction Algorithm
Before describing the algorithm for constructing SAM in linear time, we need to introduce two concepts crucial for understanding the construction process and briefly prove their properties. Among them, the ending position \(\operatorname{endpos}\) defines the states in SAM (i.e., indicates the necessary and sufficient condition for merging states), while the suffix link \(\operatorname{link}\) is the natural counterpart of the failure pointer in AC automaton.
Ending Position endpos
Consider any non-empty substring \(t\) of string \(s\). We denote \(\operatorname{endpos}(t)\) as the set of all ending positions of \(t\) in string \(s\) (assuming characters in the string are indexed from zero). For example, for string \(\texttt{abcbc}\), we have \(\operatorname{endpos}(\texttt{bc})=\{2,4\}\).
Two substrings \(t_1\) and \(t_2\) may have exactly the same ending positions: \(\operatorname{endpos}(t_1)=\operatorname{endpos}(t_2)\). This defines an equivalence relation among the substrings of string \(s\). All non-empty substrings of \(s\) can be partitioned into several equivalence classes based on their \(\operatorname{endpos}\) sets.
A fact is that each such equivalence class corresponds to a state in SAM1. That is, as long as two substrings have the same ending positions, their paths in SAM correspond to the same state. In other words, each non-initial state in SAM corresponds to one or more non-empty substrings with the same \(\operatorname{endpos}\). In summary, the states in SAM are exactly the equivalence classes of all non-empty substrings, plus the initial state.
Accepting this fact for now, we will introduce the algorithm for constructing SAM based on it. We will also show that SAM satisfies all required properties except minimality; minimality can be derived from Myhill–Nerode theorem.
From the values of \(\operatorname{endpos}\), we can derive some important conclusions that explain the relationships between different substrings corresponding to the same state.
Lemma 1
Two non-empty substrings \(u\) and \(w\) of string \(s\) (assuming \(\left|u\right|\le \left|w\right|\)) have the same \(\operatorname{endpos}\) if and only if string \(u\) appears in \(s\) only as a suffix of \(w\).
Proof
The lemma is obvious. If \(u\) and \(w\) have the same \(\operatorname{endpos}\), then \(u\) is a suffix of \(w\) and appears in \(s\) only as a suffix of \(w\). Conversely, by definition, if \(u\) is a suffix of \(w\) and appears in \(s\) only as a suffix of \(w\), then the two substrings have the same \(\operatorname{endpos}\).
Lemma 2
Consider two non-empty substrings \(u\) and \(w\) (assuming \(\left|u\right|\le \left|w\right|\)). Then, either \(\operatorname{endpos}(u)\cap \operatorname{endpos}(w)=\varnothing\), or \(\operatorname{endpos}(w)\subseteq \operatorname{endpos}(u)\), depending on whether \(u\) is a suffix of \(w\):
Proof
If the sets \(\operatorname{endpos}(u)\) and \(\operatorname{endpos}(w)\) have at least one common element, then since strings \(u\) and \(w\) end at the same position, \(u\) is a suffix of \(w\). Therefore, wherever \(w\) appears, substring \(u\) also appears. Hence \(\operatorname{endpos}(w)\subseteq \operatorname{endpos}(u)\).
Lemma 3
Consider an equivalence class of substrings with the same \(\operatorname{endpos}\). Sort all substrings in the class in non-increasing order of length. Then, each substring is no longer than the previous one, and each substring is a suffix of the previous one. In other words, for any two substrings in the same equivalence class, the shorter one is a suffix of the longer one, and the lengths of substrings in this class are consecutive, covering all integer values in a certain interval.
Proof
If the equivalence class contains only one substring, the lemma obviously holds. Now we discuss equivalence classes with more than one substring.
By Lemma 1, among two different strings with the same \(\operatorname{endpos}\), one must be longer and the other shorter, and the shorter one is always a proper suffix of the longer one. That is, there are no strings of equal length in the equivalence class.
Let \(w\) be the longest string in the equivalence class, and \(u\) be the shortest. By Lemma 1, string \(u\) is a proper suffix of string \(w\). Now consider any suffix of \(w\) with length in the interval \([\left|u\right|,\left|w\right|]\). It is easy to see that this suffix is also in the same equivalence class, because this suffix can only appear in string \(s\) as a suffix of \(w\) (since the shorter suffix \(u\) appears in \(s\) only as a suffix of \(w\)). Therefore, by Lemma 1, this suffix has the same \(\operatorname{endpos}\) as string \(w\).
In a nutshell, the substrings corresponding to the same state have different lengths, and these lengths are consecutive natural numbers, where the shorter ones are always suffixes of the longer ones.
Suffix Link link
Consider some state \(v\neq t_0\) in SAM. We already know that state \(v\) corresponds to an equivalence class of substrings with the same \(\operatorname{endpos}\). If we define \(w\) as the longest among these strings, then all other strings are suffixes of \(w\).
We also know that the first few suffixes of string \(w\) (considered in descending order of length) are all contained in this equivalence class, while other suffixes (at least one—the empty suffix) belong to other equivalence classes. Let \(t\) be the longest among these other suffixes, and then connect the suffix link of \(v\) to \(t\).
In other words, the suffix link \(\operatorname{link}(v)\) connects to the state corresponding to the longest suffix of \(w\) that has a different \(\operatorname{endpos}\) set, i.e., the longest suffix of \(w\) that appears more times in \(s\) than \(w\) itself.
For convenience, we stipulate that the equivalence class corresponding to the initial state \(t_0\) contains only the empty string, and \(\operatorname{endpos}(t_0)=\{-1,0,\ldots,\left|S\right|-1\}\).
Lemma 4
All suffix links form a tree rooted at \(t_0\).
Proof
Consider any state \(v\neq t_0\). The suffix link \(\operatorname{link}(v)\) connects to a state corresponding to a strictly shorter string (by definition of suffix link and Lemma 3). Therefore, by following suffix links, we always eventually reach the initial state \(t_0\) corresponding to the empty string.
Lemma 5
The tree constructed with \(\operatorname{endpos}\) sets as nodes and set inclusion as edges (i.e., each child's \(\operatorname{endpos}\) set is contained in its parent's \(\operatorname{endpos}\) set) is the same as the tree constructed via suffix links \(\operatorname{link}\).
Proof
By Lemma 2, the \(\operatorname{endpos}\) sets of any SAM form a tree (because two sets are either disjoint or one is a subset of the other).
Now consider any state \(v\neq t_0\) and its suffix link \(\operatorname{link}(v)\). By the definition of suffix link and Lemma 2, we have
Note that it should be \(\subsetneq\) rather than \(\subseteq\), because if \(\operatorname{endpos}(v)=\operatorname{endpos}(\operatorname{link}(v))\), then \(v\) and \(\operatorname{link}(v)\) should be merged into a single state.
Combining the previous lemmas: The tree formed by suffix links is essentially a tree of \(\operatorname{endpos}\) sets.
Here is an example of the suffix link tree generated when constructing SAM for string \(\texttt{abcbc}\), where nodes are labeled with the longest substring in the corresponding equivalence class.
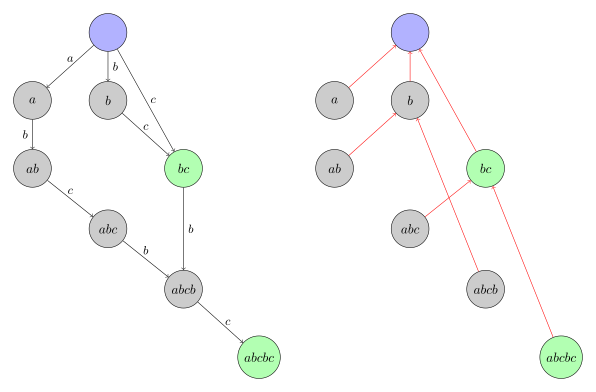
Combined with the illustration, gaining some understanding of suffix automaton will be helpful for understanding its construction algorithm and applications below.
Explanation of the Illustration
- There exists a longest path in SAM whose labels are exactly the string \(\texttt{abcbc}\) itself. This path starts from the initial state, and each state passed corresponds to a prefix of \(\texttt{abcbc}\) (\(\varnothing,\texttt{a},\texttt{ab},\texttt{abc},\texttt{abcb},\texttt{abcbc}\)). These states are crucial in later applications.
-
The suffix link tree can be seen as "compressing" the paths from these "prefix states" moving along suffix links to the root (the initial state).
- Along each path, the set of strings corresponding to the nodes forms a partition of all suffixes of the corresponding prefix. For example, the path from the state labeled \(\texttt{abcbc}\) to the root is \(\texttt{abcbc}\rightarrow\texttt{bc}\rightarrow\varnothing\). Here, node \(\texttt{abcbc}\) actually corresponds to the string set \(\{\texttt{abcbc},\texttt{bcbc},\texttt{cbc}\}\), node \(\texttt{bc}\) corresponds to \(\{\texttt{bc},\texttt{c}\}\), and node \(\varnothing\) corresponds to the empty string.
- Different paths may share the same node, which is why there is "compression". For example, paths \(\texttt{abc}\rightarrow\texttt{bc}\rightarrow\varnothing\) and \(\texttt{abcbc}\rightarrow\texttt{bc}\rightarrow\varnothing\) share node \(\texttt{bc}\). This is because \(\operatorname{endpos}(\texttt{bc})=\{2,4\}\), and the string \(\texttt{bc}\) ending at position \(2\) is preceded by character \(\texttt{a}\), while the string \(\texttt{bc}\) ending at position \(4\) is preceded by character \(\texttt{c}\). Therefore, when adding characters in front (i.e., moving against suffix links), the set of ending positions (i.e., the state) splits.
- The suffix link tree only needs to "compress" these suffix paths together reasonably, without considering other nodes. This is because all substrings are suffixes of some prefix, so they must appear in some such path. The construction algorithm essentially adds characters one by one, and for each newly added prefix, constructs such a suffix path and "compresses" it reasonably into the existing paths (i.e., not reconstructing already existing states and transitions).
- The terminal states are exactly all nodes on the suffix path of the string \(\texttt{abcbc}\) itself.
-
Transitions leading to the same state must have the same label, and the starting points of these transitions must lie on some (continuous) path in the suffix link tree. For example, there are two states that transition to state \(\texttt{abcb}\): \(\texttt{abc}\) and \(\texttt{bc}\). They lie on the path \(\texttt{abc}\rightarrow\texttt{bc}\) in the suffix tree. Note that they correspond to string sets \(\{\texttt{abc}\}\) and \(\{\texttt{bc},\texttt{c}\}\), respectively. Adding character \(\texttt{b}\) after these strings yields the string set \(\{\texttt{abcb},\texttt{bcb},\texttt{cb}\}\) corresponding to state \(\texttt{abcb}\).
- After adding a character, different states may transition to the same state because the newly added character makes it harder to increase the set of ending positions.
-
In the suffix link tree, the \(\operatorname{endpos}\) set of each node is the union of the \(\operatorname{endpos}\) sets of its children, possibly plus one more position. Moreover, this new position exists if and only if the node exactly corresponds to a prefix of the original string ending at that position. Since in the illustration, non-root non-leaf nodes do not correspond to prefixes of \(\texttt{abcbc}\), this situation does not occur.
The suffix automaton stores information about all substrings of the string. This can be understood from two perspectives:
- SAM itself can be seen as a compressed version of the AC automaton for all suffixes of the string. Therefore, it stores information about all prefixes of all suffixes of the string, which is equivalent to storing information about all substrings of the string.
- The suffix link tree of SAM can be seen as a compressed version of the suffix paths of all prefixes of the string. Therefore, it stores information about all suffixes of all prefixes of the string, which is also equivalent to storing information about all substrings of the string.
Both perspectives are useful when dealing with different problems.
Summary
Before further discussing the algorithm itself, we summarize the previous content and introduce some auxiliary notation.
-
Substrings of \(s\) can be partitioned into equivalence classes based on their \(\operatorname{endpos}\) sets;
-
SAM consists of the initial state \(t_0\) and each state corresponding to each \(\operatorname{endpos}\) equivalence class (of non-empty substrings);
-
Each state \(v\) matches one or more substrings. We denote \(\operatorname{longest}(v)\) as the longest such string, and \(\operatorname{len}(v)\) as its length. Similarly, denote \(\operatorname{shortest}(v)\) as the shortest substring, with length \(\operatorname{minlen}(v)\). Then all strings corresponding to this state are different suffixes of string \(\operatorname{longest}(v)\), and their lengths exactly cover every integer in the interval \([\operatorname{minlen}(v),\operatorname{len}(v)]\).
-
For any state \(v\neq t_0\), define the suffix link as an edge connecting to the suffix of \(\operatorname{longest}(v)\) of length \(\operatorname{minlen}(v)-1\). The suffix links starting from the root \(t_0\) form a tree. This tree also represents the inclusion relations among \(\operatorname{endpos}\) sets.
-
For any state \(v\neq t_0\), we can express \(\operatorname{minlen}(v)\) using the suffix link \(\operatorname{link}(v)\):
\[ \operatorname{minlen}(v)=\operatorname{len}(\operatorname{link}(v))+1. \] -
If we start from any state \(v_0\) and follow suffix links, we always reach the initial state \(t_0\). In this case, we obtain a sequence of disjoint intervals \([\operatorname{minlen}(v_i),\operatorname{len}(v_i)]\), whose union forms a continuous interval \([0,\operatorname{len}(v_0)]\).
Algorithm
Now we can discuss the algorithm for constructing SAM. This algorithm is online: we can add each character of the string one by one and maintain the SAM accordingly at each step.
Before discussing the detailed implementation, let's first get a preliminary feel for the possible changes in SAM when adding a new character \(c\).
Simple Understanding of Incremental Construction
Based on the SAM of string \(s\), we can construct the SAM of string \(s+c\). According to the previous explanation of the illustration, we only need to construct the suffix path for the newly added prefix (i.e., \(s+c\)) and compress it into the existing paths. Moreover, as described earlier, the nodes on the new suffix path must be reachable via character \(c\) from nodes on the suffix path of the original string \(s\).
We first consider what form the suffix path of the original string \(s\) might have before adding the new character \(c\), and how it transitions via character \(c\). The most general situation is illustrated below:
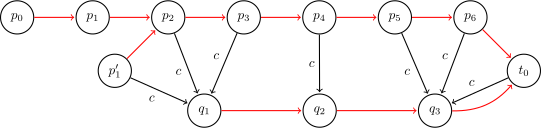
In the figure, the suffix path of the original string \(s\) is \(p_0\rightarrow p_1\rightarrow\cdots\rightarrow p_6\rightarrow t_0\), with suffix links shown as red arrows. Some nodes (i.e., \(p_2\sim p_6\)) already have transitions via character \(c\); because adding the same character to consecutive suffixes yields consecutive suffixes, the destinations of these transitions form another suffix path \(q_1\rightarrow q_2\rightarrow q_3\rightarrow t_0\). At this point, two observations:
-
On the suffix path of the original string \(s\), the nodes without a transition via \(c\) must be the first few nodes. Once a node (like \(p_2\) in the figure) has a transition via \(c\), subsequent nodes also have transitions via \(c\).
Explanation: Let \(s_2=\operatorname{longest}(p_2)\). Then all subsequent nodes correspond to suffixes of \(s_2\). If \(s_2+c\) also appears in \(s\), then the result of adding \(c\) to any suffix of \(s_2\) must also appear in \(s\), so these nodes all have transitions via \(c\).
-
Although the nodes that can reach node \(q_i\) via character \(c\) must form a continuous segment in the suffix link tree, this segment may not entirely lie on the suffix path from \(p_0\) to the root. In particular, only the first few nodes in the segment corresponding to the first node \(q_1\) may not be on this suffix path. For example, node \(p_1'\) in the figure is not on the suffix path of \(p_0\).
Explanation: Let \(s_2=\operatorname{longest}(p_2)\). Then \(s_2+c\) corresponds to \(q_1\), but clearly \(s_2+c\neq\operatorname{longest}(q_1)\) in the figure, because the latter is \(\operatorname{longest}(p'_1)+c\). This indicates that part of the strings corresponding to \(q_1\) cannot be derived from \(s_2\) and its suffixes. Conversely, strings in \(q_2\) must be suffixes of \(s_2+c\), so removing the trailing \(c\) yields suffixes of \(s_2\). That is, nodes transitioning to \(q_2\) via \(c\) must lie on the suffix path starting from \(p_2\). This is why only some nodes in the segment corresponding to the starting \(q_1\) may not be on the suffix path of \(p_0\).
For this illustration, if we add a character \(c\) at the end of the original string \(s\) and construct the corresponding suffix path, what changes? The answer is shown below:
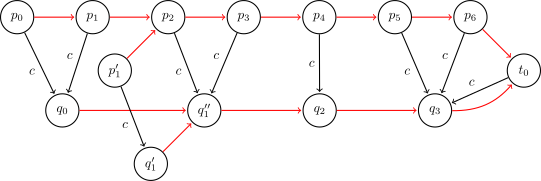
Since node \(q_0\) is derived from node \(p_0\) (corresponding to the original string \(s\)) via character \(c\), it corresponds to the new string \(s+c\). Therefore, its suffix path \(q_0\rightarrow q_1''\rightarrow q_2\rightarrow q_3\rightarrow t_0\) is the newly added suffix path. If nodes \(p_i\) on the original suffix path already had transitions via \(c\), then the new suffix path will inevitably pass through the nodes reached by these transitions, so we can directly reuse the existing nodes. The new suffix path has exactly one completely new node \(q_0\), which accepts transitions from those starting nodes on the original suffix path that lacked transitions via \(c\).
Besides these obvious facts, we can also notice that the original node \(q_1\) has been duplicated, or rather split into two nodes \(q'_1\rightarrow q_1''\). This is because the new suffix path only partially overlaps with the existing path: among the strings corresponding to the original node \(q_1\), only the shorter ones (those reachable from nodes \(p_2\) and \(p_3\)) appear on the new suffix path, while the longer ones (those reachable from node \(p_1'\)) do not appear on the new suffix path. Therefore, the new suffix path can only pass through part of node \(q_1\), which must split into two nodes to represent this situation. For the same reason, as explained earlier, subsequent nodes \(q_2\) and \(q_3\) cannot be reached from nodes not on the suffix path of \(p_0\), so all strings corresponding to these nodes will appear on the new suffix path, and no splitting is needed.
From the perspective of the meaning of states in SAM, each state is an \(\operatorname{endpos}\) set. Suppose the new ending position added when extending the string is \(i\). Then the new node \(q_0\) is the set \(\{i\}\), while the split nodes \(q_1'\) and \(q_1''\) correspond to sets \(\operatorname{endpos}(q_1)\) and \(\operatorname{endpos}(q_1)\cup\{i\}\), respectively. Subsequent nodes \(q_2\) and \(q_3\) actually have \(i\) added to their original \(\operatorname{endpos}\) sets. That is, although \(q_2\) and \(q_3\) and their related transitions do not change, their corresponding \(\operatorname{endpos}\) sets indeed expand.
The above describes the most complex and general situation (i.e., Case 3 below). In practice, node \(p'_1\) may not exist, so no splitting is needed (i.e., Case 2 below). To determine this, we only need to check whether \(\operatorname{longest}(q_1)=\operatorname{longest}(p_2)+c\), i.e., \(\operatorname{len}(q_1)=\operatorname{len}(p_2)+1\). It is also possible that none of the nodes on the suffix path of \(p_0\) have a transition via \(c\); in that case, we only need to create \(q_0\) (i.e., Case 1 below).
With the idea of adding suffix paths in mind, let's now discuss the specific steps of incremental construction.
Process
To ensure linear space complexity, we will only store the values of \(\operatorname{len}\) and \(\operatorname{link}\) and the transition list for each state. We will not mark terminal states (but we will later show how to assign these marks after constructing the SAM).
Initially, SAM contains only one state \(t_0\), numbered \(0\) (other states are numbered \(1,2,\ldots\)). For convenience, for state \(t_0\) we set \(\operatorname{len}(t_0)=0\), \(\operatorname{link}(t_0)=-1\) (where \(-1\) denotes a virtual state).
Now, we only need to implement the process of adding a character \(c\) to the current string. The algorithm proceeds as follows:
SAM Incremental Construction Process
- Let \(\textit{last}\) be the state corresponding to the entire string before adding character \(c\) (initially we set \(\textit{last}=0\), and update \(\textit{last}\) in the last step of the algorithm).
- Create a new state \(\textit{cur}\), and set \(\operatorname{len}(\textit{cur})\) to \(\operatorname{len}(\textit{last})+1\). At this point, the value of \(\operatorname{link}(\textit{cur})\) is unknown.
- Now we proceed as follows: Starting from state \(\textit{last}\), if the current state does not have a transition labeled with character \(c\), we add a transition via \(c\) to state \(\textit{cur}\), and move the current state along the suffix link. If we encounter a state that already has a transition via \(c\), we stop and mark this state as \(p\).
- Case 1: If no such state \(p\) is found, we reach the virtual state \(-1\). We set \(\operatorname{link}(\textit{cur})\) to \(0\) and exit.
- Suppose we find a state \(p\) that has a transition via \(c\). We denote the state reached by this transition as \(q\). At this point, either \(\operatorname{len}(p)+1=\operatorname{len}(q)\), or \(\operatorname{len}(p)+1<\operatorname{len}(q)\).
- Case 2: If \(\operatorname{len}(p)+1=\operatorname{len}(q)\), we simply set \(\operatorname{link}(\textit{cur})\) to \(q\) and exit.
-
Case 3: Otherwise, things become more complicated, and we need to clone state \(q\): We create a new state \(\textit{clone}\), copying all information from \(q\) except \(\operatorname{len}\) (suffix link and transitions). We set \(\operatorname{len}(\textit{clone})\) to \(\operatorname{len}(p)+1\).
After cloning, we set the suffix link of \(\textit{cur}\) to \(\textit{clone}\), and also set the suffix link of \(q\) to \(\textit{clone}\).
Finally, we need to walk back along suffix links from state \(p\). For each state encountered that has a transition pointing to state \(q\), we redirect that transition to point to state \(\textit{clone}\).
-
After handling any of the three cases, we update \(\textit{last}\) to state \(\textit{cur}\).
If we also want to know which states are terminal states and which are not, we can find all terminal states after constructing the complete SAM for string \(s\). To do this, we start from the state corresponding to the entire string (stored in variable \(\textit{last}\)) and traverse its suffix links until we reach the initial state. We mark all states visited as terminal states. It is easy to see that this accurately marks all suffixes of string \(s\), and these states are terminal states.
Since we create only one or two new states for each character of \(s\), SAM contains only a linear number of states. The linear number of transitions and the overall linear runtime of the algorithm are not yet clarified and will be explained later.
Explanation
We explain each step of the algorithm in detail and justify its correctness.
Detailed Explanation of the Algorithm
-
A transition \((p,q)\) is called continuous if \(\operatorname{len}(p)+1=\operatorname{len}(q)\). Otherwise, when \(\operatorname{len}(p)+1<\operatorname{len}(q)\), the transition is called non-continuous.
From the algorithm description, continuous and non-continuous transitions are handled differently. Continuous transitions are fixed and will not be changed. In contrast, when inserting a new character into the string, non-continuous transitions may change (the endpoints of the transition edge may change).
-
To avoid ambiguity, we denote the string before inserting the current character \(c\) into SAM as \(s\).
- The algorithm starts by creating a new state \(\textit{cur}\), corresponding to the entire string \(s+c\). The reason for creating a new node is clear. At the same time, we create a new character and a new equivalence class.
-
After creating a new state, we move from state \(\textit{last}\) (corresponding to the entire string \(s\)) along suffix links. For each state we pass, we attempt to add a transition via character \(c\) to the new state \(\textit{cur}\).
However, we can only add transitions that do not conflict with existing ones. Therefore, we must stop as soon as we find an existing transition via \(c\).
-
The simplest case is when we reach the virtual state \(-1\), meaning we have added transitions via \(c\) for all suffixes of \(s\). This also means character \(c\) never appeared in string \(s\). Therefore, the suffix link of \(\textit{cur}\) is state \(0\).
-
In the second case, we find an existing transition \((p,q)\). This means we are trying to add a string \(x+c\) that already exists (where \(x\) is a suffix of \(s\), and string \(x+c\) already appears as a substring of \(s\)). Since we assume the automaton for string \(s\) is correctly constructed, we should not add a new transition here.
However, the difficulty is: which state should the suffix link from \(\textit{cur}\) connect to? We need to connect the suffix link to a state whose longest string is exactly \(x+c\), i.e., whose \(\operatorname{len}\) should be \(\operatorname{len}(p)+1\). However, such a state might not exist, i.e., \(\operatorname{len}(q)>\operatorname{len}(p)+1\). In this case, we must create such a state by splitting state \(q\).
-
Of course, if transition \((p,\,q)\) is continuous, then \(\operatorname{len}(q)=\operatorname{len}(p)+1\). In this case, everything is simple. We just set the suffix link of \(\textit{cur}\) to state \(q\).
-
Otherwise, the transition is non-continuous, i.e., \(\operatorname{len}(q)>\operatorname{len}(p)+1\), meaning state \(q\) corresponds not only to the suffix \(s+c\) of length \(\operatorname{len}(p)+1\) but also to longer substrings of \(s\). We have no choice but to split state \(q\) into two substates, with the first substate having length \(\operatorname{len}(p)+1\).
How do we split a state? We clone state \(q\) to create a state \(\textit{clone}\), and set \(\operatorname{len}(\textit{clone})\) to \(\operatorname{len}(p)+1\). Since we do not want to change paths passing through \(q\), we copy all transitions from \(q\) to \(\textit{clone}\). We also set the suffix link of \(\textit{clone}\) to the target of \(q\)'s suffix link, and set \(q\)'s suffix link to \(\textit{clone}\).
After splitting, we set the suffix link of \(\textit{cur}\) to \(\textit{clone}\).
The final step is to redirect some transitions originally pointing to \(q\) to point to \(\textit{clone}\). Which transitions need to be redirected? Only those transitions corresponding to all strings \(w+c\) (where \(w\) is the longest string corresponding to state \(p\)). That is, we need to continue moving along suffix links from node \(p\) until the virtual state \(-1\), or until the current state's transition via \(c\) no longer points to state \(q\).
Linear Time Complexity
We assume the alphabet size is constant, meaning operations like searching for a transition by a character, adding a transition, and finding the next transition all take \(O(1)\) time. If we store the transitions of each node as an array of length \(\left|\Sigma\right|\) (for fast lookup of transitions by label) and a dynamic list (for fast traversal of all available transitions), trading space for time, then the algorithm's time complexity2 is \(O(n)\), and space complexity is \(O(n\left|\Sigma\right|)\).
Proof
If we consider various parts of the algorithm, three places have non-obvious linear time complexity:
- First, traversing all suffix links of state \(\textit{last}\) to add transitions via \(c\).
- Second, copying transitions when state \(q\) is cloned to a new state \(\textit{clone}\).
- Third, modifying transitions pointing to \(q\) to reconnect them to \(\textit{clone}\).
We use the fact that the size of SAM (number of states and transitions) is linear (the proof for the linear number of states is the algorithm itself; the proof for the linear number of transitions will be given after implementing the algorithm).
Therefore, the total complexity of the first and second parts is clearly linear, because each operation amortized adds only one new transition to the automaton.
We still need to estimate the total complexity for the third part, where we redirect transitions originally pointing to \(q\) to \(\textit{clone}\). Let \(v=\operatorname{longest}(p)\), which is a suffix of string \(s\). Each iteration reduces the length of \(v\), so the starting position of \(v\) as a suffix of \(s\) must move backward. Therefore, the number of times \(p\) moves along suffix links in the loop does not exceed the distance the starting position of \(v\) as a suffix of \(s\) moves backward. Since \(p\) must move at least once to terminate the loop, and \(p\) is at least the result of moving \(\textit{last}\) along the suffix link once, when the loop terminates, the starting position of \(v\) as a suffix of \(s\) is no earlier than the starting position of string \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{last}))\). Moreover, when the loop terminates, the starting position of string \(v\) as a suffix of \(s\) is exactly the starting position of \(v+c\) as a suffix of \(s+c\), and as a suffix of \(s+c\), string \(v+c\) is exactly string \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{cur}))\). Since \(\textit{cur}\) is the updated value of \(\textit{last}\), the number of moves in the loop does not exceed the distance the starting position of \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{last}))\) as a suffix of the current string moves backward before and after the update, plus one (the necessary move to terminate the loop).
Because the starting position of string \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{last}))\) as a suffix of the current string increases monotonically3 throughout the SAM construction, its total movement distance does not exceed \(n\). This shows that the number of iterations in the loop redirecting transitions to \(q\) is at most \(2n\). This is exactly what we need to prove.
Of course, if the alphabet size is not constant, SAM's time complexity is not linear. Transitions from a node need to be stored in a balanced tree supporting fast query and insertion. Therefore, if we denote \(\Sigma\) as the alphabet and \(\left|\Sigma\right|\) as its size, the asymptotic time complexity of the algorithm is \(O(n\log\left|\Sigma\right|)\), and space complexity is \(O(n)\).
Implementation
First, we implement a data structure storing all information about a transition. If needed, you can add a terminal flag or other information here. We will use a map to store the list of transitions, allowing us to process the entire string with total \(O(n)\) space complexity and \(O(n\log\left|\Sigma\right|)\) time complexity. Of course, when the alphabet size is a small constant \(K\) (like 26), it is more convenient to declare next as int[K].
1 2 3 4 | |
SAM itself will be stored in an array of state structs. We record the current size of the automaton sz and the variable last, the state corresponding to the entire current string.
1 2 3 | |
We define a function to initialize SAM (create a SAM with only the initial state).
1 2 3 4 5 6 | |
Finally, we give the implementation of the main function: add a character to the end of the current string, constructing the automaton accordingly.
Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 | |
As mentioned earlier, if you trade memory for time (space complexity \(O(n\left|\Sigma\right|)\), where \(\left|\Sigma\right|\) is the alphabet size), you can construct SAM for any alphabet size in \(O(n)\) time2. However, this requires storing for each state an array of size \(\left|\Sigma\right|\) (for fast character-to-transition lookup) and a list of all available transitions (for fast traversal of all available transitions).
More Properties
Number of States
For a string \(s\) of length \(n\), the number of states in its SAM does not exceed \(2n-1\) (assuming \(n\ge 2\)).
Proof
The algorithm itself proves this claim. Initially, the automaton has one state. The first and second iterations create only one node each. The remaining \(n-2\) steps create at most \(2\) states each.
However, we can also prove this bound without relying on the algorithm. Recall that the number of states equals the number of distinct \(\operatorname{endpos}\) sets. These \(\operatorname{endpos}\) sets form a tree (a parent's \(\operatorname{endpos}\) set contains its child's \(\operatorname{endpos}\) set). Consider slightly modifying this tree: whenever there is an internal node with only one child (meaning the child's set misses at least one position from its parent's set), we create a new child containing those missing positions. Finally, we obtain a tree where every internal node has degree greater than one, and the number of leaves does not exceed \(n\). Such a tree has at most \(2n-1\) nodes. Therefore, the original number of distinct \(\operatorname{endpos}\) sets also does not exceed \(2n-1\).
The string \(\texttt{abbb} \cdots \texttt{bbb}\) achieves this upper bound: from the third iteration onward, each iteration splits a state, eventually producing exactly \(2n-1\) states.
Number of Transitions
For a string \(s\) of length \(n\), the number of transitions in its SAM does not exceed \(3n-4\) (assuming \(n\ge 3\)).
Proof
We first estimate the number of continuous transitions. Consider the spanning tree formed by the longest paths from state \(t_0\) to all states. The spanning tree contains only continuous edges, so the number is less than the number of states, i.e., the number of edges does not exceed \(2n-2\).
Now we estimate the number of non-continuous transitions. Let \((p,\,q)\) be a non-continuous transition with character \(c\). Take its corresponding string \(u+c+w\), where string \(u\) corresponds to the longest path from the initial state to \(p\), and \(w\) corresponds to the longest path from \(q\) to any terminal state. On one hand, each incomplete string corresponds to a distinct string of the form \(u+c+w\) (because strings \(u\) and \(w\) consist only of complete transitions). On the other hand, by the definition of terminal states, each string of the form \(u+c+w\) is a suffix of the entire string \(s\). Since \(s\) has only \(n\) non-empty suffixes, and strings of the form \(u+c+w\) do not contain \(s\) (because the entire string consists only of complete transitions), the total number of non-continuous transitions does not exceed \(n-1\).
Adding these two estimates gives an upper bound of \(3n-3\). However, the maximum number of states occurs only in cases like \(\texttt{abbb} \cdots \texttt{bbb}\), where the number of transitions is clearly less than \(3n-3\).
Therefore, we can obtain a tighter upper bound for the number of transitions in SAM: \(3n-4\). The string \(\texttt{abbb} \cdots \texttt{bbbc}\) achieves this bound.
Suffix Link Tree
Although SAM is constructed to obtain information about its states and transitions, the suffix link \(\operatorname{link}\) and the length \(\operatorname{len}\) of the longest substring corresponding to each state recorded during construction are often more important in applications than SAM's transitions, and can even be used separately without the transitions.
During SAM construction, the value of \(\textit{last}\) is updated. It corresponds to the string before (or after) each character addition, i.e., all prefixes of the entire string \(s\). Denote the state corresponding to the \(i\)-th prefix as \(v_i\), giving \(v_0,v_1,\cdots,v_{n-1}\) total \(n\) states. Additionally, define the initial state \(t_0\) as \(v_{-1}\), corresponding to the empty prefix. These states are temporarily called "prefix nodes".
As mentioned in Lemma 4, all states and all suffix links form a root-directed tree rooted at \(t_0\). This tree is also called the suffix link tree (domestic OI contestants often call it the parent tree). It records information about all suffixes of all prefixes of the string, i.e., information about all substrings.
The suffix link tree has the following properties:
- The string corresponding to an ancestor node is always a suffix of the string corresponding to a descendant node.
- The \(\operatorname{endpos}\) set at each node is the set of indices \(i\) of all "prefix nodes" \(v_i\) in its subtree.
- The \(\operatorname{endpos}\) set of an ancestor node always strictly contains that of a descendant node.
- The \(\operatorname{len}\) value at each node is the length of the longest common suffix of all prefixes corresponding to the "prefix nodes" \(v_i\) in its subtree.
- Except for the root \(t_0\), the number of distinct substrings corresponding to each node is its \(\operatorname{len}\) value minus its parent's \(\operatorname{len}\) value, i.e., \(\operatorname{len}(v)-\operatorname{len}(\operatorname{link}(v))\).
These properties have many applications. For example, the longest common suffix of the \(i\)-th and \(j\)-th prefixes corresponds to the longest string of the LCA of \(v_i\) and \(v_j\).
Finally, the suffix link tree built for string \(s\) has the same structure as the suffix tree built for its reverse \(s_R\). This is often used for offline suffix tree construction.
Applications
Now let's look at some problems that can be solved using SAM. For simplicity, assume the alphabet size \(k\) is constant. This allows us to consider adding a character and traversal as constant-time operations.
Checking if a String Appears
Problem
Given a text string \(T\) and multiple pattern strings \(P\), check whether string \(P\) appears as a substring of \(T\).
Solution
We construct the suffix automaton for text string \(T\) in \(O(\left|T\right|)\) time. To check if pattern string \(P\) appears in \(T\), we start from \(t_0\) and follow transitions according to the characters of \(P\). If at some point we cannot proceed, then pattern \(P\) is not a substring of \(T\). If we can process the entire string \(P\) this way, then the pattern appears in \(T\).
For each string \(P\), the time complexity is \(O(\left|P\right|)\). Additionally, this algorithm finds the maximum prefix length of pattern \(P\) that appears in the text.
Number of Distinct Substrings
Problem
Given a string \(S\), count the number of distinct substrings.
Solution 1
Construct the suffix automaton for string \(S\).
Each substring of \(S\) corresponds to some path in the automaton. Therefore, the number of distinct substrings equals the number of distinct paths starting from \(t_0\).
Considering SAM is a directed acyclic graph, the number of distinct paths can be computed via dynamic programming. Let \(d_{v}\) be the number of paths starting from state \(v\) (including zero-length paths). Then we have the recurrence:
That is, \(d_{v}\) equals the sum over all transitions from \(v\), where \((v,w,c)\) denotes a transition from \(v\) via \(c\) to \(w\) in SAM.
So the number of distinct substrings is \(d_{t_0}-1\) (subtracting the empty substring).
Total time complexity: \(O(\left|S\right|)\).
Solution 2
Another method is to use the information from the suffix link tree after constructing SAM. The number of substrings corresponding to each node is \(\operatorname{len}(v)-\operatorname{len}(\operatorname{link}(v))\). Summing over all automaton nodes gives the answer.
Total time complexity remains: \(O(\left|S\right|)\).
Example problems: 【Template】Suffix Automaton, SDOI2016 Generating Magic Spell
Total Length of All Distinct Substrings
Problem
Given a string \(S\), compute the total length of all distinct substrings.
Solution 1
This problem is similar to the previous one, but now we need to consider dynamic programming in two parts: the number of distinct substrings \(d_{v}\) and their total length \(ans_{v}\).
We already described how to compute \(d_{v}\) in the previous problem. The value of \(ans_{v}\) can be computed via the recurrence:
We take the answer from each adjacent node \(w\) and add \(d_{w}\) (because substrings starting from state \(v\) gain one more character).
The algorithm's time complexity is still \(O(\left|S\right|)\).
Solution 2
Again, we can use the suffix link tree information. The sum of lengths of all suffixes of the longest substring at each node is
Subtracting the corresponding value of its \(\operatorname{link}\) node gives the net contribution of that node. Summing over all automaton nodes gives the answer.
Total time complexity remains: \(O(\left|S\right|)\).
K-th Lexicographically Largest Substring
Problem
Given a string \(S\). Multiple queries, each query gives a number \(K_i\), find the \(K_i\)-th lexicographically largest substring among all substrings of \(S\).
Solution
The solution idea can be developed from the previous problems. The \(k\)-th lexicographically largest substring corresponds to the \(k\)-th lexicographically largest path in SAM. Therefore, after computing the number of paths from each state, we can easily find the \(k\)-th largest path starting from the root of SAM.
Preprocessing time complexity is \(O(\left|S\right|)\). Single query complexity is \(O(\left|ans\right|\cdot\left|\Sigma\right|)\) (where \(ans\) is the query answer, \(\left|\Sigma\right|\) is the alphabet size).
Note
Although this is a classic suffix automaton problem, due to lexicographic ordering, suffix array is actually more convenient.
Example problems: SPOJ - SUBLEX, TJOI2015 String Theory
Minimum Cyclic Shift
Problem
Given a string \(S\). Find the lexicographically smallest cyclic shift.
Solution
It is easy to see that string \(S+S\) contains all cyclic shifts of \(S\) as substrings.
So the problem reduces to finding the smallest path of length \(\left|S\right|\) in the suffix automaton of \(S+S\). This can be done trivially: starting from the initial state, greedily visit the smallest character.
Total time complexity is \(O(\left|S\right|)\).
Occurrence Count
Problem
For a given text string \(T\), multiple queries, each query gives a pattern string \(P\), answer how many times pattern \(P\) appears as a substring in string \(T\).
Solution 1
Using the suffix link tree information, perform DFS to precompute the size of the \(\operatorname{endpos}\) set for each node.
All "prefix nodes" initially have size \(1\), and non-"prefix nodes" initially have size \(0\). Then, when backtracking upward along suffix links, each parent's size is increased by the sizes of all its children (do not forget the parent's own initial value). The resulting value at each node is the size of its \(\operatorname{endpos}\) set. The reason we can directly add sizes from different children is that the same \(v_i\) appears in only one subtree, so addition does not double-count.
When querying, find the node corresponding to pattern \(P\) in the automaton. If it exists, the answer is the size of its \(\operatorname{endpos}\) set; otherwise, the answer is \(0\).
Preprocessing time complexity is \(O(|T|)\). Single query time complexity is \(O(|P|)\).
Solution 2
Construct the suffix automaton for text string \(T\).
Next, preprocess: for each state \(v\) in the automaton, precompute \(cnt_{v}\), which equals the size of \(\operatorname{endpos}(v)\). In fact, all substrings corresponding to the same state \(v\) appear the same number of times in \(T\), which equals the number of positions in set \(\operatorname{endpos}\).
However, we cannot explicitly construct \(\operatorname{endpos}\) sets, so we only consider their sizes \(cnt\).
To compute these values, we do the following. For each state that is not created by cloning (and is not the initial state \(t_0\)), we initialize its \(cnt\) to 1. Then we traverse all states in descending order of their \(\operatorname{len}\), and add the current \(cnt_{v}\) to the state pointed by its suffix link:
This yields correct answers for all states.
Why is this correct? States not created by cloning are exactly \(\left|T\right|\) in number, and the first \(i\) of them are created when inserting the first \(i\) characters. Therefore, for each such state, we compute the number of positions it corresponds to when it is processed. Hence we initialize \(cnt\) of these states to \(1\), and others to \(0\).
Next, for each \(v\) we perform: \(cnt_{\operatorname{link}(v)}+=cnt_{v}\). The meaning is: if a string \(v\) appears \(cnt_{v}\) times, then all its suffixes also end at exactly the same positions, i.e., also appear \(cnt_{v}\) times.
Why don't we double-count positions in this process? Because we only add a state's positions to one other state, so a state cannot have its positions added to another state in two different ways.
Thus, we can compute \(cnt\) for all states in \(O(\left|T\right|)\).
Finally, answering a query only requires looking up \(cnt_{t}\), where \(t\) is the state corresponding to the pattern string. If the pattern does not exist, the answer is \(0\). Single query time complexity is \(O(\left|P\right|)\).
First Occurrence Position
Problem
Given a text string \(T\), multiple queries. Each query asks for the first occurrence position (starting position) of string \(P\) in \(T\).
Solution 1
Using the suffix link tree information, perform DFS to precompute the minimum value in the \(\operatorname{endpos}\) set for each node.
All "prefix nodes" \(v_i\) initially have value \(i\), and non-"prefix nodes" initially have value \(\infty\). Then, when backtracking upward along suffix links, each parent's value is compared with all its children's values, taking the minimum (do not forget the parent's own initial value). The resulting value at each node is the minimum in its \(\operatorname{endpos}\) set.
When querying, find the node corresponding to pattern \(P\) in the automaton. If it exists, the answer is that value minus \(|P|-1\); otherwise, the answer does not exist.
Preprocessing time complexity is \(O(|T|)\). Single query time complexity is \(O(|P|)\).
Solution 2
We construct a suffix automaton. For all states in SAM, precompute position \(\operatorname{firstpos}\). That is, for each state \(v\) we want to find the first ending position \(\operatorname{firstpos}[v]\) where this state appears. In other words, we want to find the smallest element in each \(\operatorname{endpos}\) set (we cannot explicitly maintain all \(\operatorname{endpos}\) sets).
To maintain \(\operatorname{firstpos}\), we extend the function sam_extend(). When creating a new state \(\textit{cur}\), we set:
When cloning node \(q\) to \(\textit{clone}\), we set:
(Because the only other option \(\operatorname{firstpos}(\textit{cur})\) is obviously too large).
Then the query answer is \(\operatorname{firstpos}(t)-\left|P\right|+1\), where \(t\) is the state corresponding to string \(P\). A single query takes \(O(\left|P\right|)\) time.
All Occurrence Positions
Problem
Problem same as above, but this time need to output all positions where pattern \(P\) appears in text \(T\).
Solution 1
After finding the node corresponding to pattern \(P\), use the suffix link tree information, traverse the subtree, and output whenever a terminal node is found.
Single query complexity is \(O(|P|)+O(\textit{answer}(P))\), where \(\textit{answer}(P)\) is the answer for this query. Following the proof of linear number of states, the subtree size in the suffix link tree does not exceed twice the size of the node's \(\operatorname{endpos}\) set, so traversing the subtree takes \(O(\textit{answer}(P))\) time.
Solution 2
We still construct the suffix automaton for text string \(T\). Similar to the previous problem, we compute \(\operatorname{firstpos}\) for all states.
If \(t\) is the state corresponding to pattern \(P\), obviously \(\operatorname{firstpos}(t)\) is one answer. We have found the state corresponding to \(P\) in the automaton. What other positions do we need? Those corresponding to strings that have \(P\) as a suffix. In other words, we need to find all states reachable from state \(t\) via reverse suffix links.
Therefore, to solve this problem, we need to store for each state a list of reverse suffix links pointing to it. The answer includes \(\operatorname{firstpos}\) values for all states we can find by DFS or BFS from state \(t\) using only reverse suffix links.
Preprocessing complexity is \(O(|T|)\). Single query complexity is \(O(|P|+\textit{answer}(P))\).
We will not visit a state twice (because each state has only one suffix link pointing to it, so there cannot be two different paths to the same state).
We only need to consider two different states possibly having the same \(\operatorname{firstpos}\) value. This happens only when one state is cloned from another. However, this does not affect complexity analysis. Following the proof of linear number of states, the number of such states with \(P\) as a suffix does not exceed \(2\textit{answer}(P)\).
Moreover, we can remove duplicate positions by ignoring \(\operatorname{firstpos}\) values of cloned states. In fact, if a state is reachable via a cloned state, it is also reachable via the original state. Therefore, if we record a flag is_clone for each state indicating whether it was cloned, we can simply ignore cloned states and output \(\operatorname{firstpos}\) of all other states.
Here is a rough implementation:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 | |
Shortest Non-appearing String
Problem
Given a string \(S\) and a specific alphabet, find the shortest string that does not appear in \(S\).
Solution
We perform dynamic programming on the suffix automaton of string \(S\).
Assume we have processed part of a substring and are currently at state \(v\). We want to find the minimum number of characters to add to get a non-existing transition, denoted \(d_v\) for node \(v\).
Computing \(d_{v}\) is simple. If there is no transition using at least one character from the alphabet, then \(d_{v}=1\). Otherwise, adding one character is insufficient; we need the minimum over all transitions:
The answer is \(d_{t_0}\), and the string can be reconstructed backward using the computed array \(d\).
Longest Common Substring of Two Strings
Problem
Given two strings \(S\) and \(T\), find the longest common substring, defined as a string \(X\) that appears as a substring in both \(S\) and \(T\).
Solution
We construct the suffix automaton for string \(S\).
Now we process string \(T\). For each prefix, we find the longest suffix of this prefix that appears in \(S\). In other words, for each position in \(T\), we want to find the length of the longest common substring ending at that position.
To achieve this, we use two variables: current state \(v\) and current length \(l\). These describe the currently matched part: its length and corresponding state.
Initially \(v=t_0\) and \(l=0\), i.e., matching the empty string.
Now we describe how to add a character \(T_{i}\) and recompute the answer:
- If there is a transition from \(v\) via character \(T_{i}\), we simply follow the transition and increment \(l\) by one.
-
If no such transition exists, we need to shorten the current match, meaning we follow the suffix link:
\[ v=\operatorname{link}(v) \]At the same time, we need to shorten the current length. Obviously we set \(l\) to \(\operatorname{len}(v)\), because after following this suffix link, the longest string corresponding to the reached state is a substring.
-
If still no transition via this character exists, we repeat following suffix links and decreasing \(l\) until we find a transition or reach the virtual state \(-1\) (meaning character \(T_{i}\) does not appear in \(S\) at all, so we set \(v=l=0\)).
The answer is the maximum \(l\) over all steps.
This part takes \(O(\left|T\right|)\) time, because each move either increases \(l\) by one or moves along suffix links several times, each time decreasing \(l\).
Code implementation:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 | |
Example problem: SPOJ Longest Common Substring
Longest Common Substring of Multiple Strings
Problem
Given \(k\) strings \(S_i\). Find their longest common substring, i.e., a string \(X\) that appears as a substring in each string.
Solution 1
Concatenate all strings into a longer string \(T\), separating each string with a special character \(D_i\) (one character per string):
Then construct the suffix automaton for string \(T\).
Now we need to find a string in the automaton that exists in all strings \(S_i\), using the added special characters. If \(S_j\) contains a substring \(X\), then from the node \(t\) corresponding to substring \(X\), there must be a path to \(D_j\) that does not pass through any other special characters \(D_1,\cdots,D_{j-1},D_{j+1},\cdots,D_k\). For a common substring \(X\), such a path must exist for each special character \(D_j\).
Therefore, we need to compute reachability: for each state and each character \(D_i\), whether such a path exists. This can be easily computed via DFS or BFS and dynamic programming. After that, the answer is the longest \(\operatorname{longest}(v)\) among all states \(v\) that can reach all special characters.
Solution 2
Assume the shortest string is \(S_1\), and construct SAM for it. Using the algorithm for the longest common substring of two strings, compute the longest common substring length between each remaining string \(S_j\) and \(S_1\). During matching, each time a character from \(S_j\) is added, we move accordingly on SAM. Therefore, we can directly record during matching the longest substring length that each SAM state can match for \(S_j\).
During matching, when we match to a state in SAM, we also match all its ancestors in the suffix link tree, but the matching length information for ancestors is not updated. So after finishing matching string \(S_j\), we need to update bottom-up along suffix links, propagating the longest matched length from child to parent. Note that the parent's recorded longest match length cannot exceed its own \(\operatorname{len}\) value. This gives the actual longest substring of \(S_j\) that each state in \(S_1\)'s SAM can match.
Finally, we only need to match each \(S_2,\cdots,S_k\) once, then take the minimum of the actual matched lengths recorded for each SAM state across all strings, giving the longest common substring length that each state can match for \(S_2,\cdots,S_k\). Then, traverse all SAM states and take the maximum as the longest common substring length of these \(k\) strings.
The algorithm time complexity is \(O(\sum_i |S_i|)\). Although \(S_1\)'s SAM is traversed \(k\) times, because \(|S_1|\) is the smallest, \(k|S_1|\le \sum_i |S_i|\), so the main complexity is still from matching all substrings.
Example problem: SPOJ Longest Common Substring II
Exercises
- 【Template】Suffix Automaton
- SDOI2016 Generating Magic Spell
- SPOJ - SUBLEX
- TJOI2015 String Theory
- SPOJ Longest Common Substring
- SPOJ Longest Common Substring II
- Codeforces 1037H Security
- Codeforces 666E Forensic Examination
- HDU4416 Good Article Good sentence
- HDU4436 str2int
- HDU6583 Typewriter
- Codeforces 235C Cyclical Quest
- CTSC2012 Familiar Articles
- NOI2018 Your Name
References
We first give some early literature related to SAM:
- A. Blumer, J. Blumer, A. Ehrenfeucht, D. Haussler, R. McConnell. Linear Size Finite Automata for the Set of All Subwords of a Word. An Outline of Results. [1983]
- A. Blumer, J. Blumer, A. Ehrenfeucht, D. Haussler. The Smallest Automaton Recognizing the Subwords of a Text. [1984]
- Maxime Crochemore. Optimal Factor Transducers. [1985]
- Maxime Crochemore. Transducers and Repetitions. [1986]
- A. Nerode. Linear automaton transformations. [1958]
Additionally, this topic can be found in more recent resources and many books on string algorithms:
- Maxime Crochemore, Rytter Wowjcieh. Jewels of Stringology. [2002]
- Bill Smyth. Computing Patterns in Strings. [2003]
- Bill Smith. Methods and algorithms of calculations on lines. [2006]
Other references:
- 《Suffix Automaton》, Chen Lijie.
- 《Extension of Suffix Automaton on Trie》, Liu Yanyi.
- 《Suffix Automaton and Its Applications》, Zhang Tianyang.
- https://www.cnblogs.com/zinthos/p/3899679.html
- https://codeforces.com/blog/entry/20861
- https://zhuanlan.zhihu.com/p/25948077
This page is mainly translated from the blog post Суффиксный автомат and its English translation Suffix Automaton. The Russian version copyright is Public Domain + Leave a Link; the English version copyright is CC-BY-SA 4.0.
-
The reason each state must correspond to an \(\operatorname{endpos}\) equivalence class is essentially the Myhill–Nerode theorem. Briefly, if two strings \(t\) and \(u\) have different \(\operatorname{endpos}\) sets, they cannot correspond to the same state in SAM: the paths from the same state to terminal states are always the same, meaning the way to reach the end of \(s\) by appending characters to \(t\) and \(u\) is the same, which implies \(t\) and \(u\) have the same ending positions in \(s\). Conversely, if two strings \(t\) and \(u\) have the same \(\operatorname{endpos}\) set, they can correspond to the same state in SAM. This works due to Nerode theorem's proof, not discussed here. However, this discussion at least convinces that putting strings with the same \(\operatorname{endpos}\) into the same state yields a minimal SAM, because further merging is impossible. ↩
-
If we do not use an additional list to record available transitions for the current state, but only store an array of all possible transitions (whether they exist) and copy directly when cloning nodes, then the time complexity is also \(O(n\left|\Sigma\right|)\). ↩↩
-
The main text does not explain here whether in Cases 1 and 2, the position of \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{last})))\) is also (weakly) monotonic increasing. Case 1 is easy to verify because after update, \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{last})))\) is the empty string, starting at the end of \(s\). In Case 2, the transition is continuous, meaning \(\operatorname{longest}(q) = \operatorname{longest}(p)+c\). However, adding a new character to the end of a substring only makes it harder to appear in the string. That is, when the suffix of \(\operatorname{longest}(p)\) of length \(\operatorname{len}(\operatorname{link}(p))\) has an \(\operatorname{endpos}\) set strictly containing \(\operatorname{endpos}(p)\), the suffix of \(\operatorname{longest}(q)\) of length \(\operatorname{len}(\operatorname{link}(p))+1\) may still have the same \(\operatorname{endpos}\) set as \(\operatorname{endpos}(q)\). Hence, \(\operatorname{len}(\operatorname{link}(q))<\operatorname{len}(\operatorname{link}(p))+1\), i.e., the starting position of \(\operatorname{longest}(\operatorname{link}(p))\) as a suffix of \(s\) is no later than the starting position of \(\operatorname{longest}(\operatorname{link}(q))\) as a suffix of \(s+c\). When we find a state \(p\) with a transition via \(c\), we must have moved at least once, meaning the starting position of \(\operatorname{longest}(\operatorname{link}(p))\) as a suffix of \(s\) is no earlier than the starting position of \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{last})))\) as a suffix of \(s\). Finally, \(\operatorname{longest}(\operatorname{link}(q))=\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{cur})))\). This shows that in Case 2, the position of \(\operatorname{longest}(\operatorname{link}(\operatorname{link}(\textit{last})))\) is also monotonic increasing. ↩
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用