Random Walk on Graph
This page introduces the problem of random walks on graphs. It mainly explores from three perspectives: grid graphs, sparse graphs, and general graphs, introduces various methods to solve such problems, and compares their advantages and disadvantages in addressing different issues.
Definition
Given a directed simple graph \(G=(V, E)(V=\{v_1, v_2, \cdots, v_{|V|}\})\), a starting point \(s \in V\), and an ending point \(t \in V\), each edge \(e=\left(x, y\right)\) has a positive weight \(w_e\), satisfying \(\forall x \in V \backslash\left\{t\right\}\), \(\sum_{\left(x, y\right) \in E} w_{\left(x, y\right)}=1\), and for any point \(x\), there exists a path from \(x\) to \(t\). A piece starts from the starting point, and each second, from the current point \(x\), it chooses an outgoing edge \(\left(x, y\right)\) with probability \(w_{(x, y)}\) and moves to \(y\), stopping upon reaching the endpoint. The expected time taken is required.
In fact, this problem can also be written in matrix form. Define matrix \(P\):
The required answer is:
where \(\left(P^k\right)_{s, t}\) represents the probability of reaching the endpoint for the first time after \(k\) steps. When the graph is finite and all points can reach the endpoint, it can be proven from the definition of \(P\) that all its eigenvalues are less than 1, so the answer must converge.
For convenience, unless otherwise specified, \(n\) refers to \(|V|\) and \(m\) refers to \(|E|\) on this page.
Additionally, on this page, a sparse graph refers to a graph where the number of edges is of the same order as the number of vertices.
Grid Graph
Example 1 Circles of Waiting
A piece is initially placed at \((0,0)\) in the Cartesian coordinate system. Each second, the piece moves randomly. Suppose it is currently at \((x, y)\), it has a probability \(p_1\) of moving to \((x-1, y)\), \(p_2\) to \((x, y-1)\), \(p_3\) to \((x+1, y)\), and \(p_4\) to \((x, y+1)\) in the next second. It is guaranteed that \(p_1+p_2+p_3+p_4=1\). Find the expected time for it to move to a position whose Euclidean distance from the origin is greater than \(R\). \(0 \leq R \leq 50\), \(p_1, p_2, p_3, p_4>0\), output the answer modulo \(10^9+7\).
Naive Approach
Let \(f(i, j)\) denote the expected time for the piece to move to a position with Euclidean distance greater than \(R\) from the origin when it is at \((i, j)\). The transition equation is:
Since the transitions do not have a topological order, Gaussian elimination is required. Time complexity is \(O\left(R^6\right)\), which cannot pass this problem.
Direct Elimination Method
Note that most coefficients in the equations to be eliminated are 0. During elimination, only positions with non-zero values need to be computed, which reduces complexity.
Consider the elimination process. Order the equations from top to bottom in the coordinate system, and within the same layer from left to right. Color the equations that have been eliminated as yellow, points adjacent to yellow points as green, and the remaining points as black, as shown below:
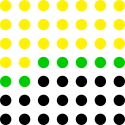
Next, eliminate the equation corresponding to the next green cell. In this equation, only the coefficients of variables corresponding to green cells and the first black cell below it may be non-zero; and only in the equations corresponding to the green cell and the first black cell below it, the coefficient of the variable corresponding to the current cell may be non-zero.
Note that there are only \(O(R)\) green cells, so the time complexity for eliminating a single equation is \(O\left(R^2\right)\). There are only \(O\left(R^2\right)\) equations in total, so the time complexity is reduced to \(O\left(R^4\right)\), which can pass this problem.
Pivot Method
There are \(O\left(R^2\right)\) equations and variables. If the scale can be reduced to \(O(R)\), then naive Gaussian elimination can pass.
Set the variable corresponding to the first cell in each row from left to right as a pivot, totaling \(2 R+1\) pivots. Try to express other variables as linear functions of these pivots. Consider column by column from left to right. For each cell \((i, j)\) in the current column, note that \(f(i, j), f(i-1, j), f(i, j-1), f(i, j+1)\) are all known linear functions of the pivots. Rearranging the transition equation:
Thus, we obtain the linear function representation of \(f(i+1, j)\) in terms of the pivots. If \((i+1, j)\) already has a Euclidean distance from the origin exceeding \(R\), we get an equation: \(f(i+1, j)=0\). Finally, we obtain \(2 R+1\) equations, and Gaussian elimination can be performed on these equations.
In the stage of deriving linear functions of the pivots, there are \(O\left(R^2\right)\) variables, and deriving a single variable takes \(O(R)\) time; afterward, the problem scale is reduced to \(O(R)\). The time complexity of both parts is \(O\left(R^3\right)\), and the total time complexity is also \(O\left(R^3\right)\), which can pass this problem.
Comparison of the Two Approaches
Below is a comparison of the two approaches from various aspects:
In terms of time complexity, the worst-case time complexity of the pivot method on grid graphs is \(O(n \sqrt{n})\) (when the grid graph's length and width are both \(O(\sqrt{n})\)), while the worst-case time complexity of the direct elimination method on grid graphs is \(O\left(n^2\right)\). The pivot method is better.
In terms of precision, for problems requiring real number calculations instead of modulo operations, the direct elimination method has better precision than the pivot method.
In terms of applicability, the two approaches are suitable for different scenarios.
When there are obstacles in the grid graph or the probability of taking certain edges is \(0\), the pivot method needs to add a pivot for each obstacle or edge with probability \(0\). When the number of obstacles or edges with probability \(0\) exceeds \(O(R)\), the time complexity of the pivot method increases, while the time complexity of the direct elimination method remains unchanged.
However, the pivot method can also perform elimination on transition equations similar to grid graphs, such as \(f(i, j)=p_1 f(i+1, j)+p_2 f(i, j+1)+p_3 f(\operatorname{pre}(i, j))+1\), where \(\operatorname{pre}(i, j)=(x, y)(x \leq i, y \leq j)\) is a given value, and the complexity analysis of the direct elimination method does not apply in this model.
Additionally, the calculation of the determinant of the adjacency matrix of a grid graph cannot use the pivot method; only the direct elimination method can be used to optimize time complexity.
In summary, both approaches have their own strengths, and the choice should be based on the specific problem.
Sparse Graph
Example 2 Expected Value
Given a simple undirected connected sparse graph \(G=(V, E)\), a piece starts at \(v_1\). Each second, the piece chooses an edge connected to the current point with equal probability and moves to the point pointed by the outgoing edge. Find the expected time to reach \(v_n\). \(n \leq 2000\), output the answer modulo \(p\), where \(p\) is a randomly generated prime number in the interval \(\left[10^9, 1.01 \times 10^9\right]\).
Basic Knowledge
Definition 4.1. All polynomials \(p(λ)\) satisfying \(p(A) = 0\) are called annihilating polynomials of matrix \(A\).
Definition 4.2. Let \(I_n\) denote the \(n \times n\) identity matrix. The characteristic polynomial of an \(n \times n\) matrix \(A\) is defined as \(p(λ) = \det(λI_n - A)\), where \(\det\) denotes the determinant of a matrix. It is not hard to see that the degree of the characteristic polynomial of an \(n \times n\) matrix \(A\) is at most \(n\).
Theorem 4.2. (Cayley–Hamilton theorem) The characteristic polynomial of any matrix is its annihilating polynomial.
Therefore, the degree of the minimal annihilating polynomial of an \(n \times n\) matrix is also at most \(n\).
Solving the Original Problem
Note that the expected time \(E(t)=\sum_{i\geq0}\Pr[t>i]\). If we can find the probability of not having ended after \(i\) steps, summing over all \(i ≥ 0\) gives the answer.
Let \(f(i, j)\) denote the probability of having taken \(i\) steps, currently staying at \(j\), and never having reached \(n\). Then:
where \(\deg_k\) denotes the degree of \(k\).
Note that the transition of \(f\) is independent of \(i\). It can be considered that each transition is multiplying by a matrix, i.e., \(f_{i+1}=f_iM\). Since the minimal annihilating polynomial of \(M\) has degree at most \(n\), the shortest recurrence relation for \(f\) also has length at most \(n\). Hence, the shortest recurrence relation for \(\Pr[t>i]=\sum_{j=1}^{n-1}f(i,j)\) also has length at most \(n\). We can compute \(\Pr[t>0],\Pr[t>1],\cdots,\Pr[t>3n]\) in \(O(nm)\) time, then use the Berlekamp–Massey algorithm to find the shortest recurrence relation for \(\Pr[t > i]\) in \(O(n^2)\) time.
Consider finding the generating function of a \(k\)-order linear recurrence sequence \(a\). Suppose for \(i ≥ i_0\), \(a_i=\sum_{j=1}^kc_ja_{i-j}\). Let the generating functions of \(a\) and \(c\) be \(A(x)\) and \(C(x)\). Then \(A(x)=A(x)C(x)+A_0(x)\), where \(A_0(x)\) is determined by terms with \(i < i_0\).
Returning to the original problem, since we can find the shortest recurrence relation for \(\Pr[t > i]\), we can find \(C(x)\) and \(A_0(x)\) (defined as above). Rearranging gives \(A(x)=\frac{A_0(x)}{1-C(x)}\). We need to find \(\sum_{i\geq0}[x^i]A(x)\), which is equal to \(A(1)\). Substitute \(x = 1\) into the expression to solve. Since the modulus is a random prime, it can be assumed that the denominator is not \(0\).
Thus, we solve the problem in \(O(nm+n^2)\) time complexity. If the number of vertices and edges in graph \(G\) are of the same order, the time complexity can be considered as \(O(n^2)\).
General Graph
Example 3 Frank
Given a simple strongly connected directed graph \(G = (V, E)\), for all \(1 ≤ s ≤ n\), \(1 ≤ t ≤ n\), \(s ≠ t\), answer the following question: A piece starts at \(v_s\). Each second, the piece chooses an outgoing edge from the current point with equal probability and moves to the point pointed by the outgoing edge. Find the expected time to reach \(v_t\). \(3 ≤ n ≤ 400\).
Analysis and Transformation
Let \(p_{i, j}\) denote the probability that the piece at \(i\) chooses the outgoing edge \((i, j)\) to move to \(j\). Specifically, the probability is \(0\) when the outgoing edge does not exist. Let \(f_{i,j}\) denote the expected time for a random walk from \(i\) to \(j\). Specifically, \(f_{i,i} = 0\). When \(i ≠ j\), the transition equation is:
When \(i = j\), let \(g_i\) denote the expected time for a random walk starting from \(i\) to return to \(i\) for the first time. Then:
For convenience, we write the transition equations in matrix form. Let \(P\) denote the transition matrix of this graph, \(F\) denote the answer matrix, \(I\) denote the \(n \times n\) identity matrix, \(J\) denote the \(n \times n\) all-ones matrix, and \(G\) be an \(n \times n\) matrix with \(G_{i,i} = g_i\) and other entries \(0\). Then:
If we can find \(G\), then we only need to solve the equation:
Finding G
Definition 5.1. Define a stationary distribution of an \(n \times n\) transition matrix \(P\) as an \(n\)-dimensional vector \(π\) satisfying \(\sum_{i=1}^{n}\pi_{i}=1\), \(πP = π\), where each component of \(π\) is in the interval \([0,1]\).
The practical meaning of a stationary distribution is easy to see. If at some moment the piece has probability \(π_i\) of staying at \(v_i\), then at any subsequent moment, the piece still satisfies this probability distribution. We can find \(π\) in \(O(n^3)\) time by Gaussian elimination. What is the relationship between \(π\) and \(G\)?
Theorem 5.1. For any \(1 ≤ i ≤ n\), \(π_ig_i = 1\).
Proof
From \(F = J - G + PF\), rearranging gives:
Multiply both sides on the left by \(π\):
By the definition of \(π\), \(πP = π\), so:
Therefore:
The original proposition is proven.
Thus, by introducing the stationary distribution, we can solve for \(G\) in \(O(n^3)\) time.
Solving the Original Problem
During solving the equation, we encounter a problem: \((I - P)\) is not full rank, so it cannot be solved by multiplying the inverse matrix.
Definition 5.2. Define a directed spanning tree of a directed graph \(G = (V,E)\) rooted at \(r\in V\) as a subgraph \(T = (V,A)\) of \(G\) satisfying:
- For any \(i ≠ r\), the outdegree of \(i\) is \(1\).
- The outdegree of \(r\) is \(0\).
- There are no cycles in \(T\).
Lemma 5.1. (Matrix tree theorem for directed graphs) For a directed graph \(G\), let \(D\) denote its outdegree matrix, i.e., \(D_{i,i} = d_i\), \(D_{i,j} = 0(i ≠ j)\), where \(d_i\) is the outdegree of \(i\). Let \(A\) denote its adjacency matrix. Then the number of directed spanning trees rooted at \(r\) is the determinant of \(D - A\) after removing the \(r\)-th row and \(r\)-th column.
Theorem 5.2. For the transition matrix \(P\) of a strongly connected graph \(G = (V,E)\), the rank of \((I - P)\) is \(n - 1\).
Proof
Since multiplying a row of a matrix by a non-zero constant does not change its rank, we multiply the \(i\)-th row of \((I - P)\) by the outdegree of \(v_i\) to obtain a new matrix \(L\). We only need to prove that the rank of \(L\) is \(n - 1\).
Since each row of \(L\) sums to \(0\), summing all column vectors of \(L\) yields the zero vector, meaning these vectors are linearly dependent, so the rank of \(L\) is not \(n\).
It is not hard to see that \(L\) equals the outdegree matrix of graph \(G\) minus its adjacency matrix. By Lemma 5.1, the determinant after removing the \(i\)-th row and \(i\)-th column of \(L\) represents the number of directed spanning trees rooted at \(v_i\).
Since \(G\) is strongly connected, the number of directed spanning trees rooted at any point is not \(0\), meaning \(L\) remains full rank after removing the \(i\)-th row and \(i\)-th column.
Since adding a column does not reduce the rank, all row vectors of \(L\) after removing the \(i\)-th row are linearly independent. Hence, the rank of \(L\) is \(n - 1\).
Returning to the original problem, consider solving the equation in the original problem. For convenience, we write the equation as \(AX = B\), where \(A\) and \(B\) are known, and \(X\) needs to be solved. Since \(A\) is not full rank, there are infinitely many solutions. We first find a particular solution.
Perform Gaussian elimination on \(A\) and \(B\) together. Eliminate the first \(n - 1\) rows of \(A\) to a form where only the main diagonal and the \(n\)-th column have values, and the last row is eliminated to all zeros, i.e., the following form:
Let \(X_{n,i} = 0\), we can solve for a particular solution, denoted as \(Y\). Next, adjust the particular solution to the true solution.
Note that \(X_{n,i} = 0\). Considering the combinatorial meaning, \(Y_{i,j} = 1 + Y_{j,j} + P_{i,k}X_{k,j}\). It is not hard to solve \(X_{i,j} = Y_{i,j} - Y_{j,j}\).
Finally, the problem is solved in \(O(n^3)\) time complexity.
References
- A Brief Discussion on Random Walk Problems on Graph Models. IOI2019 China National Candidate Team Papers (pp. 17-26)
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用