Skip to content

Treap

Prerequisites: Naive Binary Search Tree, Heap Basics.

Introduction

Treap (Tree + Heap) is a weakly balanced binary search tree.

Each node in a Treap has, in addition to the value (\(\textit{val}\)) being maintained, a random priority (\(\textit{priority}\)). The values satisfy the binary search tree property, while the priorities satisfy the heap property (min-heap or max-heap).

The binary search tree property means:

  • The value (\(\textit{val}\)) of the left child is smaller than that of the parent node.
  • The value (\(\textit{val}\)) of the right child is larger than that of the parent node.

The heap property means:

  • The priority (\(\textit{priority}\)) of a child is larger or smaller than that of the parent (depending on whether it is a min-heap or max-heap).

It is not hard to see that if the same value is used, these two data structures combined would degenerate into a chain. Therefore, we introduce an additional heap value \(\textit{priority}\) on top of the search tree. For the \(\textit{val}\) values, we maintain the search tree property; for the \(\textit{priority}\) values, we maintain the heap property. The \(\textit{priority}\) value is randomly assigned.

The following figure shows an example of a Treap (here a min-heap is used, meaning the root has the smallest priority).
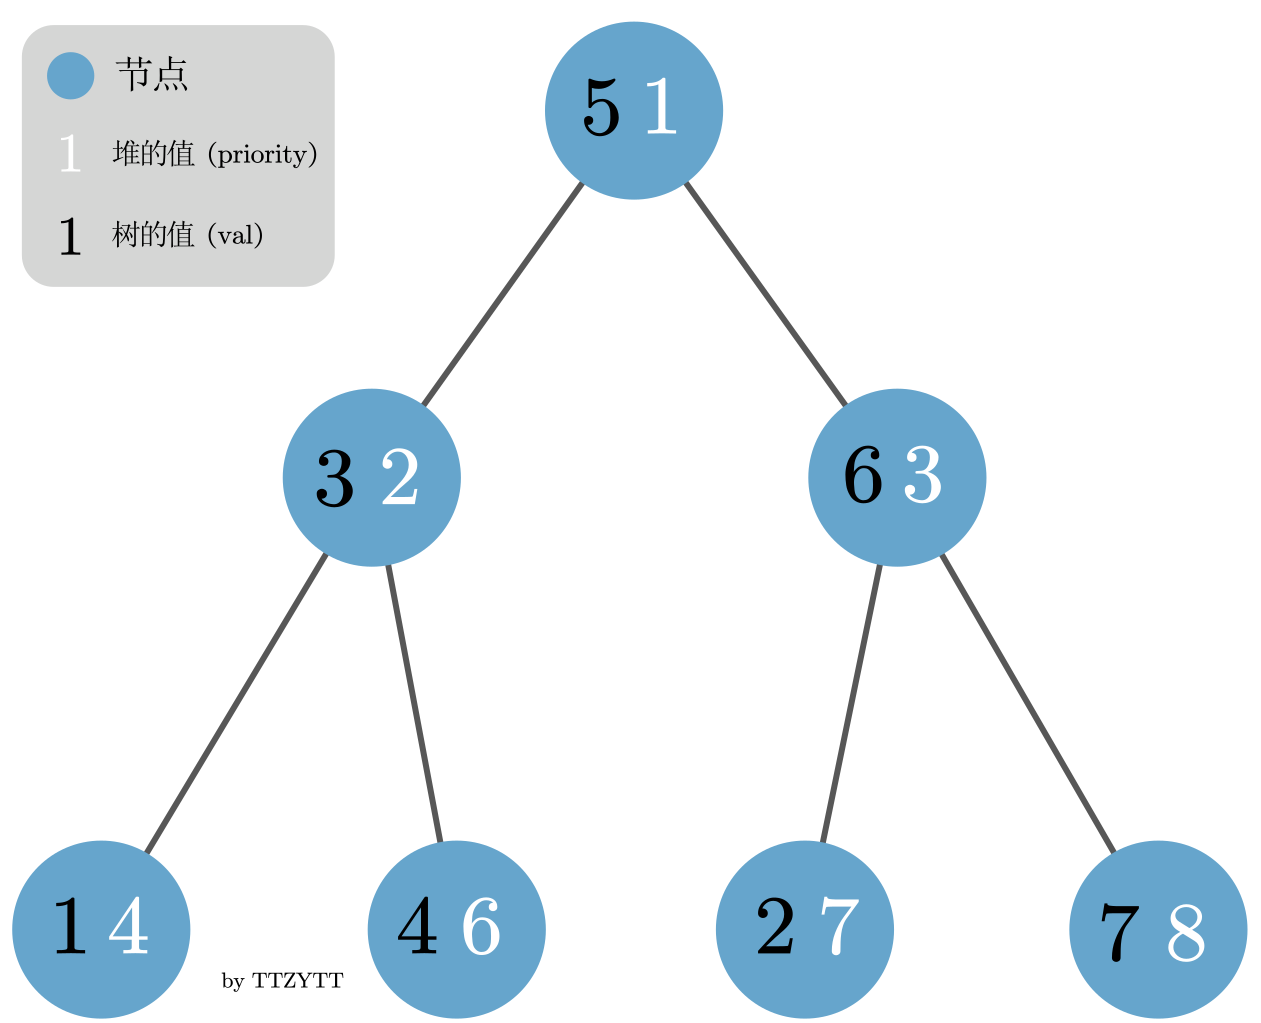
An example of a Treap

Why do we need to go through all this trouble to make this data structure satisfy both tree and heap properties, and assign random heap values?

To understand this, we first need to understand the problem with naive binary search trees. When inserting a new node into a naive search tree, we start recursively from the root. If the new node is smaller than the current node, we go left; otherwise, we go right.

Finally, when we find a node with no child, we make the new node its left or right child based on its value.

If the inserted node values are random (i.e., inserted in random order), the height of this naive search tree will be small (close to \(\log n\), where \(n\) is the number of nodes), and each level will have many nodes, i.e., its shape will be very "fat". The Treap in the figure above is an example. Therefore, any operation will have a complexity of about \(O(\log n)\).

However, this is only the complexity in the random case. If we insert nodes into a naive search tree in a very ordered sequence like:

1
1 2 3 4 5

Then the tree will degenerate into a chain, becoming very "tall and thin" (each inserted node is larger than the previous ones, so they are all placed as right children):
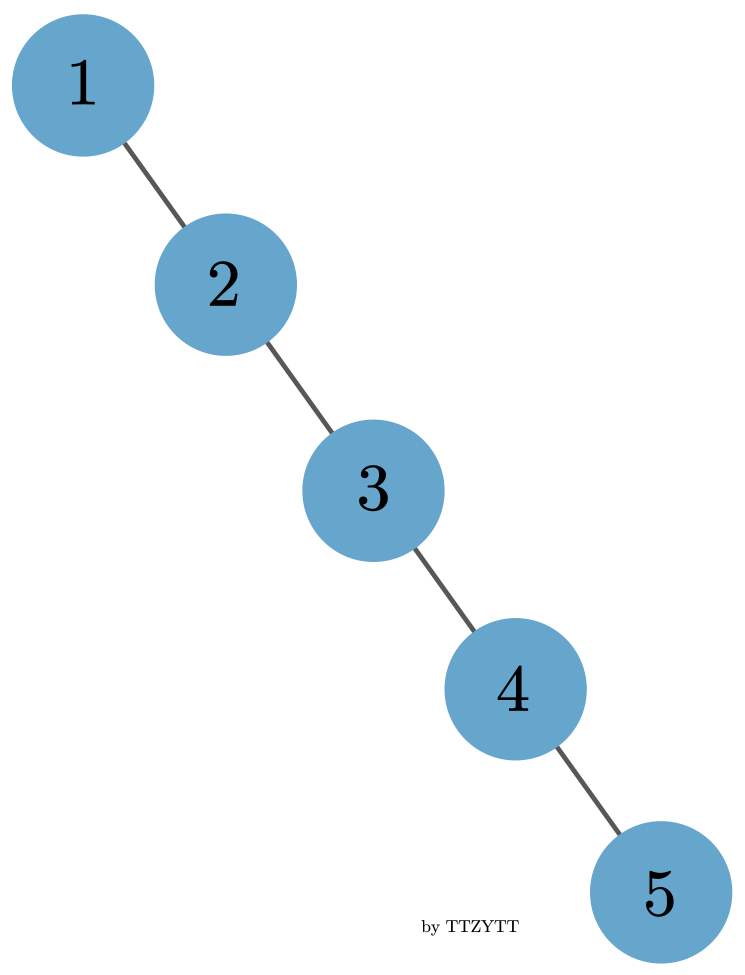
Example of degeneration into a chain

It is easy to see that the query complexity changes from \(O(\log n)\) to \(O(n)\).

To solve this problem and achieve a more "balanced" state, Treap uses random priorities to satisfy the heap property, "shuffling" the insertion order of nodes, thus giving the binary search tree ideal complexity and avoiding the chain degeneration problem.

Proof of Treap Complexity

Since the complexity of various operations in a Treap is related to the depth of the nodes being operated on, we first prove that the expected depth of all nodes is \(O(\log n)\).

Notation Convention

For convenience, we define:

  • \(n\) is the number of nodes.
  • In a Treap node, the property satisfying the binary search tree is called value, and the property satisfying the heap (i.e., random) is called priority. Assume the priority satisfies the min-heap property.
  • \(x_k\) denotes the node with the \(k\)-th smallest value.
  • \(X_{i,j}\) denotes the set \(\{x_i,x_{i+1},\cdots,x_{j-1},x_j\}\), i.e., the set of nodes from the \(i\)-th to the \(j\)-th in ascending order of value.
  • \(\operatorname{dep}(x)\) denotes the depth of node \(x\). The root depth is defined as \(0\).
  • \(Y_{i,j}\) is an indicator random variable that equals \(1\) when \(x_i\) is an ancestor of \(x_j\), and \(0\) otherwise. In particular, \(Y_{i,i}=0\).
  • \(\Pr(A)\) denotes the probability of event \(A\) occurring.

Proof of Expected Node Depth

Since the depth of node \(x_i\) equals the number of its ancestors, we have

\[ \operatorname{dep}(x_i)=\sum_{k=1}^nY_{k,i}. \]

Then by linearity of expectation,

\[ E(\operatorname{dep}(x_i))=E\left(\sum_{k=1}^nY_{k,i}\right)=\sum_{k=1}^nE(Y_{k,i}). \]

Since \(Y_{k,i}\) is an indicator random variable, its expectation equals the probability that it is \(1\), so

\[ E(\operatorname{dep}(x_i))=\sum_{k=1}^n\Pr(Y_{k,i}=1). \]

We first prove a lemma: \(Y_{i,j}=1\) if and only if \(x_i\) has the smallest priority in \(X_{i,j}\).

Proof of Lemma

Consider cases for \(x_i\) and \(x_j\).

  1. If \(x_i\) is the root: Since priorities satisfy the min-heap property, \(x_i\) has the smallest priority, and for any \(x_j\), \(x_i\) is an ancestor of \(x_j\).
  2. If \(x_j\) is the root: Similarly, \(x_j\) has the smallest priority, so \(x_i\) is not the smallest in \(X_{i,j}\); also \(x_i\) is not an ancestor of \(x_j\).
  3. If \(x_i\) and \(x_j\) are in two different subtrees of the root (one left, one right), then the root \(r\in X_{i,j}\). Therefore, \(x_i\) cannot have the smallest priority in \(X_{i,j}\) (because the root's priority is smaller). Also, since \(x_i\) and \(x_j\) belong to different subtrees, \(x_i\) is not an ancestor of \(x_j\).
  4. If \(x_i\) and \(x_j\) are in the same subtree of the root, we can treat this subtree as a new Treap and recursively apply the above proof.

Then according to the lemma, the expected depth can be transformed into

\[ E(\operatorname{dep}(x_i))=\sum_{k=1}^n\Pr(x_k=\min X_{i,k}\land k\neq i). \]

Since node priorities are random, we assume that any node in set \(X_{i,j}\) has equal probability of being the smallest. Then

\[ \begin{aligned} E(\operatorname{dep}(x_i))&=\sum_{k=1}^n\Pr(x_k=\min X_{i,k}\land k\neq i)\\ &=\sum_{k=1}^{n}\Pr(x_k=\min X_{i,k})-1\\ &=\sum_{k=1}^n\dfrac{1}{|i-k|+1}-1\\ &=\sum_{k=1}^{i-1}\dfrac{1}{i-k+1}+\sum_{k=i+1}^n\dfrac{1}{k-i+1}\\ &=\sum_{j=2}^i\dfrac 1j+\sum_{j=2}^{n-i+1}\dfrac 1j\\ &\le 2\sum_{j=2}^n\dfrac 1j < 2\sum_{j=2}^n\int_{j-1}^j\dfrac 1x\mathrm dx\\ &=2\int_1^n\dfrac 1x\mathrm dx=2\ln n=O(\log n). \end{aligned} \]

Therefore, the expected depth of each node is \(O(\log n)\).

The operations of a naive binary search tree all have complexity \(O(h)\), and maintaining the heap property in a Treap also has complexity \(O(h)\). Thus, the expected complexity of all Treap operations is \(O(\log n)\).

Intuitive Understanding of Expected Complexity

First, we need to recognize that a node's \(\textit{priority}\) property is directly related to its level in the tree. Recall the heap property:

  • Child node value (\(\textit{priority}\)) is larger or smaller than the parent (depending on min-heap or max-heap).

We find that nodes at lower levels, such as the root of the entire tree, have smaller \(\textit{priority}\) (in a min-heap). Moreover, in a naive search tree, nodes inserted earlier are more likely to have lower levels. We can associate this \(\textit{priority}\) property with insertion order to understand why Treap can shuffle node insertion order via \(\textit{priority}\).

When inserting a new node into a Treap, we need to maintain both tree and heap properties. The search tree property can be maintained during insertion, while the heap property can be maintained in two ways: rotation, and split/merge. Treaps using these two methods are called rotating Treap and non-rotating Treap, respectively.

Rotating Treap

Rotating Treap maintains balance through rotation, similar to AVL tree rotations, divided into left rotation and right rotation. That is, under the condition of satisfying the binary search tree, balance operations are performed on the Treap based on heap priorities.

Rotating Treap has relatively small constant factors among all balanced trees when solving ordinary balanced tree problems.

The code explanation below implements a rotating Treap using pointers; a full array-based implementation is provided at the end.

Info

In the code, rank represents the priority (\(\textit{priority}\) property) mentioned earlier, which satisfies the min-heap property.

Node Structure

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
struct Node {
  Node *ch[2];  // Addresses of the two child nodes
  int val, rank;
  int rep_cnt;  // Number of times the current value (val) repeats
  int siz;      // Size of the subtree rooted at the current node

  Node(int val) : val(val), rep_cnt(1), siz(1) {
    ch[0] = ch[1] = nullptr;
    rank = rand();
    // Note: during initialization, rank is randomly assigned
  }

  void upd_siz() {
    // Used to recalculate siz after rotation and deletion
    siz = rep_cnt;
    if (ch[0] != nullptr) siz += ch[0]->siz;
    if (ch[1] != nullptr) siz += ch[1]->siz;
  }
};

Rotation

Rotation is a very important operation in Treap, mainly used to adjust the levels of different nodes while preserving the Treap tree properties, in order to maintain the heap property.

Left and right rotations might not be easy to distinguish; here are two more obvious characteristics:

Meaning of rotation:

  • Without affecting the search tree property, turn the subtree opposite the rotation direction into the root node (e.g., left rotation turns the right subtree into the root)
  • Does not affect properties, and after rotation, the child node in the same direction as the rotation becomes the original root (e.g., after left rotation, the left child becomes the original root)

Left and right rotations are inverse operations, as shown in the figure.
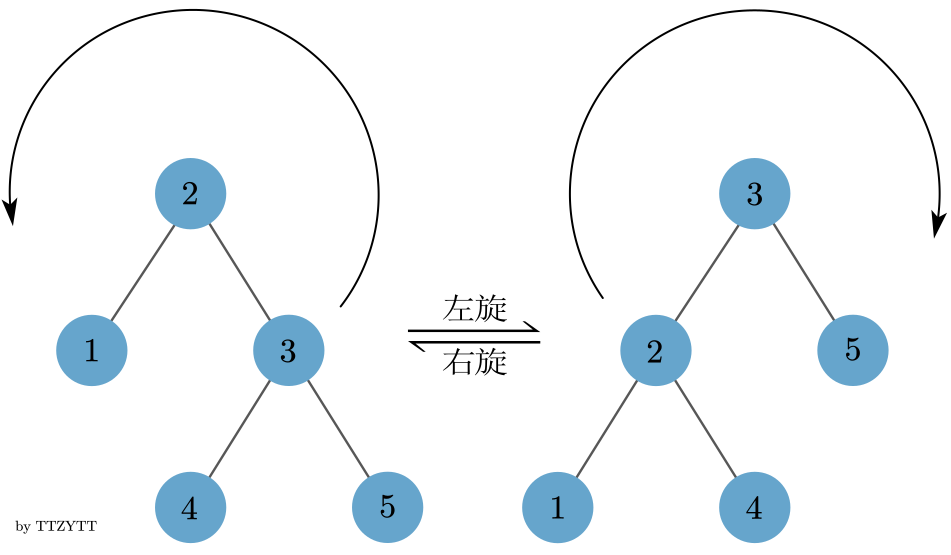
Rotation operation

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
enum rot_type { LF = 1, RT = 0 };

void _rotate(Node *&cur,
             rot_type dir) {  // dir parameter indicates rotation direction: 0 for right, 1 for left
  // Note: cur is passed by reference, so changing cur here changes the original variable.
  // If this cur is a child of another tree, it will be found via ch and modified here.

  // The following code explains the case of left rotation.
  Node *tmp = cur->ch[dir];  // Let C become the root node.
                             // Here tmp is a temporary node pointer pointing to the node becoming the new root.

  /* Left rotation: make the right child the root node
   *         A                 C
   *        / \               / \
   *       B  C    ---->     A   E
   *         / \            / \
   *        D   E          B   D
   */
  cur->ch[dir] = tmp->ch[!dir];    // Make A's right child become D
  tmp->ch[!dir] = cur;             // Make C's left child become A
  cur->upd_siz(), tmp->upd_siz();  // Update size information
  cur = tmp;  // Finally assign the variable temporarily storing tree C to the current root (note cur is a reference)
}

Insertion

Similar to insertion in an ordinary binary search tree, but rotation is needed during insertion to maintain the heap property of priorities.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
void _insert(Node *&cur, int val) {
  if (cur == nullptr) {
    // If the node doesn't exist, create it directly
    cur = new Node(val);
    return;
  } else if (val == cur->val) {
    // If a node with the same value exists, increment the repeat count
    cur->rep_cnt++;
    cur->siz++;
  } else if (val < cur->val) {
    // Maintain search tree property: if val is smaller than current node, insert left; otherwise right
    _insert(cur->ch[0], val);
    if (cur->ch[0]->rank < cur->rank) {
      // In a min-heap, the parent node's priority must be smaller.
      // Since the newly inserted left child is smaller than the parent, we need to make the left child the parent.
      _rotate(cur, RT);  // Note the rotation property: to bring the left child up, we need a right rotation.
    }
    cur->upd_siz();  // Size changes after insertion, need to update
  } else {
    _insert(cur->ch[1], val);
    if (cur->ch[1]->rank < cur->rank) {
      _rotate(cur, LF);
    }
    cur->upd_siz();
  }
}

Deletion

Mainly involves case analysis; different cases have different handling methods. After deletion, the tree size changes, so update is needed. If the node to be deleted has both left and right subtrees, consider who should become the parent after deletion (maintain the node with smaller rank on top).

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
void _del(Node *&cur, int val) {
  if (val > cur->val) {
    _del(cur->ch[1], val);
    // Larger value is in the right subtree, and vice versa
    cur->upd_siz();
  } else if (val < cur->val) {
    _del(cur->ch[0], val);
    cur->upd_siz();
  } else {
    if (cur->rep_cnt > 1) {
      // If the node to delete is repeated, simply decrease the repeat count
      cur->rep_cnt--, cur->siz--;
      return;
    }
    uint8_t state = 0;
    state |= (cur->ch[0] != nullptr);
    state |= ((cur->ch[1] != nullptr) << 1);
    // 00: none, 01: left only, 10: right only, 11: both
    Node *tmp = cur;
    switch (state) {
      case 0:
        delete cur;
        cur = nullptr;
        // No children, simply delete the node
        break;
      case 1:  // Left child only
        cur = tmp->ch[0];
        // Make the root become the left child, then delete the original root.
        // Note tmp is copied from cur, and cur is a reference.
        delete tmp;
        break;
      case 2:  // Right child only
        cur = tmp->ch[1];
        delete tmp;
        break;
      case 3:
        rot_type dir = cur->ch[0]->rank < cur->ch[1]->rank
                           ? RT
                           : LF;  // dir is the child with smaller rank
        _rotate(cur, dir);  // This rotation brings the child with smaller priority up.
                            // rt is 0, lf is 1, opposite to actual subtree indices.
        _del(
            cur->ch[!dir],
            val);  // After rotation, the original root is on the side of the rotation direction,
                   // so we need to continue deleting this original root node.
                   // If the node to delete is "upper" in the tree, we will keep rotating it
                   // until it has no subtrees (or only one), then delete it.
        cur->upd_siz();
        // Deletion changes size
        break;
    }
  }
}

Query Rank by Value

Operation meaning: Query the rank (number of nodes smaller than val in the subtree + 1) of value val in the subtree rooted at cur.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
int _query_rank(Node *cur, int val) {
  int less_siz = cur->ch[0] == nullptr ? 0 : cur->ch[0]->siz;
  // Number of nodes smaller than val in this tree
  if (val == cur->val)
    // If this node is the one being queried
    return less_siz + 1;
  else if (val < cur->val) {
    if (cur->ch[0] != nullptr)
      return _query_rank(cur->ch[0], val);
    else
      return 1;  // If left subtree is empty, the value is smaller than the smallest node, so rank is 1
  } else {
    if (cur->ch[1] != nullptr)
      // If the queried value is larger than this node, then this node's left subtree and itself are definitely smaller.
      // So add these two, plus the result of searching right
      // (rank of val in the subtree rooted at the right child)
      return less_siz + cur->rep_cnt + _query_rank(cur->ch[1], val);
    else
      return cur->siz + 1;
    // If no right subtree, directly whole tree + 1, equivalent to less_siz + cur->rep_cnt + 1
  }
}

Query Value by Rank

To query a value by rank, we first need to know how to determine which part of the tree the node is in:

The following table shows a judgment method:

Left Subtree Root Node / Current Node Right Subtree
rank ≤ left subtree size rank > left subtree size and ≤ left subtree size + root repeat count rank > left subtree size + root repeat count

Note that if in the right subtree, the original rank needs to be adjusted during recursion. Recursion then queries the value at that rank in the right subtree. To convert the rank to be based on the right subtree, subtract the left subtree size and the root's repeat count.

Think of all nodes as a sorted array or number line (as below),

1
2
3
4
5
6
7
1 -> |left subtree nodes|root|right subtree nodes| -> n
                           ^
                           queried rank
                     ⬇ convert to rank based on right subtree
1 -> |right subtree nodes| -> n
       ^
       queried rank

The conversion method is simply to subtract the left subtree size and the root's repeat count from the rank.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
int _query_val(Node *cur, int rank) {
  // Query the value of the rank-th largest node in the tree
  int less_siz = cur->ch[0] == nullptr ? 0 : cur->ch[0]->siz;
  // less_siz is the size of the left subtree
  if (rank <= less_siz)
    return _query_val(cur->ch[0], rank);
  else if (rank <= less_siz + cur->rep_cnt)
    return cur->val;
  else
    return _query_val(cur->ch[1], rank - less_siz - cur->rep_cnt);  // As explained earlier
}

Query First Node Smaller Than val

Note that a global variable q_prev_tmp in the class is used here.

This value is only updated when val is larger than the current node's value, so returning this variable returns the last time val was larger than the current node's value, after which it becomes smaller.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
int _query_prev(Node *cur, int val) {
  if (val <= cur->val) {
    // Still larger than val, so search left subtree
    if (cur->ch[0] != nullptr) return _query_prev(cur->ch[0], val);
  } else {
    // Only when entering this else block will q_prev_tmp be updated
    q_prev_tmp = cur->val;
    // Current node is already smaller than val, but may not be the largest, so continue searching right subtree
    if (cur->ch[1] != nullptr) _query_prev(cur->ch[1], val);
    // Subsequent recursion may not change q_prev_tmp again,
    // then just return this value. In short, return the last cur->val that entered this else block.
    return q_prev_tmp;
  }
  return NIL;
}

Query First Node Larger Than val

Similar to the previous one, just swap the inequality signs.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
int _query_nex(Node *cur, int val) {
  if (val >= cur->val) {
    if (cur->ch[1] != nullptr) return _query_nex(cur->ch[1], val);
  } else {
    q_nex_tmp = cur->val;
    if (cur->ch[0] != nullptr) _query_nex(cur->ch[0], val);
    return q_nex_tmp;
  }
  return NIL;
}

Non-rotating Treap

The operational approach of non-rotating Treap makes it inherently support sequence maintenance, persistence, and other features.

Non-rotating Treap is also called split-merge Treap. It has only two core operations: split and merge. Through these two operations, many other operations can be implemented more conveniently than with rotating Treap. These two operations are introduced below.

Note

Discussion of non-rotating Treap should mention FHQ-Treap (by Fan Haoqiang). That is, a persistent, interval-operation supporting non-rotating Treap. For more content, refer to the ppt "Fan Haoqiang on Data Structures".

Split

Split by Value

The split operation takes two parameters: root pointer \(\textit{cur}\) and key value \(\textit{key}\). The result splits the Treap pointed to by the root pointer into two Treaps: the first Treap contains all nodes with value (\(\textit{val}\)) less than or equal to \(\textit{key}\), and the second Treap contains all nodes with value greater than \(\textit{key}\).

The process first checks if \(\textit{key}\) is less than \(\textit{cur}\)'s value. If so, then \(\textit{cur}\) and its entire right subtree are greater than \(\textit{key}\), belonging to the second Treap. However, part of the left subtree may also be greater than \(\textit{key}\), so we need to continue recursively splitting the left subtree. For the part of the left subtree greater than \(\textit{key}\), we attach it as \(\textit{cur}\)'s left subtree, so that all nodes on \(\textit{cur}\) are greater than \(\textit{key}\).

Correspondingly, if \(\textit{key}\) is greater than or equal to \(\textit{cur}\)'s value, then \(\textit{cur}\)'s entire left subtree and itself are less than or equal to \(\textit{key}\), belonging to the first Treap after split. Also, part of \(\textit{cur}\)'s right subtree may be less than or equal to \(\textit{key}\), so we need to recursively split the right subtree. Attach the part less than or equal to \(\textit{key}\) as \(\textit{cur}\)'s right subtree, so that all nodes on \(\textit{cur}\) are less than or equal to \(\textit{key}\).

The figure below shows split by value when \(\textit{cur}\)'s value is less than or equal to \(\textit{key}\).1
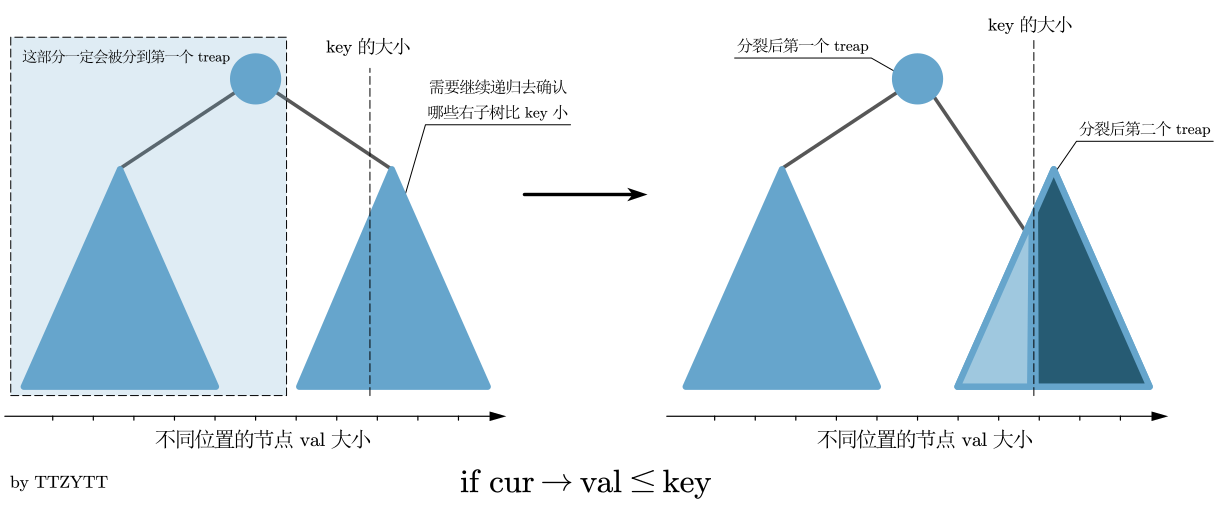
Split by value

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
pair<Node *, Node *> split(Node *cur, int key) {
  if (cur == nullptr) return {nullptr, nullptr};
  if (cur->val <= key) {
    // cur and its left subtree definitely belong to the first tree after split
    auto temp = split(cur->ch[1], key);
    // But part of its right subtree may also be smaller than key
    cur->ch[1] = temp.first;
    // We take the part smaller than key and make it cur's right subtree, so the entire cur is smaller than key.
    // The remaining part of the right subtree becomes the second Treap after split.
    cur->upd_siz();
    // Size changes after split, need to update
    return {cur, temp.second};
  } else {
    // Similarly
    auto temp = split(cur->ch[0], key);
    cur->ch[0] = temp.second;
    cur->upd_siz();
    return {temp.first, cur};
  }
}

Split by Rank

Compared to split by value, this operation is more like querying value by rank in rotating Treap (a node's rank is the number of nodes with smaller values in the tree \(+ 1\)):

This function takes two parameters: node pointer \(\textit{cur}\) and rank \(\textit{rk}\), and returns three Treaps after split.

The first Treap contains nodes with rank less than \(\textit{rk}\), the second has rank equal to \(\textit{rk}\) (and only one node, since multiple equal ones would increase the cnt field in the Node struct), and the third has rank greater.

The key point of this operation is determining which part of the tree contains the node with rank equal to \(\textit{cur}\). This is also an important part of querying value by rank in rotating Treap, explained in detail earlier, so not repeated here.

Also, the recursive part of this operation is very similar to split by value, not elaborated here.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
tuple<Node *, Node *, Node *> split_by_rk(Node *cur, int rk) {
  if (cur == nullptr) return {nullptr, nullptr, nullptr};
  int ls_siz = cur->ch[0] == nullptr ? 0 : cur->ch[0]->siz;
  if (rk <= ls_siz) {
    // Node with rank equal to cur is in left subtree
    Node *l, *mid, *r;
    tie(l, mid, r) = split_by_rk(cur->ch[0], rk);
    cur->ch[0] = r;  // The third Treap returned has ranks all greater than rk
    // After setting cur's left subtree to r, all nodes in cur have rank greater than rk
    cur->upd_siz();
    return {l, mid, cur};
  } else if (rk <= ls_siz + cur->cnt) {
    // The node equal to cur is the current node
    Node *lt = cur->ch[0];
    Node *rt = cur->ch[1];
    cur->ch[0] = cur->ch[1] = nullptr;
    // After split, the second Treap has only one node, so set its children to null
    return {lt, cur, rt};
  } else {
    // Node with rank equal to cur is in right subtree
    // Recursive process similar to above
    Node *l, *mid, *r;
    tie(l, mid, r) = split_by_rk(cur->ch[1], rk - ls_siz - cur->cnt);
    cur->ch[1] = l;
    cur->upd_siz();
    return {cur, mid, r};
  }
}

Merge

The merge operation takes two parameters: left Treap root pointer \(\textit{u}\) and right Treap root pointer \(\textit{v}\). It must satisfy that all node values in \(\textit{u}\) are less than or equal to all node values in \(\textit{v}\). Generally, the two Treaps we merge are originally split from one Treap, so it's easy to satisfy that all nodes in \(\textit{u}\) are smaller than those in \(\textit{v}\).

In rotating Treap, we use rotation to maintain \(\textit{priority}\) satisfying heap properties while not changing tree properties. In non-rotating Treap, we use merge to achieve the same effect.

Since the two Treaps are already ordered, during merge we only need to decide which tree to "place on top" and which "below", i.e., which tree to use as a subtree. Clearly, according to heap properties, we need to place the one with smaller \(\textit{priority}\) on top (here using min-heap).

Also, we need to satisfy the search tree property, so if the root node of \(\textit{u}\) has smaller \(\textit{priority}\) than \(\textit{v}\)'s, then \(\textit{u}\) becomes the new root, and \(\textit{v}\), having larger values than \(\textit{u}\), should merge with \(\textit{u}\)'s right subtree; otherwise, \(\textit{v}\) becomes the new root, and since \(u\)'s values are smaller than \(\textit{v}\)'s, merge with \(v\)'s left subtree.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
Node *merge(Node *u, Node *v) {
  // The two trees passed already satisfy search tree properties internally
  // and all nodes in u < all nodes in v.
  // So during merge we need to maintain heap properties.
  // Here using min-heap.
  if (u == nullptr && v == nullptr) return nullptr;
  if (u != nullptr && v == nullptr) return u;
  if (v != nullptr && u == nullptr) return v;

  if (u->prio < v->prio) {
    // u's prio is smaller, u should be the parent
    u->ch[1] = merge(u->ch[1], v);
    // Since v is larger than u, make v u's right subtree
    u->upd_siz();
    return u;
  } else {
    // v is smaller, v should be the parent
    v->ch[0] = merge(u, v->ch[0]);
    // u is smaller than v, so recursive parameters are like this
    v->upd_siz();
    return v;
  }
}

Insertion

In non-rotating Treap, basic operations like insertion, deletion, and querying rank by value can be implemented either using ordinary binary search tree methods or using split and merge. Generally, using split and merge is more concise but slightly slower2. To help better understand non-rotating Treap, the following operations all use split and merge.

When implementing insertion, we utilize some properties of split. That is, nodes with value less than or equal to \(\textit{val}\) will be split into the first Treap.

So, suppose we split the current Treap according to \(\textit{val}\). We get two trees satisfying:

\[ \begin{aligned} T_1 &\le val\\ T_2 &> val \end{aligned} \]

where \(T_1\) denotes the set of nodes assigned to the first Treap after split, and \(T_2\) the second.

If we further split \(T_1\) by \(\textit{val} - 1\), we get two trees satisfying:

\[ \begin{gathered} T_{1\ \text{left}} \le val - 1\\ T_{1\ \text{right}} > val - 1 \ \And \ T_{1\ \text{right}} \le val \end{gathered} \]

where \(T_{1\ \text{left}}\) denotes the set of nodes assigned to the first Treap after splitting \(T_1\), and \(T_{1\ \text{right}}\) the second. The condition \(\And \ T_{1\ \text{right}} \le val\) in the latter half comes from \(T_1\)'s condition \(T_1 \le val\).

It's not hard to see that as long as \(\textit{val}\) and node values are integers (as in most use cases), there is exactly one node satisfying \(T_{1\ \text{right}}\), i.e., the node with value equal to \(\textit{val}\).

During insertion, if we find a node satisfying \(T_{1\ \text{right}}\) exists, we can simply increase its repeat count; otherwise, create a new node.

Note that after splitting, we need to merge the trees back together using merge so they can be used again later. Also, note that the order of parameters in merge matters: all nodes in the first tree must be smaller than those in the second.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
void insert(int val) {
  auto temp = split(root, val);
  // Split the entire tree into two based on val
  // Note split implementation: nodes equal to val go to left subtree
  auto l_tr = split(temp.first, val - 1);
  // l_tr's left subtree <= val - 1; if any node = val, it must be in right subtree
  Node *new_node;
  if (l_tr.second == nullptr) {
    // If node doesn't exist, create new; otherwise increase repeat count.
    new_node = new Node(val);
  } else {
    l_tr.second->cnt++;
    l_tr.second->upd_siz();
  }
  Node *l_tr_combined =
      merge(l_tr.first, l_tr.second == nullptr ? new_node : l_tr.second);
  // Merge T_1 left and T_1 right
  root = merge(l_tr_combined, temp.second);
  // Merge T_1 and T_2
}

Deletion

Deletion also uses a method similar to insertion: find the node with value equal to \(\textit{val}\) and delete it.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
void del(int val) {
  auto temp = split(root, val);
  auto l_tr = split(temp.first, val - 1);
  if (l_tr.second->cnt > 1) {
    // If node's repeat count > 1, just decrease
    l_tr.second->cnt--;
    l_tr.second->upd_siz();
    l_tr.first = merge(l_tr.first, l_tr.second);
  } else {
    if (temp.first == l_tr.second) {
      // Possibly the entire T_1 is only this node, so set this point to null to mark deletion
      temp.first = nullptr;
    }
    delete l_tr.second;
    l_tr.second = nullptr;
  }
  root = merge(l_tr.first, temp.second);
}

Query Rank by Value

Rank is the number of nodes smaller than this value \(+ 1\), so we split the current tree by \(\textit{val} - 1\). Then the first tree after split satisfies:

\[ T_1 \le val - 1 \]

If tree values and \(\textit{val}\) are integers, then \(T_1\) contains all nodes with value less than \(\textit{val}\).

1
2
3
4
5
6
int qrank_by_val(Node* cur, int val) {
  auto temp = split(cur, val - 1);
  int ret = (temp.first == nullptr ? 0 : temp.first->siz) + 1;  // According to definition + 1
  root = merge(temp.first, temp.second);  // Merge back after splitting
  return ret;
}

Query Value by Rank

Calling split_by_rk() returns three split Treaps, where the second contains only one node with rank equal to \(\textit{rk}\), so we directly return this node's \(\textit{val}\).

1
2
3
4
5
6
7
int qval_by_rank(Node *cur, int rk) {
  Node *l, *mid, *r;
  tie(l, mid, r) = split_by_rk(cur, rk);
  int ret = mid->val;
  root = merge(merge(l, mid), r);
  return ret;
}

Query First Node Smaller Than val

This problem can be transformed into: among all nodes smaller than \(\textit{val}\), find the one with the largest rank. We split the Treap by \(\textit{val}\); the first Treap returned contains all nodes with values less than \(\textit{val}\). Then we call qval_by_rank() to find the node with the largest value in this tree.

1
2
3
4
5
6
7
8
int qprev(int val) {
  auto temp = split(root, val - 1);
  // temp.first is the subtree with values < val
  int ret = qval_by_rank(temp.first, temp.first->siz);
  // Here we query the largest value among all nodes smaller than val
  root = merge(temp.first, temp.second);
  return ret;
}

Query First Node Larger Than val

Similar to the previous operation, this can be transformed into: among all nodes larger than \(\textit{val}\), find the one with the smallest rank. After splitting by \(\textit{val}\), the second Treap returned contains all nodes with values greater than \(\textit{val}\).

Then we query the value of the node with rank \(1\) in this tree (i.e., the node with the smallest value), successfully obtaining the first node larger than \(\textit{val}\).

1
2
3
4
5
6
7
int qnex(int val) {
  auto temp = split(root, val);
  int ret = qval_by_rank(temp.second, 1);
  // Query the smallest value among all subtrees larger than val
  root = merge(temp.first, temp.second);
  return ret;
}

Building a Tree (build)

Convert a sequence \(\{a_n\}\) of \(n\) nodes into a Treap.

We can insert these \(n\) nodes sequentially. Each time inserting a node with value \(v\), split the entire Treap into two parts: nodes with value \(\le v\) and nodes with value \(> v\). Then create a new node with value \(v\), and merge the two parts and the new node in increasing order. Single insertion time \(O(\log n)\), total time \(O(n\log n)\).

In some problems, there may be multiple insertions of ordered sequences, requiring building a tree in \(O(n)\) time.

Method 1: During recursive tree building, each time pick the midpoint of the current interval as the tree root for that interval, and assign appropriate priorities to each node so that the new tree satisfies heap properties. This ensures tree height \(O(\log n)\).

Method 2: During recursive tree building, each time pick the midpoint of the current interval as the tree root, then assign random priorities to each node. This ensures tree height \(O(\log n)\) but does not guarantee heap properties. This is still correct because priorities in non-rotating Treap are used to make merge more random, not to guarantee tree height.

Method 3: Observe that Treap is a Cartesian tree; use the \(O(n)\) Cartesian tree building method with a monotonic stack to maintain the right chain.

Interval Operations in Non-rotating Treap

Building a Tree

One major advantage of non-rotating Treap over rotating Treap is the ability to perform various interval operations. Below we use the template problem of Literary Balanced Tree as an example to introduce interval operations in Treap.

You need to write a data structure (refer to the problem title) to maintain an ordered sequence.

Required operations: flip an interval. For example, original sequence \(5\ 4\ 3\ 2\ 1\), flipping interval \([2,4]\) yields \(5\ 2\ 3\ 4\ 1\). For \(100\%\) data, \(1 \le n\) (initial interval length) \(m\) (number of flips) \(\le 10^5\)

In this problem, we need to implement interval flipping. First consider how to build the tree; the built tree should represent the initial interval.

We simply insert the indices of the interval sequentially into the Treap. Then an in-order traversal (left subtree, then current node, then right subtree) yields this interval3.

We know that inserting nodes in increasing order into a naive binary search tree results in a long chain; in-order traversal naturally gives the interval.

As shown above, inserting nodes in order \(1\ 2\ 3\ 4\ 5\) into a naive search tree yields \(1\ 2\ 3\ 4\ 5\) in in-order traversal.

But in a Treap, after inserting nodes in increasing order, the merge operation adjusts the tree structure according to \(\textit{priority}\). In this case, how can we ensure in-order traversal outputs correctly?

Refer to the monotonic stack building method for Cartesian trees to understand this.

Let the newly inserted node be \(\textit{u}\).

First, because nodes are inserted in increasing order, each new node will be connected to the right chain of the Treap (the chain from the root always going to the right child).

Starting from the root, the \(\textit{priority}\) of nodes on the right chain is increasing (min-heap). We can find the first node on the right chain with \(\textit{priority}\) greater than \(\textit{u}\), call this node \(\textit{v}\), and replace it with \(\textit{u}\).

Since \(\textit{u}\) must be greater than all other nodes in the tree, we need to attach \(\textit{v}\) and its subtree as \(\textit{u}\)'s left subtree. And \(\textit{u}\) has no right subtree at this point.

We can see that in in-order traversal, \(\textit{u}\) will definitely be the last visited (because \(\textit{u}\) is the last in the right chain, and in in-order traversal, the right subtree is visited last).

The figure below shows the changes when inserting node \(5\) into a Treap after inserting nodes \(1 \sim 5\) in increasing order. This figure helps understand the process of insertion in increasing order.
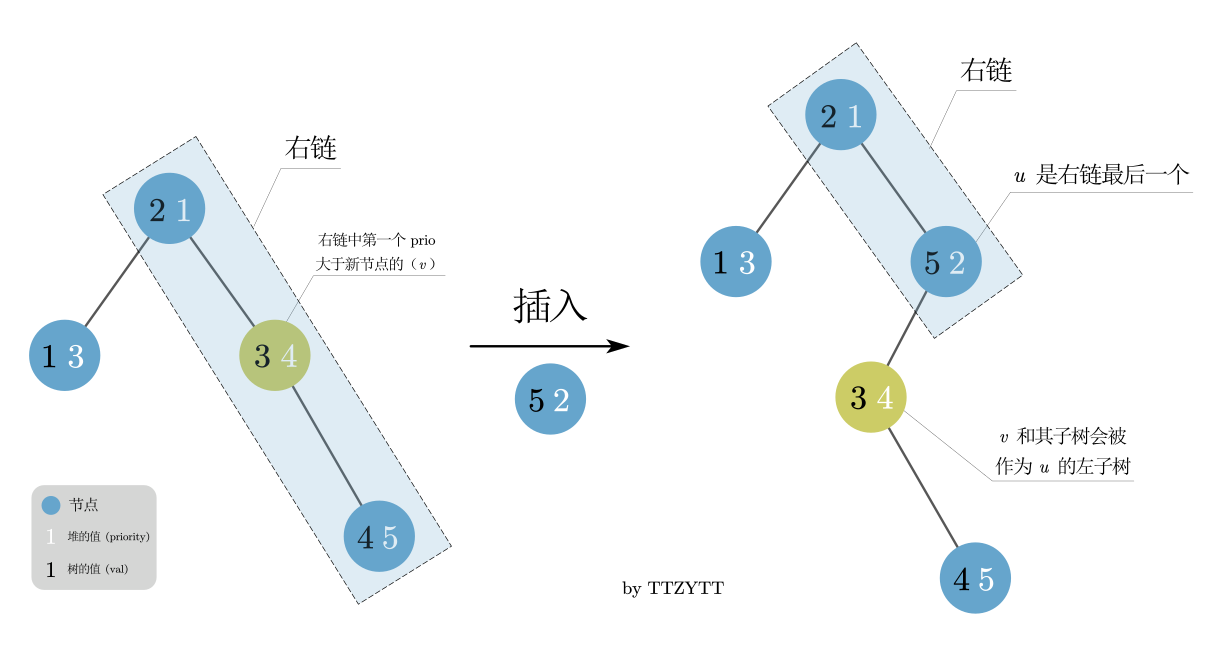
Inserting a node

Interval Flip

When flipping interval \([l, r]\), the basic idea is to split the tree into three intervals: \([1, l - 1],\ [l, r],\ [r + 1, n]\), then flip the middle \([l, r]\)3.

The specific flip operation swaps the left and right children of every node in the interval. The figure below shows the Treap after flipping intervals \([3, 4]\) and \([3, 5]\) in the Treap from the previous figure.
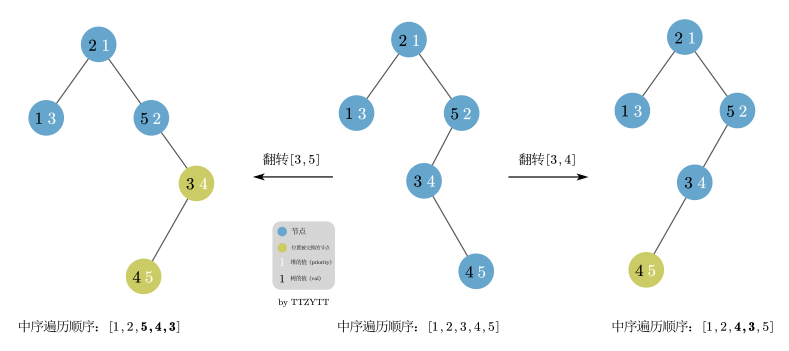
Interval flip

Note that if we flip this way, each time we flip interval \([l, r]\), \(r - l\) nodes would have their children swapped. Such frequent operations obviously cannot handle \(10^5\) data range; its \(O(n \times \log_2 n)\) flip complexity per operation is even worse than brute force (because besides linear time swapping nodes, we also need \(O(\log_2 n)\) time to find the nodes to swap).

Observing the problem requirements, since we only need to output the final interval after operations, we don't actually need to swap every time. Thus, we can use lazy tags (lazy propagation), commonly used in segment trees, to optimize complexity. When flipping, we only need to mark the parent node, indicating that every left/right child in the subtree below needs to be swapped.

In segment trees, we usually propagate lazy tags during updates and queries. This is because the range we want to update/query may not coincide with the range represented by the lazy tag, so we propagate first to ensure correct values.

The same applies in non-rotating Treap. Specifically, we split the Treap into the three trees mentioned earlier, mark the middle tree with a lazy tag, then merge the three trees. Because the interval we want to flip may not coincide with the lazy tag's range, we need to propagate the tag during splitting. Also, split and merge operations cause each node and its lazy tag's represented nodes to change, so we also need to propagate lazy tags before merging.

In other words, when the tree structure changes—when we perform split or merge operations and need to change a node's left/right child information—we should propagate the tag beforehand, not after, because lazy tags need to be passed to child nodes. If we change child information before propagating, the lazy tag loses its target.4

The following explains the code, referencing3.

Since most operations in interval operations are the same as ordinary non-rotating Treap, only the differences are explained here.

Propagating Tags

Note that the lazy tag here means we need to swap every child node in this tree. So if the current node's child also has a lazy tag, the two flips cancel. If the child does not need flipping, this lazy tag needs to be propagated further to the child.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
// Here pushdown is a member function of Node class, where to_rev is the lazy tag
void pushdown() {
  swap(ch[0], ch[1]);
  if (ch[0] != nullptr) ch[0]->to_rev ^= 1;
  if (ch[1] != nullptr) ch[1]->to_rev ^= 1;
  to_rev = false;
}

void check_tag() {
  if (to_rev) pushdown();
}

Split

Note that in this problem, due to flip operations, the \(\textit{val}\) in the Treap no longer satisfies the binary search tree property (see interval flip figure), so we cannot decide whether to recurse left or right based on \(\textit{val}\).

Thus, this split is more similar to split by rank in ordinary non-rotating Treap; it decides recursion direction based on the current tree size, i.e., based on the node's original position in the tree.

The first Treap returned contains nodes with rank all \(\le \textit{sz}\), while the second contains nodes with rank all \(> \textit{sz}\).

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
#define siz(_) (_ == nullptr ? 0 : _->siz)

pair<Node*, Node*> split(Node* cur, int sz) {
  // Decide based on tree size
  if (cur == nullptr) return {nullptr, nullptr};
  cur->check_tag();
  // Propagate before splitting
  if (sz <= siz(cur->ch[0])) {
    auto temp = split(cur->ch[0], sz);
    cur->ch[0] = temp.second;
    cur->upd_siz();
    return {temp.first, cur};
  } else {
    auto temp =
        split(cur->ch[1],
              sz - siz(cur->ch[0]) -
                  1);  // This conversion is explained in "Query value by rank" in rotating Treap
    cur->ch[1] = temp.first;
    cur->upd_siz();
    return {cur, temp.second};
  }
}

Merge

The only note is to propagate lazy tags before merging.

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
Node *merge(Node *sm, Node *bg) {
  // small, big
  if (sm == nullptr && bg == nullptr) return nullptr;
  if (sm != nullptr && bg == nullptr) return sm;
  if (sm == nullptr && bg != nullptr) return bg;
  sm->check_tag(), bg->check_tag();
  if (sm->prio < bg->prio) {
    sm->ch[1] = merge(sm->ch[1], bg);
    sm->upd_siz();
    return sm;
  } else {
    bg->ch[0] = merge(sm, bg->ch[0]);
    bg->upd_siz();
    return bg;
  }
}

Interval Flip

As described earlier, split into \([1, l - 1],\ [l, r],\ [r + 1, n]\) three intervals, mark the middle interval, then merge.

1
2
3
4
5
6
7
8
9
void seg_rev(int l, int r) {
  // Here less and more are relative to l
  auto less = split(root, l - 1);
  // All <= l - 1 go to less's left subtree
  auto more = split(less.second, r - l + 1);
  // The interval of the first r - l + 1 elements starting from l
  more.first->to_rev = true;
  root = merge(less.first, merge(more.first, more.second));
}

In-order Traversal Print

Remember to propagate tags when printing.

1
2
3
4
5
6
7
8
void print(Node* cur) {
  if (cur == nullptr) return;
  cur->check_tag();
  // In-order traversal: left subtree, then self, then right subtree
  print(cur->ch[0]);
  cout << cur->val << " ";
  print(cur->ch[1]);
}

Complete Code

Rotating Treap

Pointer Implementation

Complete Code

The following is the complete version of the code explained earlier, a template for ordinary balanced tree problems.

  1
  2
  3
  4
  5
  6
  7
  8
  9
 10
 11
 12
 13
 14
 15
 16
 17
 18
 19
 20
 21
 22
 23
 24
 25
 26
 27
 28
 29
 30
 31
 32
 33
 34
 35
 36
 37
 38
 39
 40
 41
 42
 43
 44
 45
 46
 47
 48
 49
 50
 51
 52
 53
 54
 55
 56
 57
 58
 59
 60
 61
 62
 63
 64
 65
 66
 67
 68
 69
 70
 71
 72
 73
 74
 75
 76
 77
 78
 79
 80
 81
 82
 83
 84
 85
 86
 87
 88
 89
 90
 91
 92
 93
 94
 95
 96
 97
 98
 99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
// author: (ttzytt)[ttzytt.com]
#include <cstdint>
#include <cstdio>
#include <cstdlib>
using namespace std;

struct Node {
  Node *ch[2];
  int val, rank;
  int rep_cnt;
  int siz;

  Node(int val) : val(val), rep_cnt(1), siz(1) {
    ch[0] = ch[1] = nullptr;
    rank = rand();
  }

  void upd_siz() {
    siz = rep_cnt;
    if (ch[0] != nullptr) siz += ch[0]->siz;
    if (ch[1] != nullptr) siz += ch[1]->siz;
  }
};

class Treap {
 private:
  Node *root;

  constexpr static int NIL = -1;  // Indicates queried value does not exist

  enum rot_type { LF = 1, RT = 0 };

  int q_prev_tmp = 0, q_nex_tmp = 0;

  void _rotate(Node *&cur, rot_type dir) {  // 0 for right rotation, 1 for left
    Node *tmp = cur->ch[dir];
    cur->ch[dir] = tmp->ch[!dir];
    tmp->ch[!dir] = cur;
    cur->upd_siz(), tmp->upd_siz();
    cur = tmp;
  }

  void _insert(Node *&cur, int val) {
    if (cur == nullptr) {
      cur = new Node(val);
      return;
    } else if (val == cur->val) {
      cur->rep_cnt++;
      cur->siz++;
    } else if (val < cur->val) {
      _insert(cur->ch[0], val);
      if (cur->ch[0]->rank < cur->rank) {
        _rotate(cur, RT);
      }
      cur->upd_siz();
    } else {
      _insert(cur->ch[1], val);
      if (cur->ch[1]->rank < cur->rank) {
        _rotate(cur, LF);
      }
      cur->upd_siz();
    }
  }

  void _del(Node *&cur, int val) {
    if (val > cur->val) {
      _del(cur->ch[1], val);
      cur->upd_siz();
    } else if (val < cur->val) {
      _del(cur->ch[0], val);
      cur->upd_siz();
    } else {
      if (cur->rep_cnt > 1) {
        cur->rep_cnt--, cur->siz--;
        return;
      }
      uint8_t state = 0;
      state |= (cur->ch[0] != nullptr);
      state |= ((cur->ch[1] != nullptr) << 1);
      // 00: none, 01: left only, 10: right only, 11: both
      Node *tmp = cur;
      switch (state) {
        case 0:
          delete cur;
          cur = nullptr;
          break;
        case 1:  // left only
          cur = tmp->ch[0];
          delete tmp;
          break;
        case 2:  // right only
          cur = tmp->ch[1];
          delete tmp;
          break;
        case 3:
          rot_type dir = cur->ch[0]->rank < cur->ch[1]->rank ? RT : LF;
          _rotate(cur, dir);
          _del(cur->ch[!dir], val);
          cur->upd_siz();
          break;
      }
    }
  }

  int _query_rank(Node *cur, int val) {
    int less_siz = cur->ch[0] == nullptr ? 0 : cur->ch[0]->siz;
    if (val == cur->val)
      return less_siz + 1;
    else if (val < cur->val) {
      if (cur->ch[0] != nullptr)
        return _query_rank(cur->ch[0], val);
      else
        return 1;
    } else {
      if (cur->ch[1] != nullptr)
        return less_siz + cur->rep_cnt + _query_rank(cur->ch[1], val);
      else
        return cur->siz + 1;
    }
  }

  int _query_val(Node *cur, int rank) {
    int less_siz = cur->ch[0] == nullptr ? 0 : cur->ch[0]->siz;
    if (rank <= less_siz)
      return _query_val(cur->ch[0], rank);
    else if (rank <= less_siz + cur->rep_cnt)
      return cur->val;
    else
      return _query_val(cur->ch[1], rank - less_siz - cur->rep_cnt);
  }

  int _query_prev(Node *cur, int val) {
    if (val <= cur->val) {
      if (cur->ch[0] != nullptr) return _query_prev(cur->ch[0], val);
    } else {
      q_prev_tmp = cur->val;
      if (cur->ch[1] != nullptr) _query_prev(cur->ch[1], val);
      return q_prev_tmp;
    }
    return NIL;
  }

  int _query_nex(Node *cur, int val) {
    if (val >= cur->val) {
      if (cur->ch[1] != nullptr) return _query_nex(cur->ch[1], val);
    } else {
      q_nex_tmp = cur->val;
      if (cur->ch[0] != nullptr) _query_nex(cur->ch[0], val);
      return q_nex_tmp;
    }
    return NIL;
  }

 public:
  void insert(int val) { _insert(root, val); }

  void del(int val) { _del(root, val); }

  int query_rank(int val) { return _query_rank(root, val); }

  int query_val(int rank) { return _query_val(root, rank); }

  int query_prev(int val) { return _query_prev(root, val); }

  int query_nex(int val) { return _query_nex(root, val); }
};

Treap tr;

int main() {
  srand(0);
  int t;
  scanf("%d", &t);
  while (t--) {
    int mode;
    int num;
    scanf("%d%d", &mode, &num);
    switch (mode) {
      case 1:
        tr.insert(num);
        break;
      case 2:
        tr.del(num);
        break;
      case 3:
        printf("%d\n", tr.query_rank(num));
        break;
      case 4:
        printf("%d\n", tr.query_val(num));
        break;
      case 5:
        printf("%d\n", tr.query_prev(num));
        break;
      case 6:
        printf("%d\n", tr.query_nex(num));
        break;
    }
  }
}

Array Implementation

Below is the template code for ordinary balanced tree on bzoj, implemented with arrays.

Complete Code
  1
  2
  3
  4
  5
  6
  7
  8
  9
 10
 11
 12
 13
 14
 15
 16
 17
 18
 19
 20
 21
 22
 23
 24
 25
 26
 27
 28
 29
 30
 31
 32
 33
 34
 35
 36
 37
 38
 39
 40
 41
 42
 43
 44
 45
 46
 47
 48
 49
 50
 51
 52
 53
 54
 55
 56
 57
 58
 59
 60
 61
 62
 63
 64
 65
 66
 67
 68
 69
 70
 71
 72
 73
 74
 75
 76
 77
 78
 79
 80
 81
 82
 83
 84
 85
 86
 87
 88
 89
 90
 91
 92
 93
 94
 95
 96
 97
 98
 99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
#include <iostream>

constexpr int MAXN = 100005;
constexpr int INF = 1 << 30;

int n;

struct treap {  // Directly maintained as a data structure, can be used directly
  int l[MAXN], r[MAXN], val[MAXN], rnd[MAXN], size_[MAXN], w[MAXN];
  int sz, ans, rt;

  void pushup(int x) { size_[x] = size_[l[x]] + size_[r[x]] + w[x]; }

  void lrotate(int &k) {
    int t = r[k];
    r[k] = l[t];
    l[t] = k;
    size_[t] = size_[k];
    pushup(k);
    k = t;
  }

  void rrotate(int &k) {
    int t = l[k];
    l[k] = r[t];
    r[t] = k;
    size_[t] = size_[k];
    pushup(k);
    k = t;
  }

  void insert(int &k, int x) {  // Insert
    if (!k) {
      sz++;
      k = sz;
      size_[k] = 1;
      w[k] = 1;
      val[k] = x;
      rnd[k] = rand();
      return;
    }
    size_[k]++;
    if (val[k] == x) {
      w[k]++;
    } else if (val[k] < x) {
      insert(r[k], x);
      if (rnd[r[k]] < rnd[k]) lrotate(k);
    } else {
      insert(l[k], x);
      if (rnd[l[k]] < rnd[k]) rrotate(k);
    }
  }

  bool del(int &k, int x) {  // Delete node
    if (!k) return false;
    if (val[k] == x) {
      if (w[k] > 1) {
        w[k]--;
        size_[k]--;
        return true;
      }
      if (l[k] == 0 || r[k] == 0) {
        k = l[k] + r[k];
        return true;
      } else if (rnd[l[k]] < rnd[r[k]]) {
        rrotate(k);
        return del(k, x);
      } else {
        lrotate(k);
        return del(k, x);
      }
    } else if (val[k] < x) {
      bool succ = del(r[k], x);
      if (succ) size_[k]--;
      return succ;
    } else {
      bool succ = del(l[k], x);
      if (succ) size_[k]--;
      return succ;
    }
  }

  int queryrank(int k, int x) {
    if (!k) return 0;
    if (val[k] == x)
      return size_[l[k]] + 1;
    else if (x > val[k]) {
      return size_[l[k]] + w[k] + queryrank(r[k], x);
    } else
      return queryrank(l[k], x);
  }

  int querynum(int k, int x) {
    if (!k) return 0;
    if (x <= size_[l[k]])
      return querynum(l[k], x);
    else if (x > size_[l[k]] + w[k])
      return querynum(r[k], x - size_[l[k]] - w[k]);
    else
      return val[k];
  }

  void querypre(int k, int x) {
    if (!k) return;
    if (val[k] < x)
      ans = k, querypre(r[k], x);
    else
      querypre(l[k], x);
  }

  void querysub(int k, int x) {
    if (!k) return;
    if (val[k] > x)
      ans = k, querysub(l[k], x);
    else
      querysub(r[k], x);
  }
} T;

using std::cin;
using std::cout;

int main() {
  cin.tie(nullptr)->sync_with_stdio(false);
  srand(123);
  cin >> n;
  int opt, x;
  for (int i = 1; i <= n; i++) {
    cin >> opt >> x;
    if (opt == 1)
      T.insert(T.rt, x);
    else if (opt == 2)
      T.del(T.rt, x);
    else if (opt == 3) {
      cout << T.queryrank(T.rt, x) << '\n';
    } else if (opt == 4) {
      cout << T.querynum(T.rt, x) << '\n';
    } else if (opt == 5) {
      T.ans = 0;
      T.querypre(T.rt, x);
      cout << T.val[T.ans] << '\n';
    } else if (opt == 6) {
      T.ans = 0;
      T.querysub(T.rt, x);
      cout << T.val[T.ans] << '\n';
    }
  }
  return 0;
}

Non-rotating Treap

Pointer Implementation

Complete Code

The following is the complete version of the code explained earlier, a template for ordinary balanced tree problems.

  1
  2
  3
  4
  5
  6
  7
  8
  9
 10
 11
 12
 13
 14
 15
 16
 17
 18
 19
 20
 21
 22
 23
 24
 25
 26
 27
 28
 29
 30
 31
 32
 33
 34
 35
 36
 37
 38
 39
 40
 41
 42
 43
 44
 45
 46
 47
 48
 49
 50
 51
 52
 53
 54
 55
 56
 57
 58
 59
 60
 61
 62
 63
 64
 65
 66
 67
 68
 69
 70
 71
 72
 73
 74
 75
 76
 77
 78
 79
 80
 81
 82
 83
 84
 85
 86
 87
 88
 89
 90
 91
 92
 93
 94
 95
 96
 97
 98
 99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
// author: (ttzytt)[ttzytt.com]
#include <cstdio>
#include <cstdlib>
#include <ctime>
#include <tuple>
using namespace std;

struct Node {
  Node *ch[2];
  int val, prio;
  int cnt;
  int siz;

  Node(int _val) : val(_val), cnt(1), siz(1) {
    ch[0] = ch[1] = nullptr;
    prio = rand();
  }

  Node(Node *_node) {
    val = _node->val, prio = _node->prio, cnt = _node->cnt, siz = _node->siz;
  }

  void upd_siz() {
    siz = cnt;
    if (ch[0] != nullptr) siz += ch[0]->siz;
    if (ch[1] != nullptr) siz += ch[1]->siz;
  }
};

struct none_rot_treap {
#define _3 second.second
#define _2 second.first
  Node *root;

  pair<Node *, Node *> split(Node *cur, int key) {
    if (cur == nullptr) return {nullptr, nullptr};
    if (cur->val <= key) {
      auto temp = split(cur->ch[1], key);
      cur->ch[1] = temp.first;
      cur->upd_siz();
      return {cur, temp.second};
    } else {
      auto temp = split(cur->ch[0], key);
      cur->ch[0] = temp.second;
      cur->upd_siz();
      return {temp.first, cur};
    }
  }

  tuple<Node *, Node *, Node *> split_by_rk(Node *cur, int rk) {
    if (cur == nullptr) return {nullptr, nullptr, nullptr};
    int ls_siz = cur->ch[0] == nullptr ? 0 : cur->ch[0]->siz;
    if (rk <= ls_siz) {
      Node *l, *mid, *r;
      tie(l, mid, r) = split_by_rk(cur->ch[0], rk);
      cur->ch[0] = r;
      cur->upd_siz();
      return {l, mid, cur};
    } else if (rk <= ls_siz + cur->cnt) {
      Node *lt = cur->ch[0];
      Node *rt = cur->ch[1];
      cur->ch[0] = cur->ch[1] = nullptr;
      return {lt, cur, rt};
    } else {
      Node *l, *mid, *r;
      tie(l, mid, r) = split_by_rk(cur->ch[1], rk - ls_siz - cur->cnt);
      cur->ch[1] = l;
      cur->upd_siz();
      return {cur, mid, r};
    }
  }

  Node *merge(Node *u, Node *v) {
    if (u == nullptr && v == nullptr) return nullptr;
    if (u != nullptr && v == nullptr) return u;
    if (v != nullptr && u == nullptr) return v;
    if (u->prio < v->prio) {
      u->ch[1] = merge(u->ch[1], v);
      u->upd_siz();
      return u;
    } else {
      v->ch[0] = merge(u, v->ch[0]);
      v->upd_siz();
      return v;
    }
  }

  void insert(int val) {
    auto temp = split(root, val);
    auto l_tr = split(temp.first, val - 1);
    Node *new_node;
    if (l_tr.second == nullptr) {
      new_node = new Node(val);
    } else {
      l_tr.second->cnt++;
      l_tr.second->upd_siz();
    }
    Node *l_tr_combined =
        merge(l_tr.first, l_tr.second == nullptr ? new_node : l_tr.second);
    root = merge(l_tr_combined, temp.second);
  }

  void del(int val) {
    auto temp = split(root, val);
    auto l_tr = split(temp.first, val - 1);
    if (l_tr.second->cnt > 1) {
      l_tr.second->cnt--;
      l_tr.second->upd_siz();
      l_tr.first = merge(l_tr.first, l_tr.second);
    } else {
      if (temp.first == l_tr.second) {
        temp.first = nullptr;
      }
      delete l_tr.second;
      l_tr.second = nullptr;
    }
    root = merge(l_tr.first, temp.second);
  }

  int qrank_by_val(Node *cur, int val) {
    auto temp = split(cur, val - 1);
    int ret = (temp.first == nullptr ? 0 : temp.first->siz) + 1;
    root = merge(temp.first, temp.second);
    return ret;
  }

  int qval_by_rank(Node *cur, int rk) {
    Node *l, *mid, *r;
    tie(l, mid, r) = split_by_rk(cur, rk);
    int ret = mid->val;
    root = merge(merge(l, mid), r);
    return ret;
  }

  int qprev(int val) {
    auto temp = split(root, val - 1);
    int ret = qval_by_rank(temp.first, temp.first->siz);
    root = merge(temp.first, temp.second);
    return ret;
  }

  int qnex(int val) {
    auto temp = split(root, val);
    int ret = qval_by_rank(temp.second, 1);
    root = merge(temp.first, temp.second);
    return ret;
  }
};

none_rot_treap tr;

int main() {
  srand(time(nullptr));
  int t;
  scanf("%d", &t);
  while (t--) {
    int mode;
    int num;
    scanf("%d%d", &mode, &num);
    switch (mode) {
      case 1:
        tr.insert(num);
        break;
      case 2:
        tr.del(num);
        break;
      case 3:
        printf("%d\n", tr.qrank_by_val(tr.root, num));
        break;
      case 4:
        printf("%d\n", tr.qval_by_rank(tr.root, num));
        break;
      case 5:
        printf("%d\n", tr.qprev(num));
        break;
      case 6:
        printf("%d\n", tr.qnex(num));
        break;
    }
  }
}

Interval Operations in Non-rotating Treap

Pointer Implementation

Complete Code

The following is the complete version of the code explained earlier, a template for the Literary Balanced Tree problem.

  1
  2
  3
  4
  5
  6
  7
  8
  9
 10
 11
 12
 13
 14
 15
 16
 17
 18
 19
 20
 21
 22
 23
 24
 25
 26
 27
 28
 29
 30
 31
 32
 33
 34
 35
 36
 37
 38
 39
 40
 41
 42
 43
 44
 45
 46
 47
 48
 49
 50
 51
 52
 53
 54
 55
 56
 57
 58
 59
 60
 61
 62
 63
 64
 65
 66
 67
 68
 69
 70
 71
 72
 73
 74
 75
 76
 77
 78
 79
 80
 81
 82
 83
 84
 85
 86
 87
 88
 89
 90
 91
 92
 93
 94
 95
 96
 97
 98
 99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
// author: (ttzytt)[ttzytt.com]
#include <cstdlib>
#include <ctime>
#include <iostream>
using namespace std;

// Reference: https://www.cnblogs.com/Equinox-Flower/p/10785292.html
struct Node {
  Node* ch[2];
  int val, prio;
  int cnt;
  int siz;
  bool to_rev = false;  // Need to flip every node under this subtree

  Node(int _val) : val(_val), cnt(1), siz(1) {
    ch[0] = ch[1] = nullptr;
    prio = rand();
  }

  int upd_siz() {
    siz = cnt;
    if (ch[0] != nullptr) siz += ch[0]->siz;
    if (ch[1] != nullptr) siz += ch[1]->siz;
    return siz;
  }

  void pushdown() {
    swap(ch[0], ch[1]);
    if (ch[0] != nullptr) ch[0]->to_rev ^= 1;
    // If child node also needed flipping, the two flips cancel.
    // If child node didn't need flipping, this tag needs to be pushed further.
    if (ch[1] != nullptr) ch[1]->to_rev ^= 1;
    to_rev = false;
  }

  void check_tag() {
    if (to_rev) pushdown();
  }
};

struct Seg_treap {
  Node* root;
#define siz(_) (_ == nullptr ? 0 : _->siz)

  pair<Node*, Node*> split(Node* cur, int sz) {
    // Split by tree size
    if (cur == nullptr) return {nullptr, nullptr};
    cur->check_tag();
    if (sz <= siz(cur->ch[0])) {
      // Left subtree is enough
      auto temp = split(cur->ch[0], sz);
      // Left subtree may not all be needed; temp.second is the unneeded part
      cur->ch[0] = temp.second;
      cur->upd_siz();
      return {temp.first, cur};
    } else {
      // Left plus part of right (including this node itself)
      auto temp = split(cur->ch[1], sz - siz(cur->ch[0]) - 1);
      cur->ch[1] = temp.first;
      cur->upd_siz();
      return {cur, temp.second};
    }
  }

  Node* merge(Node* sm, Node* bg) {
    // small, big
    if (sm == nullptr && bg == nullptr) return nullptr;
    if (sm != nullptr && bg == nullptr) return sm;
    if (sm == nullptr && bg != nullptr) return bg;
    sm->check_tag(), bg->check_tag();
    if (sm->prio < bg->prio) {
      sm->ch[1] = merge(sm->ch[1], bg);
      sm->upd_siz();
      return sm;
    } else {
      bg->ch[0] = merge(sm, bg->ch[0]);
      bg->upd_siz();
      return bg;
    }
  }

  void insert(int val) {
    auto temp = split(root, val);
    auto l_tr = split(temp.first, val - 1);
    Node* new_node;
    if (l_tr.second == nullptr) new_node = new Node(val);
    Node* l_tr_combined =
        merge(l_tr.first, l_tr.second == nullptr ? new_node : l_tr.second);
    root = merge(l_tr_combined, temp.second);
  }

  void seg_rev(int l, int r) {
    // Here less and more are relative to l
    auto less = split(root, l - 1);
    // All <= l - 1 go to less's left
    auto more = split(less.second, r - l + 1);
    // Take the first r - l + 1 starting from l
    more.first->to_rev = true;
    root = merge(less.first, merge(more.first, more.second));
  }

  void print(Node* cur) {
    if (cur == nullptr) return;
    cur->check_tag();
    print(cur->ch[0]);
    cout << cur->val << " ";
    print(cur->ch[1]);
  }
};

Seg_treap tr;

int main() {
  srand(time(nullptr));
  int n, m;
  cin >> n >> m;
  for (int i = 1; i <= n; i++) tr.insert(i);
  while (m--) {
    int l, r;
    cin >> l >> r;
    tr.seg_rev(l, r);
  }
  tr.print(tr.root);
}

Example Problems

Ordinary Balanced Tree

Literary Balanced Tree (Splay)

「ZJOI2006」Bookshelf

「NOI2005」Maintain Sequence

CF 702F T-Shirts

References and Notes