Introduction to Complexity
Time complexity and space complexity are important metrics for measuring the efficiency of an algorithm.
Number of Basic Operations
The same algorithm may run at different speeds on different computers, and the actual runtime is difficult to compute theoretically. Measuring it directly is also cumbersome. Therefore, we usually consider not the actual runtime of the algorithm but the number of basic operations required for its execution.
On a typical computer, operations such as addition, subtraction, multiplication, division, accessing variables (variables of basic data types, similarly hereinafter), and assigning values to variables can be regarded as basic operations.
Counting or estimating the number of basic operations can serve as an indicator for evaluating the runtime of an algorithm.
Time Complexity
Definition
When measuring the speed of an algorithm, the size of the data must be considered. The data size generally refers to the number of input numbers, the number of vertices and edges in a graph given in the input, etc. Generally, the larger the data size, the longer the algorithm takes. In algorithm competitions, when evaluating the efficiency of an algorithm, the most important aspect is not its runtime for a specific data size but the trend of its runtime as the data size grows, i.e., time complexity.
Introduction
The main reasons for considering the trend of runtime with data size are as follows:
- Modern computers can process hundreds of millions or even more basic operations per second, so the data sizes we handle are usually large. If algorithm A takes \(100n\) time on data of size \(n\), and algorithm B takes \(n^2\) time on data of size \(n\), algorithm B is faster when the data size is less than \(100\). However, in one second, algorithm A can process millions of data points, while algorithm B can only process tens of thousands. When longer execution times are allowed, the impact of time complexity on the processable data size becomes even more significant, far exceeding the effect of runtime differences at the same data size.
- We use the number of basic operations to represent runtime, but different basic operations take different amounts of time. For example, addition and subtraction take much less time than division. Calculating time complexity while ignoring the differences between basic operations and the distinction between one basic operation and ten basic operations eliminates the impact of varying execution times among basic operations.
Of course, the runtime of an algorithm is not entirely determined by the input size but also depends on the input content. Therefore, time complexity is further divided into several types, such as:
- Worst-case time complexity: The time complexity corresponding to the input that takes the longest time for each input size. In algorithm competitions, since the input can be arbitrarily given within the specified data range, we generally consider the worst-case time complexity to ensure the algorithm can handle any data within the given range.
- Average (expected) time complexity: The complexity corresponding to the average runtime over all possible inputs for each input size (the expected runtime under random input).
The so-called "trend of runtime with data size" is a vague concept. We need to use the asymptotic notation introduced below to formally express time complexity.
Definition of Asymptotic Notation
Asymptotic notation provides a formal description of the order of a function. Simply put, asymptotic notation ignores the slower-growing parts of a function and the coefficients of its terms (in time complexity analysis, coefficients are generally referred to as "constants"), while retaining the important parts that indicate the growth trend of the function.
A simple mnemonic: use uppercase for inclusive (non-strict) comparisons and lowercase for exclusive (strict) comparisons. Equality is \(\Theta\), less than or equal is \(O\), and greater than or equal is \(\Omega\). The uppercase \(O\) and lowercase \(o\) originally come from the Greek letter Omicron, but due to their identical appearance, they can also be understood as the Latin uppercase \(O\) and lowercase \(o\).
In English, the roots "-micro-" and "-mega-" are often used to represent \(10^{-6}\) (one-millionth) and \(10^6\) (million), respectively, and also denote "small" and "large." Small and large are also common meanings of the Greek letters Omicron and Omega.
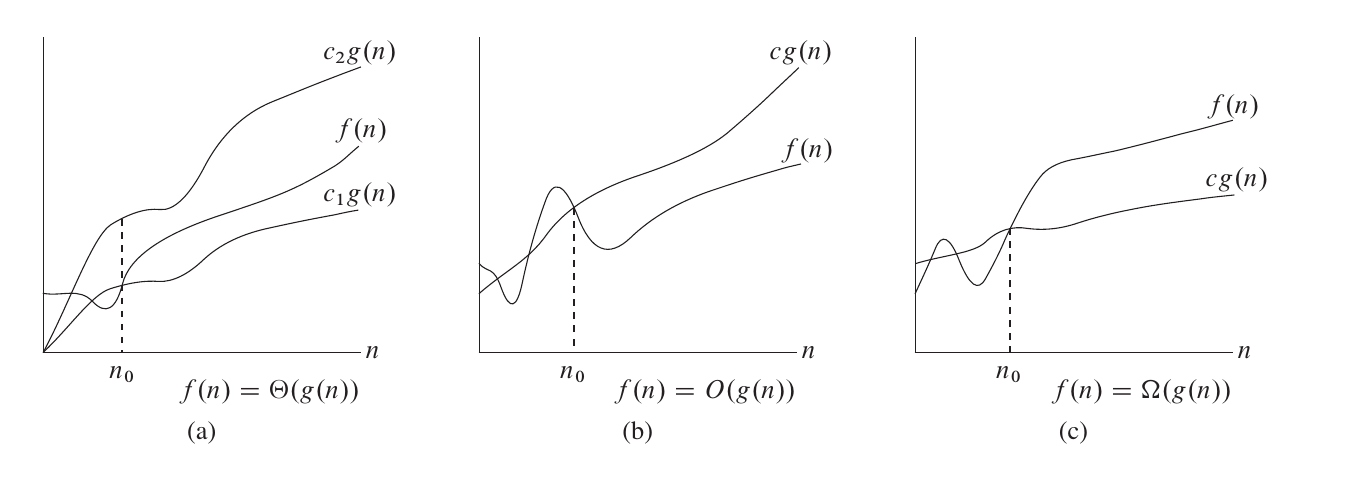
Big Theta Notation
For functions \(f(n)\) and \(g(n)\), \(f(n)=\Theta(g(n))\) if and only if \(\exists c_1,c_2,n_0>0\) such that \(\forall n \ge n_0, 0\le c_1\cdot g(n)\le f(n) \le c_2\cdot g(n)\).
In other words, if \(f(n)=\Theta(g(n))\), we can find two positive numbers \(c_1\) and \(c_2\) such that \(f(n)\) is sandwiched between \(c_1\cdot g(n)\) and \(c_2\cdot g(n)\).
For example, \(3n^2+5n-3=\Theta(n^2)\), where \(c_1, c_2, n_0\) can be \(2, 4, 100\), respectively. \(n\sqrt {n} + n{\log^5 n} + m{\log m} +nm=\Theta(n\sqrt {n} + m{\log m} + nm)\), where \(c_1, c_2, n_0\) can be \(1, 2, 100\), respectively.
Big O Notation
The \(\Theta\) notation gives both an upper and lower bound for a function. If only the asymptotic upper bound of a function is known but not its asymptotic lower bound, the \(O\) notation can be used. \(f(n)=O(g(n))\) if and only if \(\exists c,n_0\) such that \(\forall n \ge n_0,0\le f(n)\le c\cdot g(n)\).
In time complexity analysis, the \(O\) notation is often used because we are typically concerned with the upper bound of the program's runtime, not its lower bound.
It is important to note that the "upper bound" and "lower bound" here refer to the trend of the function, not the algorithm. The upper bound of an algorithm's runtime corresponds to the "worst-case time complexity," not the big \(O\) notation. Therefore, it is entirely feasible to use \(\Theta\) notation to represent worst-case time complexity; in fact, \(\Theta\) is more precise than \(O\). The main reasons for using \(O\) notation are: first, sometimes we can only prove the upper bound of time complexity but not its lower bound (this often occurs with more complex algorithms and complexity analysis), and second, \(O\) is more convenient to type on a computer.
Big Omega Notation
Similarly, we use \(\Omega\) notation to describe the asymptotic lower bound of a function. \(f(n)=\Omega(g(n))\) if and only if \(\exists c,n_0\) such that \(\forall n \ge n_0,0\le c\cdot g(n)\le f(n)\).
Little o Notation
If \(O\) notation is analogous to "less than or equal to," then \(o\) notation is analogous to "less than."
Little \(o\) notation is widely used in mathematical analysis. The Taylor expansion of a function at a point has a Peano remainder term, and little \(o\) notation is used to represent strict inequality, enabling asymptotic analysis with equivalent infinitesimals.
\(f(n)=o(g(n))\) if and only if for any given positive number \(c\), \(\exists n_0\) such that \(\forall n \ge n_0,0\le f(n)< c\cdot g(n)\).
Little Omega Notation
If \(\Omega\) notation is analogous to "greater than or equal to," then \(\omega\) notation is analogous to "greater than."
\(f(n)=\omega(g(n))\) if and only if for any given positive number \(c\), \(\exists n_0\) such that \(\forall n \ge n_0,0\le c\cdot g(n)< f(n)\).
Common Properties
- \(f(n) = \Theta(g(n))\iff f(n)=O(g(n))\land f(n)=\Omega(g(n))\)
- \(f_1(n) + f_2(n) = O(\max(f_1(n), f_2(n)))\)
- \(f_1(n) \times f_2(n) = O(f_1(n) \times f_2(n))\)
- \(\forall a \neq 1, \log_a{n} = O(\log_2 n)\). From the change-of-base formula, any logarithmic function has the same growth rate regardless of its base. Therefore, the base of logarithms is generally omitted in asymptotic time complexity.
Simple Examples of Time Complexity Calculation
for Loop
1 2 3 4 5 6 7 8 9 | |
1 2 3 4 5 6 | |
1 2 3 4 5 6 7 8 9 10 | |
If the input values \(n\) and \(m\) are taken as the data size, the time complexity of the above code is \(\Theta(n^2m)\).
DFS
When performing DFS on a graph with \(n\) vertices and \(m\) edges, since each vertex and edge is visited a constant number of times, the complexity is \(\Theta(n+m)\).
Which Quantities Are Constants?
When we perform a series of operations, how do we determine whether these operations affect the time complexity? For example:
1 2 3 4 | |
1 2 3 | |
1 2 3 4 | |
If \(N\) is not considered part of the input size, the time complexity of this code is \(O(1)\).
When calculating time complexity, it is important to determine which variables are considered part of the input size. All quantities independent of the input size are treated as constants and can be regarded as \(1\) during complexity calculation.
Note that in theoretical discussions about time complexity, a basic assumption is that "the algorithm can solve problems of any size" (though in practice, due to limited time and storage, problems that are too large cannot be solved). Therefore, solving a problem of limited data size in constant time (e.g., precomputing answers for all possible inputs within the data range) does not make the algorithm's time complexity \(O(1)\).
Master Theorem
We can use the Master Theorem to quickly determine the complexity of recursive algorithms. The recurrence relation of the Master Theorem is as follows:
Then
Note that the second case also requires the regularity condition: \(a f(n/b) \leq c f(n)\) for some constant \(c < 1\) and sufficiently large \(n\).
The proof idea is to decompose a problem of size \(n\) into \(a\) subproblems of size \((\frac{n}{b})\), then merge them step by step until reaching the top level. Each merge of subproblems takes \(f(n)\) time.
Proof
Following the proof idea mentioned above, the specific proof process is as follows:
For level \(0\) (the top level), merging subproblems takes \(f(n)\) time.
For level \(1\) (the first division of subproblems), there are \(a\) subproblems, and merging each takes \(f\left(\frac{n}{b}\right)\) time, so the total merging time is \(a f\left(\frac{n}{b}\right)\).
Continuing recursively, we can draw the recursion tree as follows: 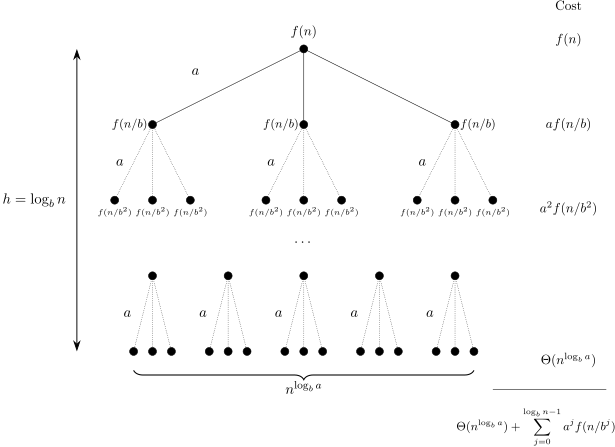
The height of this tree is \({\log_b n}\), and there are \(n^{\log_b a}\) leaves. Thus, \(T(n) = \Theta(n^{\log_b a}) + g(n)\), where \(g(n) = \sum_{j = 0}^{\log_{b}{n - 1}} a^{j} f(n / b^{j})\).
For the first case: \(f(n) = O(n^{\log_b a-\epsilon})\), so \(g(n) = O(n^{\log_b a})\).
For the second case: First, \(g(n) = \Omega(f(n))\). Also, since \(a f(\dfrac{n}{b}) \leq c f(n)\), as long as \(c\) is a sufficiently small positive number and \(n\) is sufficiently large, we can deduce that \(g(n) = O(f(n))\). Squeezing from both sides gives \(g(n) = \Theta(f(n))\).
For the third case: \(f(n) = \Theta(n^{\log_b a})\), so \(g(n) = O(n^{\log_b a} {\log n})\). The result for \(T(n)\) follows obviously after obtaining \(g(n)\).
Here are a few examples to illustrate how to use the Master Theorem.
- \(T(n) = 2T\left(\frac{n}{2}\right) + 1\). Here, \(a=2, b=2, {\log_2 2} = 1\). Then \(\epsilon\) can be chosen in \((0, 1]\) to satisfy the first case, so \(T(n) = \Theta(n)\).
- \(T(n) = T\left(\frac{n}{2}\right) + n\). Here, \(a=1, b=2, {\log_2 1} = 0\). Then \(\epsilon\) can be chosen in \((0, 1]\) to satisfy the second case, so \(T(n) = \Theta(n)\).
- \(T(n) = T\left(\frac{n}{2}\right) + {\log n}\). Here, \(a=1, b=2, {\log_2 1}=0\). Then \(k\) can be set to \(1\) to satisfy the third case, so \(T(n) = \Theta(\log^2 n)\).
- \(T(n) = T\left(\frac{n}{2}\right) + 1\). Here, \(a=1, b=2, {\log_2 1} = 0\). Then \(k\) can be set to \(0\) to satisfy the third case, so \(T(n) = \Theta(\log n)\).
Amortized Complexity
For details, see Amortized Complexity.
Space Complexity
Similarly, the trend of the space used by an algorithm as the input size changes can be measured by space complexity.
Computational Complexity
This article primarily introduces complexity from the perspective of algorithm analysis. If interested, you can explore further in Computational Complexity.
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用