Prefix Function & KMP Algorithm
Definitions of String Prefix and Suffix
For definitions of string prefix, proper prefix, suffix, and proper suffix, refer to String Basics.
Prefix Function
Definition
Given a string \(s\) of length \(n\), its prefix function is defined as an array \(\pi\) of length \(n\). Here \(\pi[i]\) is defined as:
- If the substring \(s[0\dots i]\) has an equal proper prefix and proper suffix: \(s[0\dots k-1]\) and \(s[i - (k - 1) \dots i]\), then \(\pi[i]\) is the length of this equal proper prefix (or proper suffix, since they are equal), i.e., \(\pi[i]=k\);
- If there is more than one such pair, then \(\pi[i]\) is the length of the longest one;
- If there is no such pair, then \(\pi[i]=0\).
Simply put, \(\pi[i]\) is the length of the longest equal proper prefix and proper suffix of the substring \(s[0\dots i]\).
In mathematical terms:
Specifically, it is defined that \(\pi[0]=0\).
Process
For example, for the string abcabcd,
\(\pi[0]=0\), because a has no proper prefix and proper suffix, defined as 0 by convention.
\(\pi[1]=0\), because ab has no equal proper prefix and proper suffix.
\(\pi[2]=0\), because abc has no equal proper prefix and proper suffix.
\(\pi[3]=1\), because abca has only one pair of equal proper prefix and proper suffix: a, of length 1.
\(\pi[4]=2\), because abcab has only ab as equal proper prefix and proper suffix, of length 2.
\(\pi[5]=3\), because abcabc has only abc as equal proper prefix and proper suffix, of length 3.
\(\pi[6]=0\), because abcabcd has no equal proper prefix and proper suffix.
Similarly, the prefix function for the string aabaaab can be computed as \([0, 1, 0, 1, 2, 2, 3]\).
Naive Algorithm for Computing the Prefix Function
Process
A straightforward algorithm to compute the prefix function according to the definition:
- In a loop, compute the prefix function values \(\pi[i]\) for \(i = 1\to n - 1\) (with \(\pi[0]\) assigned as \(0\)).
- To compute the current prefix function value \(\pi[i]\), we let variable \(j\) start from the largest possible proper prefix length \(i\).
- If the proper prefix and proper suffix of current length are equal, then the length is \(\pi[i]\); otherwise, decrement \(j\) by 1 and continue matching until \(j=0\).
- If \(j = 0\) and no match is found, set \(\pi[i] = 0\) and move to the next index \(i + 1\).
Implementation
The specific implementation is as follows:
1 2 3 4 5 6 7 8 9 10 11 12 13 | |
1 2 3 4 5 6 7 8 9 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 | |
Clearly, the time complexity of this algorithm is \(O(n^3)\), leaving much room for improvement.
Efficient Algorithm for Computing the Prefix Function
First Optimization
The first important observation is that adjacent prefix function values increase by at most \(1\).
Refer to the diagram below: when trying to maximize \(\pi[i+1]\), the newly added character \(s[i+1]\) must match the corresponding character, i.e., \(s[i+1]=s[\pi[i]]\), in which case \(\pi[i+1] = \pi[i]+1\).
Therefore, when moving to the next position, the prefix function value either increases by one, stays the same, or decreases.
Implementation
The improved algorithm is as follows:
1 2 3 4 5 6 7 8 9 10 11 | |
1 2 3 4 5 6 7 8 9 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 | |
In this preliminary improved algorithm, when computing each \(\pi[i]\), the best case is when the first string comparison completes the match, meaning the base number of string comparisons is n-1.
Due to the limit j = pi[i-1]+1 (pi[0]=0) on the maximum number of string comparisons, we can see that only in the best case does the upper bound of string comparisons accumulate by 1, while each extra string comparison consumes future growth space.
Thus, we can derive the worst-case scenario for string comparisons: at least 1 string comparison is consumed, and at most n-2 comparisons are accumulated, resulting in n-1 + n-2 = 2n-3 string comparisons.
After this optimization, computing the prefix function requires only \(O(n)\) string comparisons, reducing the total complexity to \(O(n^2)\).
Second Optimization
In the first optimization, we discussed the best case for computing \(\pi[i+1]\): \(s[i+1]=s[\pi[i]]\), in which case \(\pi[i+1] = \pi[i]+1\). Now let's go further along this line: discuss how to jump when \(s[i+1] \neq s[\pi[i]]\).
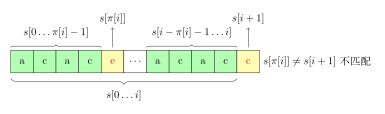
As shown in the figure above, when a mismatch occurs, we want to find the second longest length \(j\) for the substring \(s[0\dots i]\), after \(\pi[i]\), such that the prefix property at position \(i\) still holds, i.e., \(s[0 \dots j - 1] = s[i - j + 1 \dots i]\):
If we find such a length \(j\), we only need to compare \(s[i + 1]\) and \(s[j]\) again. If they are equal, then \(\pi[i + 1] = j + 1\). Otherwise, we need to find the second longest length \(j^{(2)}\) for substring \(s[0\dots i]\), after \(j\), such that the prefix property holds, and so on, until \(j = 0\). If \(s[i + 1] \neq s[0]\), then \(\pi[i + 1] = 0\). The second comparison is illustrated below.
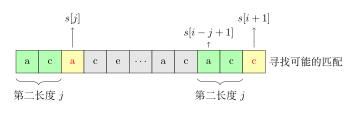
Observing the figure above, because \(s[0\dots \pi[i]-1] = s[i-\pi[i]+1\dots i]\), for the second length \(j\) of \(s[0\dots i]\), we have the property:
This formula is illustrated below:
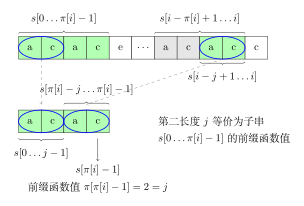
That is, \(j\) is equivalent to the prefix function value of substring \(s[\pi[i]-1]\), corresponding to the lower part of the figure above, i.e., \(j=\pi[\pi[i]-1]\). Similarly, the second length after \(j\) is equivalent to the prefix function value of \(s[j-1]\), \(j^{(2)}=\pi[j-1]\).
Clearly, we can obtain a state transition equation for \(j\): \(j^{(n)}=\pi[j^{(n-1)}-1], \ \ (j^{(n-1)}>0)\).
Final Algorithm
Thus, we can finally construct an algorithm that requires no string comparisons and performs only \(O(n)\) operations.
Moreover, the implementation of this algorithm is surprisingly short and intuitive:
Implementation
1 2 3 4 5 6 7 8 9 10 11 | |
1 2 3 4 5 6 7 8 9 10 11 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 | |
This is an online algorithm, meaning it processes data as it arrives—for example, you can read the string character by character and immediately compute the prefix function value for each character. The algorithm still needs to store the string itself and previously computed prefix function values, but if we already know the maximum possible value \(M\) of the prefix function for the string, we only need to store the first \(M + 1\) characters of the string and their corresponding prefix function values.
Applications
Finding a Substring in a String: Knuth–Morris–Pratt Algorithm
This algorithm was jointly published by Knuth, Pratt, and Morris in 1977[^kmp]. This task is a typical application of the prefix function.
Process
Given a text \(t\) and a string \(s\), we try to find and display all occurrences of \(s\) in \(t\).
For simplicity, let \(n\) denote the length of string \(s\), and \(m\) denote the length of text \(t\).
We construct a string \(s + \# + t\), where \(\#\) is a separator that does not appear in \(s\) or \(t\). Then compute the prefix function of this string. Now consider the meaning of the prefix function values after the first \(n + 1\) values (i.e., those belonging to the string \(s\) and the separator). By definition, \(\pi[i]\) is the length of the longest proper substring that ends at \(i\) and is also a prefix. In our case, its value is the length of the longest substring ending at \(i\) that is equal to a prefix of \(s\). Due to the separator, this length cannot exceed \(n\). If the equality \(\pi[i] = n\) holds, it means \(s\) appears completely at that position (i.e., its right endpoint is at position \(i\)). Note that this index refers to the string \(s + \# + t\).
Therefore, if \(\pi[i] = n\) at some position \(i\), then string \(s\) appears in string \(t\) at position \(i - (n - 1) - (n + 1) = i - 2n\). The diagram below illustrates the indices.
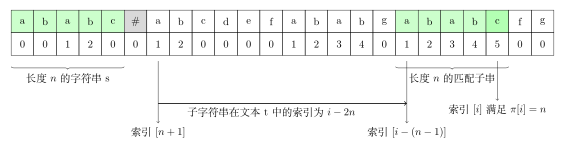
As mentioned in the computation of the prefix function, if we know that the prefix function values never exceed a certain value, we do not need to store the entire string and the entire prefix function, but only the beginning part of both. In our case, this means we only need to store the string \(s + \#\) and the corresponding prefix function values. We can read the characters of string \(t\) one by one and compute the prefix function value at the current position.
Thus, the Knuth–Morris–Pratt algorithm (KMP algorithm) solves this problem in \(O(n + m)\) time and \(O(n)\) memory.
Implementation
1 2 3 4 5 6 7 8 9 10 | |
1 2 3 4 5 6 7 8 9 | |
1 2 3 4 5 6 7 8 9 10 11 12 | |
Period of a String
For a string \(s\) and \(0 < p \le |s|\), if \(s[i] = s[i+p]\) holds for all \(i \in [0, |s| - p - 1]\), then \(p\) is called a period of \(s\).
For a string \(s\) and \(0 \le r < |s|\), if the prefix of length \(r\) and the suffix of length \(r\) of \(s\) are equal, then the prefix of length \(r\) is called a border of \(s\).
Having a border of length \(r\) for \(s\) implies that \(|s|-r\) is a period of \(s\).
According to the definition of the prefix function, we can obtain all border lengths of \(s\), i.e., \(\pi[n-1],\pi[\pi[n-1]-1], \ldots\).[^ref1]
Thus, all periods of \(s\) can be computed in \(O(n)\) time using the prefix function. Since \(\pi[n-1]\) is the length of the longest border of \(s\), \(n - \pi[n-1]\) is the minimum period of \(s\).
Counting Occurrences of Each Prefix
In this section, we will discuss two problems simultaneously. Given a string \(s\) of length \(n\), in the first variant we want to count the number of occurrences of each prefix \(s[0 \dots i]\) in the same string, and in the second variant we want to count the number of occurrences of each prefix \(s[0 \dots i]\) in another given string \(t\).
First, let's solve the first problem. Consider the prefix function value \(\pi[i]\) at position \(i\). By definition, it means that a prefix of \(s\) of length \(\pi[i]\) appears at position \(i\) with \(i\) as the right endpoint, and no longer prefix satisfies this definition. Meanwhile, shorter prefixes may also end at this position. It is easy to see that we encounter a problem already answered when computing the prefix function: given a prefix of length \(j\) that is also a suffix ending at \(i\), what is the next smaller prefix length \(k < j\)? This length must also be a suffix ending at \(i\). Therefore, at position \(i\) as the right endpoint, there is a prefix of length \(\pi[i]\), a prefix of length \(\pi[\pi[i] - 1]\), a prefix of length \(\pi[\pi[\pi[i] - 1] - 1]\), and so on, until the length becomes \(0\). Thus, we can compute the answer as follows.
Implementation
1 2 3 4 | |
1 2 3 4 5 6 7 | |
Explanation
In the above code, we first count how many times each prefix function value appears in the array \(\pi\), then compute the final answer: if we know that a prefix of length \(i\) appears exactly \(\text{ans}[i]\) times, then this value must be added to the occurrence count of its longest substring that is both a suffix and a prefix. Finally, to count the original prefixes, we add \(1\) to each result.
Now consider the second problem. We apply the trick from Knuth–Morris–Pratt: construct a string \(s + \# + t\) and compute its prefix function. The only difference from the first problem is that we only care about prefix function values related to string \(t\), i.e., \(\pi[i]\) for \(i \ge n + 1\). With these values, we can apply the same algorithm as in the first problem.
Number of Distinct Substrings in a String
Given a string \(s\) of length \(n\), we want to compute the number of its distinct substrings.
We will solve this problem iteratively. In other words, knowing the current number of distinct substrings, we want to find a way to recompute this number after appending a character to the end of \(s\).
Let \(k\) be the current number of distinct substrings of \(s\). We append a new character \(c\) to \(s\). Obviously, some new substrings ending with character \(c\) will appear. We want to count those substrings ending with this character that we have not encountered before.
Construct the string \(t = s + c\) and reverse it to get \(t^{\sim}\). Now our task becomes counting how many prefixes of \(t^{\sim}\) do not appear anywhere else in \(t^{\sim}\). If we compute the maximum prefix function value \(\pi_{\max}\) of \(t^{\sim}\), then the longest prefix that appears in \(s\) has length \(\pi_{\max}\). Naturally, all shorter prefixes also appear.
Therefore, the number of new substrings that appear after adding a new character is \(|s| + 1 - \pi_{\max}\).
So for each added character, we can compute the number of new substrings in \(O(n)\) time, resulting in a final complexity of \(O(n^2)\).
It is worth noting that we can also recompute the number of distinct substrings when adding a character at the head, or removing a character from the tail or head.
String Compression
Given a string \(s\) of length \(n\), we want to find its shortest "compressed" representation, i.e., we want to find the shortest string \(t\) such that \(s\) can be represented as the concatenation of one or more copies of \(t\).
Obviously, we only need to find the length of \(t\). Knowing this length, the answer is the prefix of \(s\) of that length.
Let's compute the prefix function of \(s\). Using the last value \(\pi[n - 1]\), we define \(k = n - \pi[n - 1]\). We will prove that if \(k\) divides \(n\), then \(k\) is the answer; otherwise, no valid compression exists, so the answer is \(n\).
Assume \(n\) is divisible by \(k\). Then the string can be divided into blocks of length \(k\). According to the definition of the prefix function, the prefix of length \(n - k\) equals its suffix. But this means the last block equals the second last block, the second last block equals the third last block, and so on. As a result, all blocks are equal, so we can compress the string \(s\) to length \(k\).
Proof
Indeed, we still need to prove that this value is optimal. Actually, if there is a compressed representation shorter than \(k\), then the last prefix function value \(\pi[n - 1]\) must be greater than \(n - k\). Therefore, \(k\) is the answer.
Now assume \(n\) is not divisible by \(k\). We will prove by contradiction that the answer is \(n\)1. Suppose the minimal compressed representation \(r\) has length \(p\) (\(p\) divides \(n\)), and string \(s\) is divided into \(n / p \ge 2\) blocks. Then the last prefix function value \(\pi[n - 1]\) must be greater than \(n - p\) (if equal, then \(n\) would be divisible by \(k\)), meaning the suffix it represents partially covers the first block. Now consider the second block of the string. This block has two interpretations: the first as \(r_0 r_1 \dots r_{p - 1}\), and the second as \(r_{p - k} r_{p - k + 1} \dots r_{p - 1} r_0 r_1 \dots r_{p - k - 1}\). Since both interpretations correspond to the same string, we obtain a system of \(p\) equations, which can be simplified as \(r_{(i + k) \bmod p} = r_{i \bmod p}\), where \(\cdot \bmod p\) denotes the least non-negative residue modulo \(p\).
According to the extended Euclidean algorithm, we can find integers \(x\) and \(y\) such that \(xk + yp = \gcd(k, p)\). By appropriately combining with the identity \(pk - kp = 0\), we can obtain \(x' > 0\) and \(y' < 0\) such that \(x'k + y'p = \gcd(k, p)\). This means that by repeatedly applying the equations from the system, we obtain a new system \(r_{(i + \gcd(k, p)) \bmod p} = r_{i \bmod p}\).
Since \(\gcd(k, p)\) divides \(p\), this means \(\gcd(k, p)\) is a period of \(r\). Because \(\pi[n - 1] > n - p\), we have \(n - \pi[n - 1] = k < p\), so \(\gcd(k, p)\) is a period of \(r\) smaller than \(p\). Therefore, string \(s\) has a compressed representation of length \(\gcd(k, p) < p\), contradicting the minimality of \(p\).
In conclusion, there is no compressed representation shorter than \(k\), so the answer is \(k\).
Building an Automaton Based on the Prefix Function
Let's return to the new string formed by concatenating two strings with a separator. For strings \(s\) and \(t\), we compute the prefix function of \(s + \# + t\). Obviously, because \(\#\) is a separator, the prefix function value never exceeds \(|s|\). Therefore, we only need to store the string \(s + \#\) and its corresponding prefix function values, and then we can dynamically compute the prefix function values for all subsequent characters:
Actually, in this case, knowing the next character \(c\) of \(t\) and the previous prefix function value is sufficient to compute the next prefix function value, without needing any other characters of \(t\) or their corresponding prefix function values.
In other words, we can construct an automaton (a finite state machine): its states are the current prefix function values, and transitions from one state to another are determined by the next character.
Therefore, even without the string \(t\), we can apply the algorithm for constructing the transition table to build a transition table \(( \text { old } \pi , c ) \rightarrow \text { new } _ { - } \pi\):
Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 | |
However, in this form, for a lowercase alphabet, the time complexity is \(O(|\Sigma|n^2)\). Note that we can apply dynamic programming to reuse already computed parts of the table. Whenever we change from value \(j\) to \(\pi[j - 1]\), we are essentially saying that the state reached by transition \((j, c)\) is the same as that reached by transition \((\pi[j - 1], c)\), but we have already computed that answer precisely.
Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 | |
Finally, we can construct the automaton in \(O(|\Sigma|n)\) time.
When is this automaton useful? First, recall that most of the time we use the prefix function of the string \(s + \# + t\) for one purpose: finding all occurrences of string \(s\) in string \(t\).
Therefore, the most direct benefit of using this automaton is accelerating the computation of the prefix function for \(s + \# + t\).
By building the automaton for \(s + \#\), we no longer need to store the string \(s\) and its corresponding prefix function values. All transitions are already computed in the table.
But besides that, there is a second, less direct application. We can use this automaton to accelerate computation when string \(t\) is some huge string constructed by certain rules. Examples include Gray strings, or strings constructed recursively from shorter input strings.
For completeness, let's solve such a problem: given a number \(k \le 10^5\), and a string \(s\) of length \(\le 10^5\), we need to compute the number of occurrences of \(s\) in the \(k\)-th Gray string. Recall that Gray strings are defined as follows:
Due to their astronomical lengths, constructing string \(t\) is impossible in this case: the \(k\)-th Gray string has \(2^k - 1\) characters. However, we can efficiently compute the prefix function value at the end of the string by knowing only a few initial prefix function values.
Besides the automaton, we also need to compute values \(G[i][j]\): the state of the automaton after processing \(g_i\) starting from state \(j\), and values \(K[i][j]\): the number of occurrences of \(s\) in \(g_i\) when starting from state \(j\). Actually, \(K[i][j]\) is the number of times the prefix function takes the value \(|s|\) during the operation. The answer to the problem is clearly \(K[k][0]\).
How do we compute these values? First, by definition, the initial conditions are \(G[0][j] = j\) and \(K[0][j] = 0\). All subsequent values can be computed from previous values using the automaton. To compute the values for some \(i\), recall that string \(g_i\) is the concatenation of \(g_{i - 1}\), the \(i\)-th character of the alphabet, and \(g_{i - 1}\). Therefore, the automaton goes through the following states:
The value of \(K[i][j]\) can also be computed simply.
where \([\cdot]\) is \(1\) if the expression is true, otherwise \(0\). In summary, we can now solve the problem about Gray strings and a large class of similar problems. For example, the same method can solve the following problem: given a string \(s\) and some patterns \(t_i\), where each pattern is given as follows: the pattern consists of ordinary characters, possibly with recursive insertions of previous strings in the form \(t_{k}^{\text{cnt}}\), meaning at that position we must insert string \(t_k\) \(\text{cnt}\) times. Here is an example of such patterns:
Recursive substitution causes string lengths to explode, reaching magnitudes like \(100^{100}\). Yet we must find the number of occurrences of string \(s\) in each string.
This problem can also be solved by constructing a prefix function automaton. As before, we compute transitions for each pattern using previously computed results and count the answer accordingly.
Practice Problems
- UVa 455 "Periodic Strings"
- UVa 11022 "String Factoring"
- UVa 11452 "Dancing the Cheeky-Cheeky"
- UVa 12604 - Caesar Cipher
- UVa 12467 - Secret Word
- UVa 11019 - Matrix Matcher
- SPOJ - Pattern Find
- Codeforces - Anthem of Berland
- Codeforces - MUH and Cube Walls
References and Notes
**This page is mainly translated from the blog post [Префикс-функция. Алгоритм Кнута-Морриса-Пратта
-
In the Russian and English versions, this part of the proof appears to be erroneous. This part of the proof in this article is added by the author. ↩
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用