Virtual Tree
Introduction
「SDOI2011」消耗战
In a war, the battlefield consists of \(n\) islands and \(n-1\) bridges, ensuring there is exactly one path between any two islands. Our army has discovered that the enemy headquarters is on island number \(1\), and they no longer have enough energy to sustain the battle, so victory is within our grasp. It is known that there are abundant energy resources on \(k\) other islands. To prevent the enemy from obtaining these resources, our mission is to destroy some bridges so that the enemy cannot reach any energy-rich island. Since different bridges have different materials and structures, destroying them incurs different costs. Our army hopes to achieve the objective while minimizing the total cost.
The reconnaissance department also discovered that the enemy has a mysterious machine. Even after we cut off all energy sources, they can still use that machine. The machine not only repairs all bridges we destroyed but also randomly redistributes the resources (though it is guaranteed that resources will not be distributed to island \(1\)). However, the reconnaissance department also found that this machine can only be used \(m\) times, so we just need to complete each mission.
For all data, \(2\le n\le 2.5\times 10^5,1\le m\le 5\times 10^5,\sum k_i\le 5\times 10^5,1\le k_i\le n-1\).
Naive Approach
For the above problem, it is not hard to see—if the number of vertices in the tree is small, we can directly run DP.
First, we call the points selected in a query—"key points".
Let \(Dp(i)\) denote—the minimum cost to disconnect \(i\) from any key point in its subtree.
Let \(w(a,b)\) denote the weight of the edge between \(a\) and \(b\).
Then enumerate \(i\)'s child \(v\):
- If \(v\) is not a key point: \(Dp(i)=Dp(i) + \min \{Dp(v),w(i,v)\}\);
- If \(v\) is a key point: \(Dp(i)=Dp(i) + w(i,v)\).
Great, this gives us an \(O(nq)\) code.
Sounds interesting.
Optimized Approach
We can observe—actually many points are useless. Take the following figure as an example:
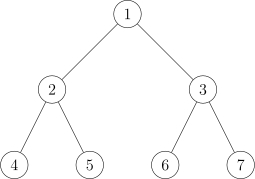
If the key points we select are:
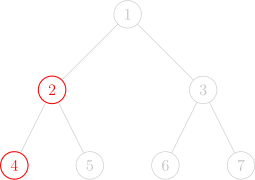
Only the two red points in the figure are key points, while all other points are "non-key points".
For this problem, we only need to ensure that the red points cannot reach node \(1\).
By visual inspection, we can conclude—there are no red points in the right subtree of node \(1\) (though there may actually be multiple subtrees, here there are only two, so we temporarily call it that), so there is no need to DP it.
Observing the conditions given in the problem, the total number of red points (key points) is of the same order as \(n\), meaning that in a single query, the red points are actually quite sparse relative to the whole tree. So if we could make the complexity depend on the total number of red points, that would be ideal.
Therefore, we need to condense information, compress a large tree into a small tree.
Virtual Tree
This leads us to the concept of "Virtual Tree".
Let's first visually see what a virtual tree looks like.
In the following figures, red nodes are the key points we selected. Both red and black nodes are points in the virtual tree. Black edges are edges in the virtual tree.
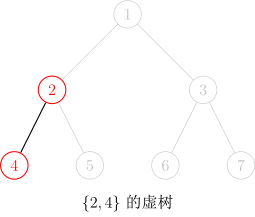
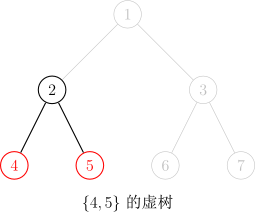
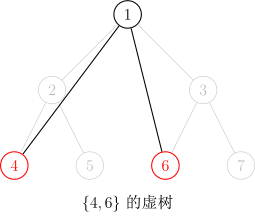
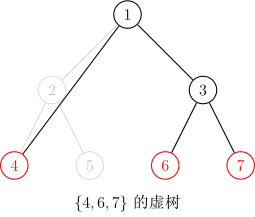
Because the LCA of any two key points also needs to preserve important information, we need to save their LCA, so the virtual tree does not necessarily contain only key points.
It is not hard to see that the ancestor-descendant relationships in the virtual tree do not change. (That is, there won't be weird situations like originally \(a\) is an ancestor of \(b\) but later \(a\) becomes a descendant of \(b\).)
But we cannot enumerate LCA in \(O(k^2)\) brute force, so we naturally think—first sort the key points by DFS order, then for every two adjacent key points (adjacent means the absolute difference of indices in the sorted sequence equals 1) compute their LCA and add it to the virtual tree.
Our urgent task is how to construct the virtual tree.
Before proposing a method, let's confirm a fact—in the virtual tree, as long as the ancestor-descendant relationships are preserved, we can add nodes arbitrarily.
That is, if we like, we can add all points from the original tree into the virtual tree without causing WA (though it would cause TLE).
Therefore, for convenience, we can first add node \(1\) to the virtual tree, and it will not affect the answer.
First Construction Method: Double Sorting + LCA Linking
Because the LCA of multiple nodes might be the same, we cannot add it to the virtual tree multiple times.
A very intuitive method is:
- Sort the key points by DFS order;
- Traverse once, compute the LCA for any two adjacent key points, and check for duplicates;
- Then build the tree according to the ancestor-descendant relationships in the original tree.
Specifically, in the key point sequence, enumerate each adjacent pair, compute their LCA and add it to sequence \(A\).
Due to the properties of DFS order, sequence \(A\) now contains all points in the virtual tree, but there may be duplicates.
So we sort sequence \(A\) by DFS order in ascending order and remove duplicates.
Finally, in sequence \(A\), enumerate each adjacent pair of point indices \(x,y\), compute their LCA and connect \(\operatorname{LCA}(x,y),y\). The virtual tree is then constructed.
Why does connecting \(\operatorname{LCA}(x,y)\) and \(y\) achieve no duplication and no omission?
Proof
If \(x\) is an ancestor of \(y\), then directly connect \(x\) to \(y\). Because DFS order ensures that \(x\) and \(y\) have adjacent DFS orders, there are no key points on the path from \(x\) to \(y\).
If \(x\) is not an ancestor of \(y\), then treat \(\operatorname{LCA}(x,y)\) as the ancestor of \(y\). According to the previous case, it can also be proven that there are no key points on the path from \(\operatorname{LCA}(x,y)\) to \(y\).
So connecting \(\operatorname{LCA}(x,y)\) and \(y\) will not miss or duplicate any connections.
Also, does it matter that the first point is not connected by a node? Since the first point must be the root of this tree, it doesn't matter, so the total number of edges is \(m-1\).
Because at least two real points are needed to summon a virtual point, plus a root node, the number of points in the virtual tree is twice the number of real points.
Time complexity is \(O(m\log n)\), where \(m\) is the number of key points and \(n\) is the total number of points.
Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 | |
Actually, this is enough to construct a virtual tree.
Second Construction Method: Using a Monotonic Stack
How to construct a virtual tree using a monotonic stack?
First, we need to clarify a purpose—we will use a monotonic stack to maintain a chain on the virtual tree.
That is, two adjacent nodes in the stack are also adjacent on the virtual tree, and the stack is monotonically increasing from bottom to top (meaning the DFS order of nodes in the stack is monotonically increasing). In simple terms, the parent of a node is the node below it in the stack.
First, we push node \(1\) into the stack.
Then, we add key nodes in increasing DFS order.
If the LCA of the current node and the top node of the stack is exactly the top node, then they are on the same chain. So we can simply push the current node onto the stack.
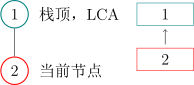
If the LCA of the current node and the top node of the stack is not the top node:
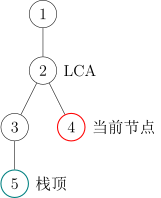
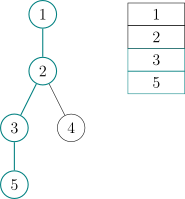
At this point, the chain maintained by the current monotonic stack is:
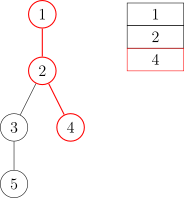
And we need to change the chain to:
So we pop the nodes marked with dashed lines from the stack. Before popping, don't forget to connect edges to its parent in the virtual tree.
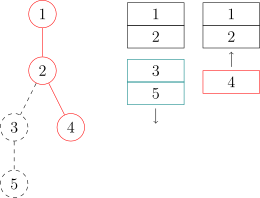
If after popping, the top of the stack is not the LCA, then push the LCA onto the stack.
Then push the current node onto the stack.
Below is a concrete example. Suppose we want to build a virtual tree for nodes 4, 6, and 7 of the following tree:
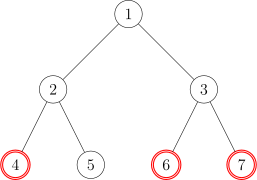
The steps are as follows:
- Sort the 3 key points \(6,4,7\) by DFS order, obtaining sequence \([4,6,7]\).
- Push \(1\) onto the stack.
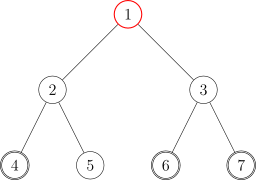
We use red points to represent points in the stack, and cyan points to represent points popped from the stack.
- Take the first element in the sequence as the current node, which is \(4\). Then take the top element of the stack, which is \(1\). Compute the LCA of \(1\) and \(4\): \(LCA(1,4)=1\).
- Find that \(LCA(1,4)=\) the top element of the stack, meaning they are on the same chain in the virtual tree, so directly push the current node \(4\) onto the stack. The current stack is \(4,1\).
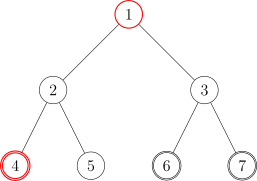
- Take the second element in the sequence as the current node, which is \(6\). Then take the top element of the stack, which is \(4\). Compute the LCA of \(6\) and \(4\): \(LCA(6,4)=1\).
- Find that \(LCA(6,4)\neq\) the top element of the stack, enter the judgment phase.
- Judgment phase: Find that the DFS order of the top node \(4\) is greater than \(LCA(6,4)\), but the DFS order of the second-largest node (the node below the top node) \(1\) is equal to the LCA's (actually equal DFS order means equal nodes), meaning the LCA is already in the stack, so directly connect the edge \(1\to4\), i.e., the edge from LCA to the top element. And pop \(4\) from the stack.
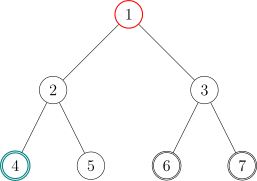
- End the judgment phase, push \(6\) onto the stack. The current stack is \(6,1\).
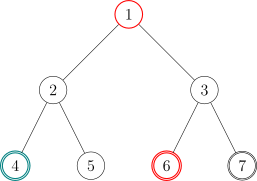
- Take the third element in the sequence as the current node, which is \(7\). Then take the top element of the stack, which is \(6\). Compute the LCA of \(7\) and \(6\): \(LCA(7,6)=3\).
- Find that \(LCA(7,6)\neq\) the top element of the stack, enter the judgment phase.
- Judgment phase: Find that the DFS order of the top node \(6\) is greater than \(LCA(7,6)\), but the DFS order of the second-largest node (the node below the top node) \(1\) is less than the LCA's, meaning the LCA has not been pushed onto the stack yet, so directly connect the edge \(3\to6\), i.e., the edge from LCA to the top element. Pop \(6\) from the stack, and push \(LCA(6,7)\) onto the stack.
- End the judgment phase, push \(7\) onto the stack. The current stack is \(1,3,7\).
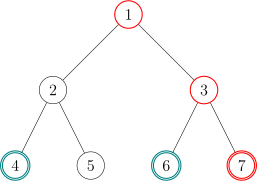
- Find that all 3 nodes in the sequence have been pushed onto the stack, exit the loop.
- Now there are still 3 nodes in the stack: \(1,3,7\). Clearly, they are on the same chain, so directly connect edges: \(1\to3\) and \(3\to7\).
- The virtual tree is now built!
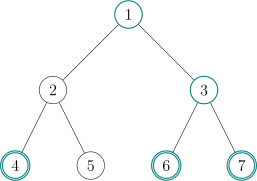
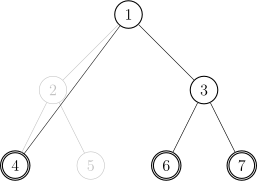
Next, we delete those points that never entered the stack (non-cyan points). The corresponding virtual tree looks like this:
There are many details. For example, if using an adjacency list to store the virtual tree, we need to clear the adjacency list. But clearing the entire adjacency list is slow, so we clear the adjacency list of an element when it is pushed onto the stack for the first time.
Implementation
The C++ code for building a virtual tree roughly looks like this:
Code Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 | |
Now we have learned how to build a virtual tree!
For the problem "消耗战", we can directly run the DP described earlier on the virtual tree. We essentially use the virtual tree to exclude those useless non-key nodes! Still consider all children \(v\) of \(i\):
- If \(v\) is not a key point: \(Dp(i)=Dp(i) + \min \{Dp(v),w(i,v)\}\)
- If \(v\) is a key point: \(Dp(i)=Dp(i) + w(i,v)\)
Thus, this problem is solved simply.
Recommended Exercises
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用