Huffman Tree
Weighted Path Length of Tree
Given a binary tree with \(n\) weighted leaf nodes, the sum of the products of the path length from the root to each leaf node and the weight of the corresponding leaf node is called the Weighted Path Length of Tree (WPL).
Let \(w_i\) be the weight of the \(i\)-th leaf node in the binary tree, and \(l_i\) be the path length from the root to the \(i\)-th leaf node. The formula for WPL is as follows:
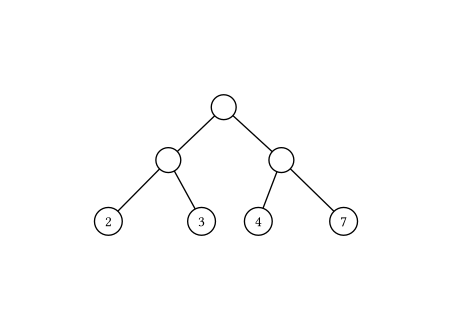
As shown in the figure above, the calculation process and result of its WPL are as follows:
Structure
For a given set of leaf nodes with determined weights, different binary trees can be constructed. Among them, the binary tree with the smallest WPL is called the Huffman Tree.
For a Huffman tree, leaf nodes with smaller weights are farther from the root, while leaf nodes with larger weights are closer to the root. Additionally, only leaf nodes have degree \(0\), while all other nodes have degree \(2\).
Huffman Algorithm
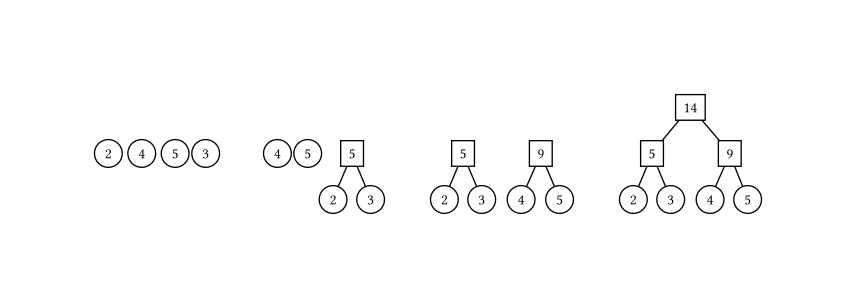
The Huffman algorithm is used to construct a Huffman tree. The steps are as follows:
- Initialization: Construct \(n\) binary trees, each with only a root node, from the given \(n\) weights, resulting in a binary tree set \(F\).
- Selection and Merging: From the binary tree set \(F\), select the two binary trees with the smallest root node weights as the left and right subtrees to construct a new binary tree. The weight of the root node of this new binary tree is the sum of the weights of the left and right subtree root nodes.
- Deletion and Addition: Remove the two binary trees used as left and right subtrees from \(F\), and add the newly constructed binary tree to \(F\).
- Repeat steps 2 and 3 until only one binary tree remains in the set. This binary tree is the Huffman tree.
Proof of Correctness
Lemma
In an optimal prefix coding tree (Huffman tree), the two leaf nodes with the smallest weights are always the deepest leaf nodes, and adjusting these two nodes to be siblings will not break the optimality of the coding tree.
Proof
We prove this proposition by contradiction. Assume that in an optimal prefix coding tree, there exist two leaf nodes with the smallest weights that are not the deepest leaf nodes. Let these two nodes be \(a\) and \(b\), and their depth is less than some deepest leaf node. For this deepest leaf node \(c\), we can swap the positions of \(a\) and \(c\), or swap the positions of \(b\) and \(c\). Since the Huffman algorithm ensures that the tree merges the leaf nodes with the smallest weights at each level, after swapping, the Weighted Path Length (WPL) of the tree will decrease. This contradiction shows that the assumption is false, so the two leaf nodes with the smallest weights must be the deepest leaf nodes.
Next, assume that these two leaf nodes with the smallest weights are \(a\) and \(b\), and they have the same depth. If in an optimal prefix coding tree these two nodes are not siblings, suppose there are other nodes \(c\) and \(d\) that are siblings of \(a\) and \(b\), respectively (assuming \(a\) and \(c\) are siblings, and \(b\) and \(d\) are siblings). We can merge \(a\) and \(b\) into a subtree.
- If the sum of the weights of \(a\) and \(b\) after merging is less than the weight of \(c\) or \(d\), then we can merge the resulting subtree with the node with the larger weight (e.g., \(c\) or \(d\)) to form a new subtree, and the WPL will decrease.
- If the sum of the weights of \(a\) and \(b\) is not less than the weights of \(c\) and \(d\), we can directly adjust \(a\) and \(b\) to be siblings, and \(c\) and \(d\) to be another pair of siblings, and the WPL will not increase.
Therefore, after such adjustments, optimality will not be broken, proving the lemma.
Theorem
The prefix coding tree obtained by the Huffman algorithm is an optimal prefix coding tree.
Proof
We prove this theorem using mathematical induction.
- Base Case: When the number of letters \(n = 2\), it is clear that directly merging the two letters into a tree is the optimal coding tree.
- Inductive Hypothesis: Assume that for \(n = k\) letters (\(k \geq 2\)), the Huffman algorithm can produce an optimal prefix coding tree.
- Inductive Step: For \(n = k + 1\) letters, we select the two letters with the smallest weights from the \(k+1\) letters and merge them into a subtree, with the root of the subtree acting as a virtual letter (virtual node). According to the lemma, this operation will not break the optimality of the prefix coding tree. Now, the virtual letter and the remaining \(k\) letters together form \(k + 1\) letters. By the inductive hypothesis, when the number of letters is \(k\), the Huffman algorithm can produce an optimal prefix coding tree.
Therefore, by mathematical induction, the Huffman algorithm can produce an optimal prefix coding tree for any number of letters \(n\), proving the theorem.
Huffman Coding
In programming, it is common to assign a unique code to each character to represent a set of characters, which is called coding.
In binary coding, assuming all codes are of equal length, representing \(n\) distinct characters requires \(\left \lceil \log_2 n \right \rceil\) bits, which is called fixed-length coding.
If each character has equal frequency of use, then fixed-length coding is undoubtedly the most space-efficient coding method. However, if characters appear with different frequencies, we can assign shorter codes to characters with higher frequencies and longer codes to characters with lower frequencies, constructing a variable-length coding to achieve better space efficiency.
When designing variable-length coding, the uniqueness of decoding must be considered. If no code in a set of codes is a prefix of any other code in the set, then this set of codes is called a prefix code, which ensures the uniqueness of decoding.
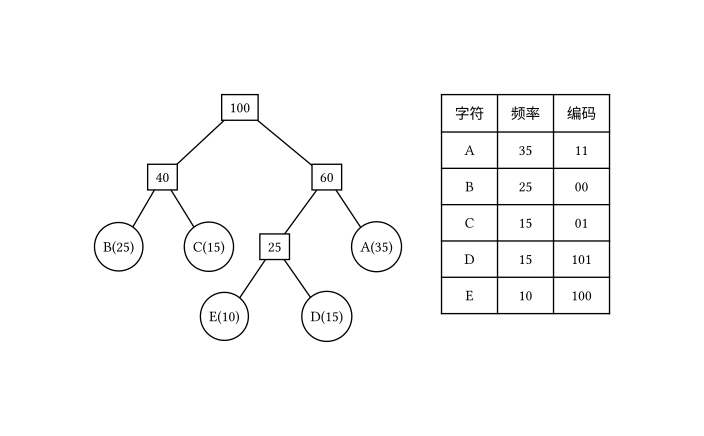
The Huffman tree can be used to construct the shortest prefix code, known as Huffman Code. The construction steps are as follows:
- Let the character set to be encoded be: \(d_1,d_2,\dots,d_n\), and their frequencies in the string be: \(w_1,w_2,\dots,w_n\).
- Use \(d_1,d_2,\dots,d_n\) as leaf nodes and \(w_1,w_2,\dots,w_n\) as the weights of the leaf nodes to construct a Huffman tree.
- Define the left branch of the Huffman coding tree to represent \(0\) and the right branch to represent \(1\). Then, the sequence of \(0\)s and \(1\)s along the path from the root to each leaf node is the code for the character corresponding to that leaf node.
Example Code
Construction of Huffman Tree
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 | |
Calculate WPL of Constructed Huffman Tree
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 | |
Directly Calculate WPL for an Unconstructed Huffman Tree
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 | |
Calculate Huffman Code for a Given Sequence
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 | |
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用