Compilation Optimizations
The commonly used programming language in the OI community is C++. Since this language is used, it inevitably involves dealing with compilers and language standards. As is well known, C++ is quite chaotic and evil. This article aims to provide practical knowledge about compilers, sufficient for competitive programming.
Introduction to Compiler Optimizations
What is Optimization
According to the as-if Rule, improvements are made to program execution speed and executable file size while preserving semantics.
Common Compiler Optimizations
Constant Folding
Constant folding, also known as constant propagation, if an expression can be determined to be a constant, constant propagation can be performed before its next definition.
1 2 3 4 5 | |
This code can be transformed during compilation into:
1 2 3 4 5 | |
Example: https://godbolt.org/z/oEfY35TTd
Dead Code Elimination
As the name suggests, code that is not used will be removed.
1 2 3 4 5 6 | |
Will be transformed into
1 | |
Note that this code first undergoes constant folding, making the return value determinable as 234, and a, b become inactive variables, thus they are removed.
Loop Rotate
Transform a loop from "for" form to "do-while" form, with an additional conditional check in front. This transformation mainly prepares for other transformations.
1 2 3 4 | |
Transformed into
1 2 3 4 5 6 7 | |
Loop Invariant Code Motion
Based on alias analysis, code within the loop that is proven to be invariant (may involve memory access, load/store, thus relying on alias analysis) is hoisted out of the loop body, reducing code inside the loop.
1 2 3 4 | |
Intuitively, this code can be hoisted as:
1 2 3 4 | |
However, if n <= 0, the loop is never entered, but we executed an extra instruction (which may have side effects!). Therefore, loops are usually rotated into do-while form, making it convenient to insert a "loop guard". Then loop invariant code motion is performed.
1 2 3 4 5 6 7 | |
Loop Unroll
Loops contain loop bodies and various branch statements, requiring modern CPUs to perform branch prediction. Directly unrolling the loop trades code size for execution time.
1 2 3 | |
Transformed into:
1 2 3 | |
Loop Unswitching
Loop unswitching moves conditional expressions inside the loop outside, then places two loops under each external condition, increasing the possibility of loop vectorization and parallelization (usually simpler loops are easier to vectorize).
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 | |
Code Layout Optimizations
During program execution, execution paths can be divided into cold/hot paths. CPU jumps are generally slower than sequential execution, the latter often referred to as "fallthrough" by compiler writers. Correspondingly, frequently executed code is called hot code, while the opposite is cold code. In OI code, if there is a special boundary condition check within a loop, or exception handling, similar logic, such code is cold code.
A basic block is the basic structure of control flow. A procedure consists of several basic blocks forming a directed graph. During executable generation, the compiler needs to arrange a layout for placing basic blocks, and how to arrange the layout is the focus of this optimization.
In principle, hot code should be placed together, while cold code should be separated. The reason is to better utilize instruction cache, improving locality for hot code.
1 2 3 4 5 6 | |
Basic Block Placement
We use labels to express a kind of "pseudo-machine code". This C++ program has two translation methods:
Layout 1
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 | |
Another layout is:
Layout 2
1 2 3 4 5 6 7 8 9 10 11 12 13 | |
We see in the latter layout, two hot code blocks are placed together, resulting in better execution efficiency.
To inform the compiler whether a branch is likely to be taken, C++20 [[likely]] and [[unlikely]] can be used: https://en.cppreference.com/w/cpp/language/attributes/likely
If the competition does not use C++20 or above, __builtin_expect (GNU Extension) can be utilized.
1 2 3 4 5 6 | |
Hot Cold Splitting
A procedure contains both cold and hot paths, and the cold code is long. A better approach is to make the cold code a function call rather than blocking the hot path. This also suggests we should not be overly clever by making all functions inline. Cold code hinders execution speed much more than function calls.
Bad Code Layout
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 | |
Good Code Layout
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 | |
Hot cold splitting is essentially the reverse operation of function inlining. The existence of this optimization reveals that function inlining does not necessarily make programs faster. If the inlined code is cold, it might even slow down the program! Some compilers have forced inlining options, but they are not recommended. Compilers internally have a static analysis process, calculating probabilities for each basic block and branch, and a cost model related to function calls, to decide whether to inline. Self-decided inlining may not be better than the compiler's decision.
In fact, without additional information, compilers typically assume branch taken and not-taken probabilities are equal, propagating cold/hot degrees of control flow paths accordingly. Part of PGO (Profile Guided Optimization) involves obtaining actual program branch probabilities through several performance tests and experiments, making code layout better.
Function Inlining
Function calls usually require registers and stack to pass parameters, both caller and callee need to save certain register states, a process often called calling convention. A function call thus incurs some time overhead. Inlining a function means writing the function directly into the caller's procedure, avoiding actual function calls.
1 2 3 4 5 6 | |
add() can be inlined into foo():
1 2 3 4 | |
always_inline,__force_inline
https://clang.llvm.org/docs/AttributeReference.html#always-inline-force-inline
Some compilers provide manual function inlining methods, adding __attribute__((always_inline)) before a function. Using this does not necessarily make it faster than a function call; the compiler trusts the programmer has good judgment at this point.
Tail Call Optimization
When a function call is at the tail position of a function body, such a call is called a tail call. For this special form of call, some special optimizations can be performed. Most architectures have Frame Pointer (a.k.a FP) and Stack Pointer (a.k.a SP), maintaining function frames. If the call is at the tail, we can discard the outer function's call record and directly replace it with the inner function.
Using Jump Instructions Instead of Function Calls
Function calls on most architectures require saving the current program counter $pc location, saving some caller-saved registers to return to the context. Tail calls do not need this process and are directly translated into jump instructions, because tail recursion never returns to the function's execution position.
A simple example: https://godbolt.org/z/e7b1safaW
1 2 3 | |
1 2 | |
Automatic Tail Recursion Rewriting
If a function's tail call is to itself, the function is tail recursive. Broadly speaking, indirect recursion (formed by two or more functions) where all are tail calls also falls into tail recursion. Tail recursion can be optimized by the compiler into non-recursive form, reducing extra stack overhead and function call cost. Many algorithm competition enthusiasts prefer writing non-recursive code; without optimizations, this greatly optimizes code constants. However, with optimizations enabled, recursive code generates binary quality almost identical to hand-written code.
1 2 3 4 | |
Note this function is not tail recursive, but can be rewritten as:
1 2 3 4 | |
The new code is tail recursive.
Modern compilers can automatically perform this process. If your code can be rewritten as tail recursive, the compiler can recognize this form and complete the rewrite.
Tail Recursion Elimination -Rpass=tailcallelim
Since the function is already tail recursive, the recursive statement can be directly removed. Through certain static analysis, the function can be transformed into non-recursive form. We won't delve into how compiler authors achieve this here. From practical experience, most OI code, if there are both recursive and non-recursive versions, can generally be automatically optimized into non-recursive version. Here are some concrete examples for readers:
GCD
1 | |
Fibonacci Sequence
1 2 3 4 5 6 | |
Factorial
1 2 3 4 5 | |
The assembly of these functions after optimization is identical to the non-recursive version; recursion is directly eliminated. For OI participants, you can safely write recursive versions of various algorithms with O2 enabled; there will be no difference from non-recursive versions. If the function you write cannot be rewritten into non-recursive form, the compiler can do nothing.
Strength Reduction
A common compilation optimization. The simplest example is x * 2 becoming x << 1, the latter being quite common in OI. Compilers automatically perform similar optimizations; with optimization switches on, x * 2 and x << 1 are completely equivalent. Strength reduction converts high-cost instructions to low-cost instructions.
Scalar Operator Transformations
Bitwise Operations Instead of Multiplication
1 2 3 | |
Note that signed and unsigned numbers have distinct differences in shifting and promotion. The sign bit receives special treatment during shifting, including arithmetic shift and logical shift. This is prominent when writing binary search/segment trees with many divide-by-two operations; signed integer division cannot be directly optimized to a single right shift.
1 2 3 4 5 6 7 8 9 | |
1 2 3 4 | |
Possible solutions:
- Use
unsigned l, r;, indices should be unsigned anyway. - Use shift in source code.
Multiplication Instead of Division
1 | |
This can be transformed into x = a * 0x55555556 >> 32. For details, see this Zhihu answer or the original paper.
Induction Variable Strength Reduction (IndVars)
Compiler automatically identifies induction variables in loops and converts related high-cost processes to low-cost.
1 2 3 4 5 | |
Here, directly using a = 3 * i is common in OI, but the compiler can automatically analyze that the equivalent transformation is a = a + 3, using lower-cost addition instead of multiplication. Analyzing loop variable evolution is called SCEV (Scalar Evolution).
SCEV can also optimize some loops:
1 2 3 4 5 6 7 | |
This function will be optimized to an \(O(1)\) summation formula. Refer to https://godbolt.org/z/ET8d89vvK. Currently, only LLVM-based compilers exhibit this behavior; GCC is more conservative.
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 | |
Auto-Vectorization
Single Instruction Multiple Data (SIMD) is a good method for single-core parallelism. Using such instructions utilizes CPU's SIMD registers, which are wider than general-purpose registers, e.g., holding 4 integers at once for computation. OI participants need not understand auto-vectorization details. Generally, Clang performs more aggressive auto-vectorization than GCC:
1 2 3 4 5 6 | |
__restrict type specifier (GNU, MSVC)
Two arbitrary pointers may have overlapping regions, requiring special checks for vector code usability. The following diagram shows an example of pointer overlap:
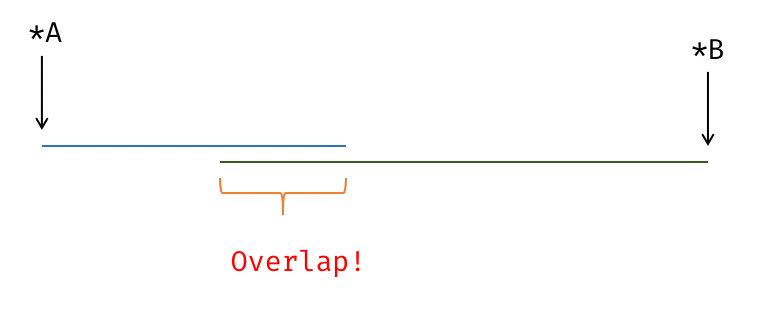
__restrict is a convention making the compiler assume two pointers never point to overlapping memory regions.
1 2 3 4 5 | |
__restrict is not part of the C++ standard but is available in major compilers. This keyword affects auto-vectorization code generation quality and can be used in extreme constant optimization scenarios.
Common Language Misuses Related to Compilation Optimizations
inline - Inlining
Function inlining is usually automatically done by the compiler with O2 enabled. inline in struct definitions is completely redundant. If the competition enables O2 optimization, there is no need to declare functions as inline. If O2 is not enabled, using inline won't make the compiler actually inline.
The inline keyword in modern C++ is treated as a linking and symbol export semantic behavior, not for function inlining.
register - False Register Hint
Modern compilers ignore your register keyword; your own register allocation ideas are generally not as smart as the compiler's register allocation algorithm. This keyword was deprecated in C++11 and removed in C++171.
https://en.cppreference.com/w/cpp/keyword/register
Undefined Behavior and Compilation Optimizations
Compilers can assume C++ programs have no undefined behavior (UB). Therefore, when compiling programs with UB, compilers may produce unexpected results. Meanwhile, compilers can also perform more aggressive and free optimizations under the assumption of no UB.
Common UB includes:
- Signed overflow;
- Using uninitialized variables;
- Out-of-bounds access;
- Null pointer dereference;
- Infinite loops without side effects.
Other UB and examples can be understood through extended reading.
Signed Overflow
1 | |
The compiler can assume the program has no signed overflow, so this function might be optimized to
1 | |
Examples: https://godbolt.org/z/WKv3W5hvM, https://godbolt.org/z/qqE9nxP1j.
This assumption can be disabled with the -fwrapv option. Examples: https://godbolt.org/z/5x3K5KGnr, https://godbolt.org/z/4r4a4EzMW.
Using Uninitialized Variables
1 2 3 4 5 6 | |
The compiler can assume the program has no use of uninitialized variables, so a must be initialized, thus this function might be optimized to
1 | |
Examples: https://godbolt.org/z/8WYMYYjdG, https://godbolt.org/z/qvGd1nvv9.
Out-of-Bounds Access
1 2 3 4 5 6 7 8 9 | |
The compiler can assume the program has no out-of-bounds access, so the function must return before out-of-bounds access occurs, thus this function might be optimized to
1 | |
Example: https://godbolt.org/z/xfePeYsE3.
Null Pointer Dereference
1 2 3 4 5 6 7 | |
The compiler can assume the program has no null pointer dereference, so !p is always false, thus this function might be optimized to
1 | |
Examples: https://godbolt.org/z/GY1jvsrb5, https://godbolt.org/z/4ronPsnxf.
Infinite Loops Without Side Effects
Verifying Fermat's Last Theorem
According to Fermat's Last Theorem, the equation \(a^3=b^3+c^3\) has no positive integer solutions. The following program attempts to enumerate integers in \([1,1000]\) to verify whether the equation holds. If it returns true, it means a set of integer solutions is found within \([1,1000]\), thus disproving Fermat's Last Theorem.
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 | |
The compiler can assume the program has no infinite loops without side effects, thus believing the for loop in fermat() will terminate at some point and return true. The program may eventually output:
1 | |
Examples: https://godbolt.org/z/d834MK7bz, https://godbolt.org/z/Eov9nsKqf.
Sanitizer
Sanity checkers. Check at runtime whether your program has undefined behavior, array out-of-bounds, null pointers, etc. In local debugging mode, enabling some sanitizers is recommended, greatly shortening debug time. These sanitizers are developed by Google and most can be used in GCC and Clang. Sanitizers are more mature in LLVM, so participants are recommended to use Clang compiler locally for debugging.
Address Sanitizer -fsanitize=address
https://clang.llvm.org/docs/AddressSanitizer.html
Both GCC and Clang support this sanitizer. Includes checks for:
- Out-of-bounds
- Use-after-free
- Use-after-return
- Double-free
- Memory leaks
- Use-after-scope
Applying this check slows your program by about 2x.
Undefined Behavior Sanitizer -fsanitize=undefined
https://clang.llvm.org/docs/UndefinedBehaviorSanitizer.html
Undefined Behavior Sanitizer (a.k.a UBSan) checks for undefined behavior in code. Both GCC and Clang support this sanitizer. Automatically checks your program for undefined behavior. UBSan checks include:
- Bitwise overflow, e.g., 32-bit integer left shift by 72 bits
- Signed integer overflow
- Floating-point to integer overflow
UBSan checks are optional; impact on program refers to provided web pages.
Miscellaneous
Compiler Explorer
Observe behaviors and assembly of various compilers here: https://godbolt.org
Extended Reading
- The LLVM Project Blog: What Every C Programmer Should Know About Undefined Behavior #⅓
- The LLVM Project Blog: What Every C Programmer Should Know About Undefined Behavior #⅔
- The LLVM Project Blog: What Every C Programmer Should Know About Undefined Behavior #3/3
References and Notes
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用