Introduction to Suffix Array
Some Conventions
For definitions related to strings, please refer to String Basics.
String indices start from \(1\).
The length of string \(s\) is \(n\).
"Suffix \(i\)" refers to the suffix starting at the \(i\)-th character. When stored, \(i\) represents the suffix \(s[i\dots n]\) of string \(s\).
What is a Suffix Array?
The Suffix Array mainly involves two arrays: \(sa\) and \(rk\).
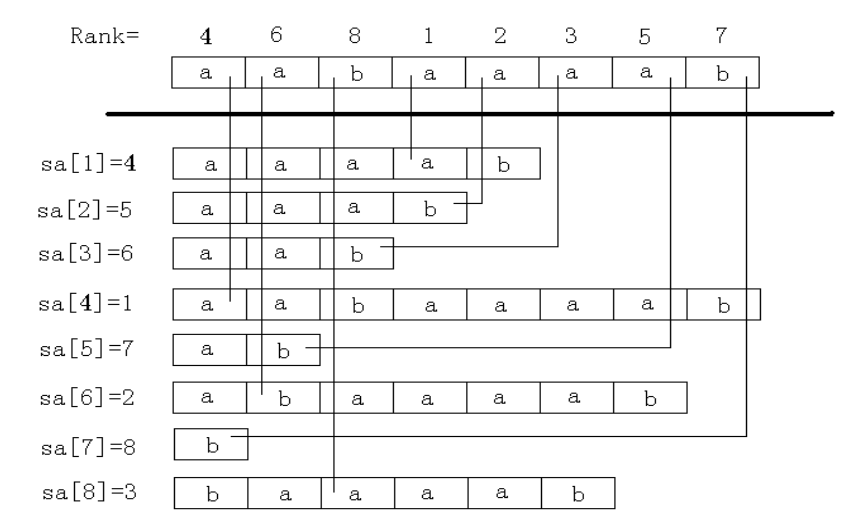
Here, \(sa[i]\) denotes the index of the \(i\)-th smallest suffix after sorting all suffixes. This is called the suffix array, also referred to as the index array \(sa\).
\(rk[i]\) denotes the rank of suffix \(i\), which is an important auxiliary array, also referred to as the rank array \(rk\).
These two arrays satisfy the property: \(sa[rk[i]]=rk[sa[i]]=i\).
Explanation
Example of a suffix array:
How to Compute the Suffix Array?
O(n^2logn) Approach
This approach is straightforward: sort the array containing all suffix strings using sort. Since sorting performs \(O(n\log n)\) string comparisons, and each string comparison requires \(O(n)\) character comparisons, the overall time complexity is \(O(n^2\log n)\).
O(nlog^2n) Approach
This approach uses the idea of doubling.
First, sort all substrings of length \(1\) of string \(s\), i.e., each character, to obtain the sorted index array \(sa_1\) and rank array \(rk_1\).
Doubling process:
-
Use the ranks of two substrings of length \(1\), i.e., \(rk_1[i]\) and \(rk_1[i+1]\), as the first and second keys for sorting. This allows sorting all substrings of length \(2\) of string \(s\): \(\{s[i\dots \min(i+1, n)]\ |\ i \in [1,\ n]\}\), obtaining \(sa_2\) and \(rk_2\).
-
Then, use the ranks of two substrings of length \(2\), i.e., \(rk_2[i]\) and \(rk_2[i+2]\), as the first and second keys for sorting. This allows sorting all substrings of length \(4\) of string \(s\): \(\{s[i\dots \min(i+3, n)]\ |\ i \in [1,\ n]\}\), obtaining \(sa_4\) and \(rk_4\).
-
Continue doubling: use the ranks of two substrings of length \(w/2\), i.e., \(rk_{w/2}[i]\) and \(rk_{w/2}[i+w/2]\), as the first and second keys for sorting. This allows sorting all substrings of length \(w\) of string \(s\): \(s[i\dots \min(i+w-1,\ n)]\), obtaining \(sa_w\) and \(rk_w\). Here, similar to lexicographic order, when \(i+w>n\), \(rk_w[i+w]\) is considered as negative infinity.
-
\(rk_w[i]\) is the rank of substring \(s[i\dots i + w - 1]\). When \(w \geqslant n\), the obtained index array \(sa_w\) is the suffix array we need.
Process
Illustration of doubling sort:
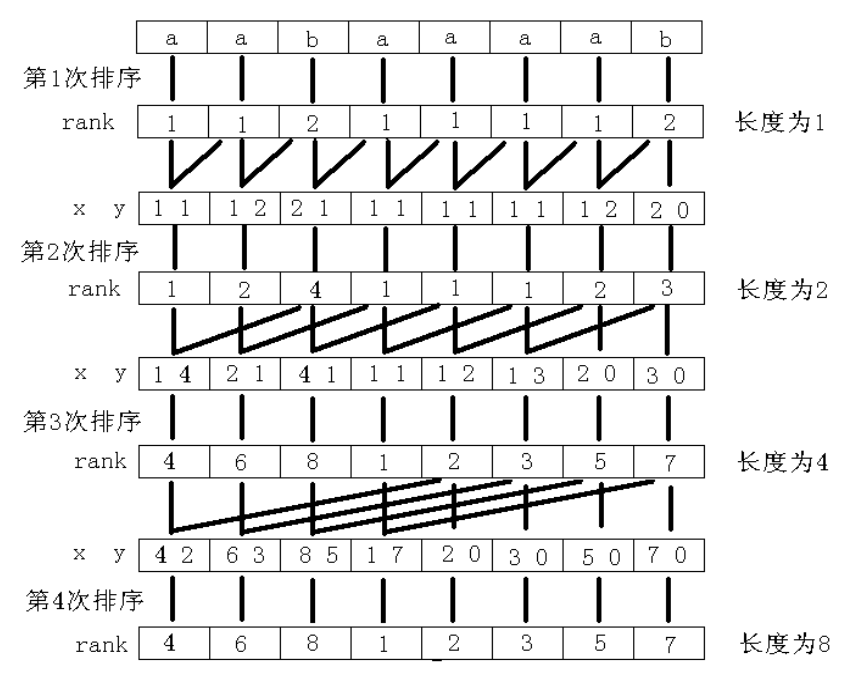
Clearly, the doubling process takes \(O(\log n)\) steps. Each step uses sort to sort substrings, which is \(O(n\log n)\), and each substring comparison requires \(2\) character comparisons.
Additionally, after each sort in the doubling step, there is an extra \(O(n)\) operation to update \(rk\), but this is negligible compared to \(O(n\log n)\).
Thus, the overall time complexity is \(O(n\log^2n)\).
Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 | |
O(nlogn) Approach
In the previous \(O(n\log^2n)\) approach, each sorting step is \(O(n\log n)\). If we can sort in \(O(n)\), we can compute the suffix array in \(O(n\log n)\).
Prerequisites: Counting Sort, Radix Sort.
Since the sorting keys during suffix array computation are ranks with a value range of \(O(n)\), and it is a two-key sort, we can use radix sort to optimize to \(O(n)\).
Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 | |
Some Constant Optimizations
If you submit the above code to LOJ #111: Suffix Sort:
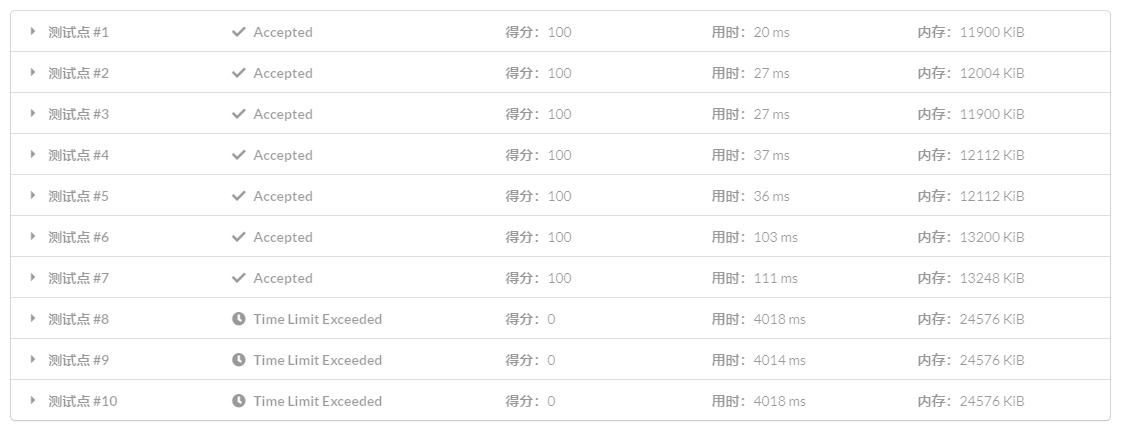
This is because the above code has high constant factors.
Second Key Does Not Require Counting Sort
Consider the essence of sorting by the second key: it simply places \(sa[i]\) that exceed the string range (i.e., \(sa[i] + w > n\)) at the beginning of the \(sa\) array, and then places the rest in their original order:
1 2 3 4 | |
Optimize the Value Range of Counting Sort
After each update of \(rk\), we compute a \(p\), which is the value range of \(rk\). We can set the value range to \(p\).
If All Ranks Are Distinct, Directly Generate Suffix Array
Consider the new \(rk\) array. If its value range is \([1,n]\), then each rank is distinct, and no further sorting is needed.
Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 | |
O(n) Approach
For general problems, the constant-optimized doubling suffix array is sufficient. Other parts often have \(O(n\log n)\) complexity, so doubling is not a bottleneck.
However, for special problems, tight time limits, or if you seek shorter runtime, you can learn \(O(n)\) suffix array construction methods.
SA-IS
Refer to Induced Sorting and SA-IS Algorithm. Its comment page is also valuable.
DC3
Refer to [2009] Suffix Array—A Powerful Tool for String Processing by Luo Suiqian.
Applications of Suffix Array
Finding the Smallest Cyclic Shift Position
Duplicate string \(S\) into \(SS\), transforming the problem into suffix sorting.
Example: 「JSOI2007」Character Encryption.
Finding Substrings in a String
The task is to find pattern string \(S\) in text string \(T\) online. "Online" means we know \(T\) in advance but only learn \(S\) upon query. We can construct \(T\)'s suffix array and then search for substring \(S\). If \(S\) appears in \(T\), it must be a prefix of some suffixes of \(T\). Since all suffixes are sorted, we can binary search \(S\) in the \(p\) array. Comparing \(S\) with a suffix takes \(O(|S|)\), so finding the substring takes \(O(|S|\log |T|)\). Note that if \(S\) appears multiple times, all occurrences are adjacent in the \(p\) array. Thus, the number of occurrences can be found via another binary search, and outputting each position is straightforward.
Minimizing Lexicographic Order by Taking Characters from Ends
Example: 「USACO07DEC」Best Cow Line.
Problem: Given a string, each step take a character from the front or back to form a string. Find the lexicographically smallest string among all possible strings.
Solution
The naive approach is to decide whether to take from the front or back in \(O(n)\) per step (by comparing the string formed by taking from the front with the reverse of the string formed by taking from the back). We only need to optimize this decision.
Since we need to compare between the set of original suffixes and the set of reversed suffixes, we can concatenate the reversed string to the original, separated by a character not in the alphabet (e.g., #, or an empty character in code). Then compute the suffix array to make the decision in \(O(1)\).
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 | |
Height Array
LCP (Longest Common Prefix)
The LCP of two strings \(S\) and \(T\) is the largest \(x\) (\(x\le \min(|S|, |T|)\)) such that \(S_i=T_i\ (\forall\ 1\le i\le x)\).
Below, \(lcp(i,j)\) denotes the longest common prefix (length) of suffix \(i\) and suffix \(j\).
Definition of Height Array
\(height[i]=lcp(sa[i],sa[i-1])\), i.e., the longest common prefix between the \(i\)-th suffix and its predecessor.
\(height[1]\) can be considered \(0\).
A Lemma Needed for O(n) Height Array Computation
\(height[rk[i]]\ge height[rk[i-1]]-1\)
Proof
When \(height[rk[i-1]]\le1\), the inequality holds trivially (right side \(\le 0\)).
When \(height[rk[i-1]]>1\):
By definition of \(height\), \(lcp(sa[rk[i-1]], sa[rk[i-1]-1]) = height[rk[i-1]] > 1\).
Since suffix \(i-1\) and suffix \(sa[rk[i-1]-1]\) have an LCP of length \(height[rk[i-1]]\),
let \(aA\) represent this LCP (where \(a\) is a character, \(A\) is a non-empty string of length \(height[rk[i-1]]-1\)).
Then suffix \(i-1\) can be written as \(aAD\), and suffix \(sa[rk[i-1]-1]\) as \(aAB\) (\(B < D\), \(B\) possibly empty, \(D\) non-empty).
Further, suffix \(i\) is \(AD\), and there exists suffix (\(sa[rk[i-1]-1]+1\)) \(AB\).
Since suffix \(sa[rk[i]-1]\) is ranked just before suffix \(sa[rk[i]]\) (i.e., suffix \(i\)), and \(AB < AD\),
we have \(AB \leqslant\) suffix \(sa[rk[i]-1] < AD\). Clearly, suffix \(i\) and suffix \(sa[rk[i]-1]\) share prefix \(A\).
Thus, \(lcp(i,sa[rk[i]-1])\) is at least \(height[rk[i-1]]-1\), i.e., \(height[rk[i]]\ge height[rk[i-1]]-1\).
Code for O(n) Height Array Computation
Using the lemma, compute directly:
1 2 3 4 5 6 | |
\(k\) does not exceed \(n\), decreases at most \(n\) times, so increases at most \(2n\) times. Total complexity is \(O(n)\).
Applications of Height Array
Longest Common Prefix of Two Substrings
\(lcp(sa[i],sa[j])=\min\{height[i+1..j]\}\)
Intuition: If \(height\) remains above a certain value, the prefixes remain unchanged; otherwise, since suffixes are sorted, they cannot change back.
For a rigorous proof, refer to [2004] Suffix Array by Xu Zhilei.
This theorem reduces finding LCP of two substrings to an RMQ problem.
Comparing Two Substrings of a String
Suppose we need to compare \(A=S[a..b]\) and \(B=S[c..d]\).
If \(lcp(a, c)\ge\min(|A|, |B|)\), then \(A<B\iff |A|<|B|\).
Otherwise, \(A<B\iff rk[a]< rk[c]\).
Number of Distinct Substrings
A substring is a prefix of a suffix. So we can enumerate each suffix, count total prefixes, and subtract duplicates.
"Total prefixes" is the number of substrings: \(n(n+1)/2\).
If we enumerate suffixes in sorted order, the new substrings added each time are the prefixes excluding the LCP with the previous suffix. These prefixes are new; otherwise, they would violate \(lcp(sa[i],sa[j])=\min\{height[i+1..j]\}\). The LCP part was counted when enumerating the previous suffix.
Thus, the answer is:
\(\frac{n(n+1)}{2}-\sum\limits_{i=2}^nheight[i]\)
Maximum Length of a Substring Appearing at Least k Times
Example: 「USACO06DEC」Milk Patterns.
Solution
Appearing at least \(k\) times means that after suffix sorting, at least \(k\) consecutive suffixes share this substring as a common prefix.
So, compute the minimum \(height\) among every consecutive \(k-1\) suffixes, and take the maximum of these minima as the answer.
Can be solved in \(O(n)\) with a monotonic queue, but other methods suffice.
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 | |
Checking if a String Appears at Least Twice Non-Overlapping
Binary search the length \(|s|\). Partition the \(h\) array into segments where consecutive LCP \(\ge |s|\). Use RMQ to find the maximum and minimum indices in each segment. If the distance satisfies the condition, then a length-\(|s|\) string appears non-overlapping at least twice.
Consecutive Identical Substrings
We can enumerate the length \(|s|\) of consecutive substrings, partition the string into blocks of size \(|s|\), and query LCP and LCS between adjacent block heads. See [2009] Suffix Array—A Powerful Tool for String Processing.
Example: 「NOI2016」Excellent Split.
Combined with Union-Find
Some problems require partitioning the suffix array into segments where consecutive LCP \(\ge\) some value, i.e., partitioning \(h\) into segments where consecutive minima \(\ge\) some value and counting answers per segment. For multiple queries, we can process offline. Observe that as the threshold decreases, the number of qualifying segments decreases, and new segments are formed by merging adjacent original segments. The \(h\) values in the newly merged parts become the decreased threshold. We can maintain a union-find set, merging adjacent segments each time, and maintain statistics.
Classic problem: 「NOI2015」Wine Tasting
Combined with Segment Tree
Some problems ask for the first few numbers satisfying certain conditions, and these numbers lie within an interval in the suffix array. We can use merge sort properties to combine information from two nodes and use a segment tree to maintain and query interval answers.
Combined with Monotonic Stack
Example: 「AHOI2013」Difference
Solution
The first two terms of the sum are easy: \(n(n-1)(n+1)/2\) (each suffix appears \(n-1\) times, total suffix length is \(n(n+1)/2\)). The key is the last term: pairwise LCP of suffixes.
We know \(lcp(i,j)=k\) is equivalent to \(\min\{height[i+1..j]\}=k\). So, we can consider \(lcp(i,j)\) as the contribution of \(\min\{x|i+1\le x\le j, height[x]=lcp(i,j)\}\) to the answer.
Consider each position's contribution to the answer: which suffixes' LCP does it affect? It affects one suffix from a contiguous block to its left with \(height\) greater than it, and one suffix from a contiguous block to its right with \(height\) not less than it. This can be computed with a monotonic stack.
The monotonic stack part is similar to Luogu P2659 Beautiful Sequence and the suspended line method.
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 | |
Similar problem: 「HAOI2016」Find Same Characters.
Exercises
- UVa 760 - DNA Sequencing
- UVa 1223 - Editor
- Codechef - Tandem
- Codechef - Substrings and Repetitions
- Codechef - Entangled Strings
- Codeforces - Martian Strings
- Codeforces - Little Elephant and Strings
- SPOJ - Ada and Terramorphing
- SPOJ - Ada and Substring
- UVa - 1227 - The longest constant gene
- SPOJ - Longest Common Substring
- UVa 11512 - GATTACA
- QOJ 11240 - Suffixes and Palindromes
- GYM - Por Costel and the Censorship Committee
- UVa 1254 - Top 10
- UVa 12191 - File Recover
- UVa 12206 - Stammering Aliens
- Codechef - Jarvis and LCP
- Luogu P8617 - Repetition Pattern
- UVa 11107 - Life Forms
- UVa 12974 - Exquisite Strings
- UVa 10526 - Intellectual Property
- UVa 12338 - Anti-Rhyme Pairs
- DevSkills Reconstructing Blue Print of Life
- UVa 12191 - File Recover
- SPOJ - Suffix Array
- Gym 102470J - Stammering Aliens
- SPOJ - LCS2
- Codeforces - Fake News (hard)
- SPOJ - Longest Commong Substring
- SPOJ - Lexicographical Substring Search
- Codeforces - Forbidden Indices
- Codeforces - Tricky and Clever Password
- Gym 101470B - Circle of digits
References
This page (parts introduced in 4070a9b) is mainly translated from the blog post Суффиксный массив and its English translation Suffix Array. The Russian version is under Public Domain + Leave a Link; the English version is under CC-BY-SA 4.0.
Papers:
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用