Binary Heap
Structure
Starting from the structure of a binary heap, it is a binary tree and a complete binary tree, where each node stores an element (or a weight).
Heap property: The weight of a parent node is not less than that of its children (max-heap). Similarly, we can define a min-heap. This article uses a max-heap as an example.
Due to the heap property, the root stores the maximum value (the getmax operation is thus resolved).
Process
Insert Operation
The insert operation refers to inserting an element into a binary heap while ensuring it remains a complete binary tree.
The simplest method is to insert at the rightmost leaf of the bottommost layer.
If the bottommost layer is full, add a new layer.
After insertion, the heap property might be violated?
Sift-up: If the weight of this node is greater than that of its parent, swap them. Repeat this process until the condition is no longer satisfied or the root is reached.
It can be proven that after insertion and sifting up, no other node will violate the heap property.
The time complexity of sifting up is \(O(\log n)\).

Delete Operation
The delete operation refers to removing the largest element in the heap, i.e., deleting the root node.
However, if deleted directly, it splits into two heaps, which is difficult to handle.
Thus, consider the inverse of the insert operation: try to move the root node to the last node and then delete it directly.
However, this is not easy in practice. The usual method is to directly swap the root node with the last node.
Then delete the root node (now at the last position), but the new root node might violate the heap property...
Sift-down: Among the children of this node, find the largest one and swap it with this node. Repeat this process until reaching the bottom layer.
It can be proven that after deletion and sifting down, no other node violates the heap property.
Time complexity is \(O(\log n)\).
Increase the Weight of a Node
Obviously, after directly modifying the weight, sift up once. Time complexity is \(O(\log n)\).
Implementation
We find that the operations introduced above mainly rely on two core operations: sift-up and sift-down.
Consider using a sequence \(h\) to represent the heap. The two children of \(h_i\) are \(h_{2i}\) and \(h_{2i+1}\), with \(1\) being the root node:
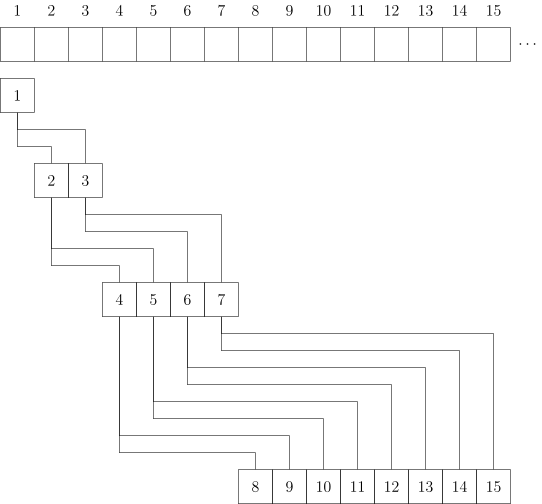
Reference code:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 | |
Building a Heap
Consider this problem: starting from an empty heap, insert \(n\) elements in any order.
Directly inserting one by one requires \(O(n \log n)\) time. Is there a better method?
Method 1: Using decreasekey (i.e., sift-up)
Start from the root and proceed in BFS order.
1 2 3 | |
Why this works: For a node at level \(k\), the complexity of sifting up is \(O(k)\) rather than \(O(\log n)\).
Total complexity: \(\log 1 + \log 2 + \cdots + \log n = \Theta(n \log n)\).
(Proven in "comparison-based sorting")
Method 2: Using sift-down
Now consider another approach: start from the leaves and sift down one by one.
1 2 3 | |
Another way to understand this: each time "merge" two already adjusted heaps, which demonstrates correctness.
Note the complexity of sifting down is \(O(\log n - k)\). Also note that leaf nodes do not need adjustment, so we can start adjusting from around position \(n/2\) in the sequence, which reduces some constant factors but does not affect the complexity.
Proof
The reason \(O(n)\) heap building is possible is because the heap property is weak; binary heaps are not unique.
If the conditions were as strong as in sorting, it would be more difficult.
Applications
Dual Priority Queue
SPOJ RMID2 - Running Median Again
Maintain a sequence supporting two operations:
- Insert an element into the sequence.
- Output and delete the current median of the sequence (if the sequence length is even, output the smaller median).
This problem can be further abstracted as: dynamically maintaining the \(k\)-th largest number in a sequence, where \(k\) may change.
For such problems, we can use the dual priority queue technique to solve it (avoiding the complexity of writing a weighted segment tree or BST).
A dual priority queue consists of a max-heap and a min-heap. The min-heap maintains the larger values, i.e., the top \(k\) largest values (including the \(k\)-th largest). The max-heap maintains the smaller values, i.e., all numbers smaller than the \(k\)-th largest.
This data structure supports the following operations:
- Maintain: When the size of the min-heap is less than \(k\), repeatedly take the top element of the max-heap and insert it into the min-heap until the min-heap size equals \(k\). When the min-heap size is greater than \(k\), repeatedly take the top element of the min-heap and insert it into the max-heap until the min-heap size equals \(k\).
- Insert element: If the inserted element is greater than or equal to the top element of the min-heap, insert it into the min-heap; otherwise, insert it into the max-heap. Then maintain the dual priority queue.
- Query the \(k\)-th largest element: The top element of the min-heap is the answer.
- Delete the \(k\)-th largest element: Delete the top element of the min-heap, then maintain the dual priority queue.
- Increase/decrease \(k\) by \(1\): Directly maintain the dual priority queue according to the new \(k\) value.
Clearly, the time complexity for querying the \(k\)-th largest element is \(O(1)\). Since after insertion, deletion, or adjusting \(k\), the size of the min-heap differs from the expected \(k\) by at most \(1\), each maintenance operation requires at most one adjustment of elements between the max-heap and min-heap. Therefore, the time complexity of these operations is \(O(\log n)\).
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 | |
Exercises
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用