Skip to content

Disjoint Set Union

Introduction

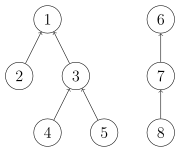
A Disjoint Set Union (DSU) is a data structure used to manage elements partitioned into disjoint sets. It is implemented as a forest, where each tree represents a set, and the nodes in the tree represent the elements in that set.

As the name suggests, DSU supports two operations:

  • Union (Unite): Merge the sets containing two elements (merge the corresponding trees).
  • Find (Query): Query which set an element belongs to (find the root node of the corresponding tree). This can be used to determine whether two elements belong to the same set.

With modifications, DSU can support deletion of single elements, moving elements, or maintaining edge weights on the tree. Using dynamic segment trees, it can also implement persistent DSU.

Warning

DSU cannot efficiently support the separation of sets.

Initialization

Initially, each element is in its own separate set, represented as a tree with only a root node. For convenience, we set the parent of the root node to itself.

Implementation
1
2
3
4
5
struct dsu {
  vector<size_t> pa;

  explicit dsu(size_t size) : pa(size) { iota(pa.begin(), pa.end(), 0); }
};
1
2
3
class Dsu:
    def __init__(self, size):
        self.pa = list(range(size))

Find Operation

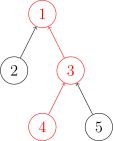
We need to move up the tree until we find the root node.
Implementation
1
size_t dsu::find(size_t x) { return pa[x] == x ? x : find(pa[x]); }
1
2
def find(self, x):
    return x if self.pa[x] == x else self.find(self.pa[x])

Path Compression

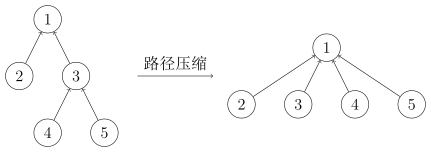
Every element visited during the find operation belongs to the same set. We can directly attach them to the root node to speed up future queries.
Implementation
1
size_t dsu::find(size_t x) { return pa[x] == x ? x : pa[x] = find(pa[x]); }
1
2
3
4
def find(self, x):
    if self.pa[x] != x:
        self.pa[x] = self.find(self.pa[x])
    return self.pa[x]

Union Operation

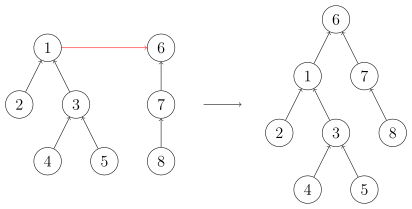
To merge two trees, we simply attach the root of one tree to the root of the other.
Implementation
1
void dsu::unite(size_t x, size_t y) { pa[find(x)] = find(y); }
1
2
def unite(self, x, y):
    self.pa[self.find(x)] = self.find(y)

Heuristic Merge (Union by Size/Rank)

When merging, choosing which root becomes the new root affects the complexity of future operations. We can attach the tree with fewer nodes or shallower depth to the other to avoid degeneration.

Detailed Complexity Discussion

Since we only need to support union and find operations, when merging two sets, attaching either set under the other yields a correct result. However, different attachment strategies lead to different time complexities. Specifically, if we attach a tree with fewer nodes and shallower depth under a larger tree, subsequent find operations will obviously be faster (and yield a better worst-case time complexity) compared to the alternative.

Of course, we don't always encounter sets that are strictly smaller in both size and depth. Since both size and depth are easy to maintain, we often choose one as the heuristic. Regardless of the choice, the time complexity is \(O(m\alpha(m,n))\). For a detailed proof, refer to the papers cited in the References.

In practice for competitive programming, even without heuristic merging, code often completes within time limits. In Tarjan's paper1, it is proven that using only path compression without heuristic merging has a worst-case time complexity of \(O(m \log n)\). In Yao's paper2, it is shown that using only path compression without heuristic merging has an average-case time complexity of \(O(m\alpha(m,n))\).

If only heuristic merging is used without path compression, the time complexity is \(O(m\log n)\). Since path compression in a single union may cause many modifications, it is sometimes unsuitable. For example, in persistent DSU or segment tree divide-and-conquer with DSU, DSU with only heuristic merging is generally used.

Reference implementation for union by size: (Note: the initialization method needs adjustment)

Implementation
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
struct dsu {
  vector<size_t> pa, size;

  explicit dsu(size_t size_) : pa(size_), size(size_, 1) {
    iota(pa.begin(), pa.end(), 0);
  }

  void unite(size_t x, size_t y) {
    x = find(x), y = find(y);
    if (x == y) return;
    if (size[x] < size[y]) swap(x, y);
    pa[y] = x;
    size[x] += size[y];
  }
};
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
class Dsu:
    def __init__(self, size):
        self.pa = list(range(size))
        self.size = [1] * size

    def unite(self, x, y):
        x, y = self.find(x), self.find(y)
        if x == y:
            return
        if self.size[x] < self.size[y]:
            x, y = y, x
        self.pa[y] = x
        self.size[x] += self.size[y]

Reference Implementation

A complete implementation of DSU with path compression and union by size is as follows:

Template Problem Luogu P3367【Template】Disjoint Set Union Reference Implementation
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
#include <algorithm>
#include <iostream>
#include <numeric>
#include <vector>

struct DSU {
  std::vector<size_t> pa, size;

  explicit DSU(size_t size_) : pa(size_), size(size_, 1) {
    std::iota(pa.begin(), pa.end(), 0);
  }

  size_t find(size_t x) { return pa[x] == x ? x : pa[x] = find(pa[x]); }

  void unite(size_t x, size_t y) {
    x = find(x), y = find(y);
    if (x == y) return;
    if (size[x] < size[y]) std::swap(x, y);
    pa[y] = x;
    size[x] += size[y];
  }
};

int main() {
  int n, m;
  std::cin >> n >> m;
  DSU dsu(n + 1);
  for (; m; --m) {
    int z, x, y;
    std::cin >> z >> x >> y;
    if (z == 1) {
      dsu.unite(x, y);
    } else {
      std::cout << (dsu.find(x) == dsu.find(y) ? 'Y' : 'N') << '\n';
    }
  }
  return 0;
}
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
class Dsu:
    def __init__(self, size):
        self.pa = list(range(size))
        self.size = [1] * size

    def find(self, x):
        if self.pa[x] != x:
            self.pa[x] = self.find(self.pa[x])
        return self.pa[x]

    def unite(self, x, y):
        x, y = self.find(x), self.find(y)
        if x == y:
            return
        if self.size[x] < self.size[y]:
            x, y = y, x
        self.pa[y] = x
        self.size[x] += self.size[y]


if __name__ == "__main__":
    n, m = map(int, input().split())
    dsu = Dsu(n + 1)
    for _ in range(m):
        z, x, y = map(int, input().split())
        if z == 1:
            dsu.unite(x, y)
        else:
            print("Y" if dsu.find(x) == dsu.find(y) else "N")

Complexity

With both path compression and heuristic merging, the average time per operation in DSU is only \(O(\alpha(n))\). Here, \(\alpha\) is the inverse of the Ackermann function, which grows extremely slowly. In other words, the average running time of a single DSU operation can be considered a very small constant. The proof of time complexity is on this page.

Inverse Ackermann Function

The Ackermann function \(A(m, n)\) is defined as:

\(A(m, n) = \begin{cases}n+1&\text{if }m=0\\A(m-1,1)&\text{if }m>0\text{ and }n=0\\A(m-1,A(m,n-1))&\text{otherwise}\end{cases}\)

The inverse Ackermann function \(\alpha(n)\) is defined as the inverse of the Ackermann function, i.e., the largest integer \(m\) such that \(A(m, m) \leqslant n\).

The space complexity of DSU is obviously \(O(n)\).

Extended Operations

Based on the ordinary DSU, a series of modifications can be made to support more operations or maintain more complex information.

DSU with Deletion

Ordinary DSU cannot support deletion because deleting a node inevitably deletes all nodes in the subtree rooted at it. To solve this, in DSU with deletion, we can ensure that all nodes storing actual data are always leaf nodes by creating virtual nodes. To do this, during initialization, a virtual node is created for each data node, and the parent of the data node is set to this virtual node. Since merging two sets always connects the two roots, only virtual nodes will ever have children. This ensures that deleting a node does not accidentally delete other nodes.

Note: after deleting a single node, a new virtual node must be created as its parent; otherwise, subsequent union and deletion operations cannot be performed correctly.

Template Problem SPOJ JMFILTER - Junk-Mail Filter Reference Implementation
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
#include <algorithm>
#include <iostream>
#include <numeric>
#include <vector>

struct DSU {
  size_t id;
  std::vector<size_t> pa, size;

  explicit DSU(size_t size_, size_t m)
      : id(size_ * 2), pa(size_ * 2 + m), size(size_ * 2 + m, 1) {
    // The first half of size is not actually used, just to make index calculation simpler
    std::iota(pa.begin(), pa.begin() + size_,
              size_);  // Make i point to virtual point i + size_
    std::iota(pa.begin() + size_, pa.end(), size_);  // All virtual points point to themselves
  }

  size_t find(size_t x) { return pa[x] == x ? x : pa[x] = find(pa[x]); }

  void unite(size_t x, size_t y) {
    x = find(x), y = find(y);
    if (x == y) return;
    if (size[x] < size[y]) std::swap(x, y);
    pa[y] = x;
    size[x] += size[y];
  }

  void erase(size_t x) {
    size_t y = find(x);
    --size[y];
    pa[x] = id++;
  }
};

int main() {
  int n, m, case_id = 0;
  while ((std::cin >> n >> m), n) {
    DSU dsu(n, m);
    for (; m; --m) {
      char ch;
      std::cin >> ch;
      if (ch == 'M') {
        int x, y;
        std::cin >> x >> y;
        dsu.unite(x, y);
      } else if (ch == 'S') {
        int x;
        std::cin >> x;
        dsu.erase(x);
      }
    }
    int res = 0;
    for (int i = n; i < dsu.id; ++i) {
      if (dsu.size[i] && i == dsu.find(i)) {
        ++res;
      }
    }
    std::cout << "Case #" << (++case_id) << ": " << res << '\n';
  }
  return 0;
}
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
# This code is for illustration only; it times out and cannot pass the original problem
class Dsu:
    def __init__(self, size, m):
        self.id = size * 2
        # Let i point to virtual point i + size_, all virtual points point to themselves
        self.pa = list(range(size, size * 2)) + list(range(size, size * 2 + m))
        # The first half of size is not actually used, just to make index calculation simpler
        self.size = [1] * (size * 2 + m)

    def find(self, x):
        if self.pa[x] != x:
            self.pa[x] = self.find(self.pa[x])
        return self.pa[x]

    def unite(self, x, y):
        x, y = self.find(x), self.find(y)
        if x == y:
            return
        if self.size[x] < self.size[y]:
            x, y = y, x
        self.pa[y] = x
        self.size[x] += self.size[y]

    def erase(self, x):
        y = self.find(x)
        self.size[y] -= 1
        self.pa[x] = self.id
        self.id += 1


if __name__ == "__main__":
    case_id = 0
    while True:
        n, m = map(int, input().split())
        if not n:
            break
        dsu = Dsu(n, m)
        for _ in range(m):
            op = input().split()
            if op[0] == "M":
                x = int(op[1])
                y = int(op[2])
                dsu.unite(x, y)
            elif op[0] == "S":
                x = int(op[1])
                dsu.erase(x)
        res = 0
        for i in range(n, dsu.id):
            if dsu.size[i] and i == dsu.find(i):
                res += 1
        case_id += 1
        print(f"Case #{case_id}: {res}")
        input()

A similar method can also be used to implement moving a single element between sets. Implementation details are explained in the example problem.

Weighted DSU

We can also define some weight on the edges of the DSU and define how this weight is combined during path compression, thereby solving more problems. For example, for the classic "NOI2001 Food Chain", we can maintain an addition group modulo \(3\) on the edge weights. For such problems maintaining edge weights modulo a small modulus, we can also solve them by splitting a single node in the DSU into multiple states. This technique in special cases is also called "kind DSU" or "extended domain DSU". Examples later will illustrate these approaches.

To maintain edge weights in DSU, the edge weight needs to be stored in the child node. Therefore, each node stores the weight of the edge between itself and its parent. Only when a node's parent changes does the edge weight need to be adjusted accordingly. In general, this may happen during path compression and when merging two nodes. For example, if the edge weight is the distance from the current node to its parent, then during path compression, each time the current node's parent is replaced by the root, the distance from the parent to the root must be added to the edge weight stored in the current node; similarly, when merging two sets, the weight of the newly connected edge between the two roots needs to be computed.

Template Problem Library Checker - Unionfind with Potential Reference Implementation
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
#include <algorithm>
#include <iostream>
#include <numeric>
#include <vector>

constexpr int M = 998244353;

struct DSU {
  std::vector<size_t> pa, size, dist;

  explicit DSU(size_t size_) : pa(size_), size(size_, 1), dist(size_) {
    std::iota(pa.begin(), pa.end(), 0);
  }

  size_t find(size_t x) {
    if (pa[x] == x) return x;
    size_t y = find(pa[x]);
    (dist[x] += dist[pa[x]]) %= M;
    return pa[x] = y;
  }

  bool unite(size_t x, size_t y, int d) {
    find(x), find(y);
    (d += M - dist[y]) %= M;
    (d += dist[x]) %= M;
    x = pa[x], y = pa[y];
    if (x == y) return d == 0;
    if (size[x] < size[y]) {
      std::swap(x, y);
      d = (M - d) % M;
    }
    pa[y] = x;
    size[x] += size[y];
    dist[y] = d;
    return true;
  }

  int check(size_t x, size_t y) {
    find(x), find(y);
    if (pa[x] != pa[y]) return -1;
    return (dist[y] - dist[x] + M) % M;
  }
};

int main() {
  int n, m;
  std::cin >> n >> m;
  DSU dsu(n);
  for (; m; --m) {
    int op;
    std::cin >> op;
    if (op) {
      int u, v;
      std::cin >> u >> v;
      std::cout << dsu.check(u, v) << '\n';
    } else {
      int u, v, x;
      std::cin >> u >> v >> x;
      std::cout << dsu.unite(u, v, x) << '\n';
    }
  }
  return 0;
}
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
M = 998244353


class DSU:
    def __init__(self, size: int):
        self.pa = list(range(size))
        self.size = [1] * size
        self.dist = [0] * size

    def find(self, x: int) -> int:
        if self.pa[x] == x:
            return x
        y = self.find(self.pa[x])
        self.dist[x] = (self.dist[x] + self.dist[self.pa[x]]) % M
        self.pa[x] = y
        return y

    def unite(self, x: int, y: int, d: int) -> bool:
        self.find(x)
        self.find(y)
        d = (d + M - self.dist[y]) % M
        d = (d + self.dist[x]) % M
        x, y = self.pa[x], self.pa[y]
        if x == y:
            return d == 0
        if self.size[x] < self.size[y]:
            x, y = y, x
            d = (M - d) % M
        self.pa[y] = x
        self.size[x] += self.size[y]
        self.dist[y] = d
        return True

    def check(self, x: int, y: int) -> int:
        self.find(x)
        self.find(y)
        if self.pa[x] != self.pa[y]:
            return -1
        return (self.dist[y] - self.dist[x] + M) % M


if __name__ == "__main__":
    n, m = map(int, input().split())
    dsu = DSU(n)
    for _ in range(m):
        op, *rest = map(int, input().split())
        if op:
            u, v = rest
            print(dsu.check(u, v))
        else:
            u, v, x = rest
            print(int(dsu.unite(u, v, x)))

Example Problems

In algorithm competitions, problems directly testing DSU often require designing special structures for the problem.

UVa11987 Almost Union-Find

Implement a data structure similar to DSU, supporting the following operations:

  1. Merge the sets containing two elements.
  2. Move a single element to the set containing another element.
  3. Query the size and sum of elements in the set containing a given element.
Solution

In this problem, operations 1 and 3 are easy to handle; the difficulty lies in operation 2. Suppose we want to move element \(x\) to the set containing element \(y\). In ordinary DSU, directly setting the parent of element \(x\) to the root of the set containing \(y\) does not work because it would move the entire subtree rooted at \(x\). To solve this, we need to ensure element \(x\) has no children. For this purpose, when initializing the DSU, create a virtual node \(\tilde x\) for each element \(x\), and set the parent of element \(x\) to the corresponding virtual node \(\tilde x\). This way, when merging two sets, since we always connect one root to another, and all roots are virtual nodes, only virtual nodes will have children, while all nodes storing actual elements have no children. Now, moving an element becomes much easier to implement.

Reference Implementation
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
#include <cassert>
#include <iostream>
#include <numeric>
#include <vector>

using namespace std;

struct dsu {
  vector<size_t> pa, size, sum;

  explicit dsu(size_t size_)
      : pa(size_ * 2), size(size_ * 2, 1), sum(size_ * 2) {
    // The first half of size and sum is not actually used, just to simplify index calculation
    iota(pa.begin(), pa.begin() + size_, size_);
    iota(pa.begin() + size_, pa.end(), size_);
    iota(sum.begin() + size_, sum.end(), 0);
  }

  void unite(size_t x, size_t y) {
    x = find(x), y = find(y);
    if (x == y) return;
    if (size[x] < size[y]) swap(x, y);
    pa[y] = x;
    size[x] += size[y];
    sum[x] += sum[y];
  }

  void move(size_t x, size_t y) {
    auto fx = find(x), fy = find(y);
    if (fx == fy) return;
    pa[x] = fy;
    --size[fx], ++size[fy];
    sum[fx] -= x, sum[fy] += x;
  }

  size_t find(size_t x) { return pa[x] == x ? x : pa[x] = find(pa[x]); }
};

int main() {
  size_t n, m, op, x, y;
  while (cin >> n >> m) {
    dsu dsu(n + 1);  // Element range is 1..n
    while (m--) {
      cin >> op;
      switch (op) {
        case 1:
          cin >> x >> y;
          dsu.unite(x, y);
          break;
        case 2:
          cin >> x >> y;
          dsu.move(x, y);
          break;
        case 3:
          cin >> x;
          x = dsu.find(x);
          cout << dsu.size[x] << ' ' << dsu.sum[x] << '\n';
          break;
        default:
          assert(false);  // not reachable
      }
    }
  }
  return 0;
}
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
class Dsu:
    def __init__(self, size):
        # The first half of size and sum is not actually used, just to make subscript calculation easier
        self.pa = list(range(size, size * 2)) * 2
        self.size = [1] * size * 2
        self.sum = list(range(size)) * 2

    def unite(self, x, y):
        x, y = self.find(x), self.find(y)
        if x == y:
            return
        if self.size[x] < self.size[y]:
            x, y = y, x
        self.pa[y] = x
        self.size[x] += self.size[y]
        self.sum[x] += self.sum[y]

    def move(self, x, y):
        fx, fy = self.find(x), self.find(y)
        if fx == fy:
            return
        self.pa[x] = fy
        self.size[fx] -= 1
        self.size[fy] += 1
        self.sum[fx] -= x
        self.sum[fy] += x

    def find(self, x):
        if self.pa[x] != x:
            self.pa[x] = self.find(self.pa[x])
        return self.pa[x]


if __name__ == "__main__":
    while True:
        try:
            n, m = map(int, input().split())
            dsu = Dsu(n + 1)  # Element range is 1..n
            for _ in range(m):
                op_x_y = list(map(int, input().split()))
                op = op_x_y[0]
                if op == 1:
                    dsu.unite(op_x_y[1], op_x_y[2])
                elif op == 2:
                    dsu.move(op_x_y[1], op_x_y[2])
                elif op == 3:
                    x = dsu.find(op_x_y[1])
                    print(dsu.size[x], dsu.sum[x])
        except EOFError:
            break
Luogu P2024「NOI2011」Food Chain

There are three types of animals \(A,B,C\) in the animal kingdom, and their food chain forms an interesting cycle. \(A\) eats \(B\), \(B\) eats \(C\), \(C\) eats \(A\).

There are \(N\) animals, numbered \(1 \sim N\). Each animal is one of \(A,B,C\), but we do not know which one.

Someone describes the food chain relationships among these \(N\) animals in two ways:

  • The first type of statement is 1 X Y, meaning \(X\) and \(Y\) are of the same type.
  • The second type of statement is 2 X Y, meaning \(X\) eats \(Y\).

This person says \(K\) statements one after another about the \(N\) animals using the above two forms. Some statements are true, some are false. A statement is false if it satisfies one of the following three conditions; otherwise, it is true.

  • The statement contradicts some previous true statements;
  • \(X\) or \(Y\) in the statement is greater than \(N\);
  • The statement says \(X\) eats \(X\).

Your task is to output the total number of false statements given \(N\) and the \(K\) statements.

Solution 1

Consider using weighted DSU to maintain food chain information. If \(x\) and \(y\) are of the same type, then \(x\equiv y\pmod 3\); if \(x\) eats \(y\), then \(x - y \equiv 1 \pmod 3\). This transforms the problem into the template problem mentioned earlier.

Specifically, for each statement, excluding those obviously false due to \(x>n\) or \(y>n\), we need to check if \(x\) and \(y\) are already connected: if connected, compute the distance modulo 3 between them and compare with the information claimed by the statement; otherwise, connect them according to the information provided. Apart from obvious cases, a statement is false if and only if the two mentioned nodes are already connected and the corresponding distance contradicts the claimed information.

Reference Implementation 1
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
#include <algorithm>
#include <iostream>
#include <numeric>
#include <vector>

constexpr int M = 3;

struct DSU {
  std::vector<size_t> pa, size, dist;

  explicit DSU(size_t size_) : pa(size_), size(size_, 1), dist(size_) {
    std::iota(pa.begin(), pa.end(), 0);
  }

  size_t find(size_t x) {
    if (pa[x] == x) return x;
    size_t y = find(pa[x]);
    (dist[x] += dist[pa[x]]) %= M;
    return pa[x] = y;
  }

  bool unite(size_t x, size_t y, int d) {
    find(x), find(y);
    (d += M - dist[y]) %= M;
    (d += dist[x]) %= M;
    x = pa[x], y = pa[y];
    if (x == y) return d == 0;
    if (size[x] < size[y]) {
      std::swap(x, y);
      d = (M - d) % M;
    }
    pa[y] = x;
    size[x] += size[y];
    dist[y] = d;
    return true;
  }
};

int main() {
  int n, m;
  std::cin >> n >> m;
  DSU dsu(n + 1);
  int res = 0;
  for (; m; --m) {
    int op, x, y;
    std::cin >> op >> x >> y;
    if (x > n || y > n)
      ++res;
    else
      res += !dsu.unite(x, y, op == 1 ? 0 : 1);
  }
  std::cout << res << std::endl;
  return 0;
}
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
M = 3


class DSU:
    def __init__(self, size: int):
        self.pa = list(range(size))
        self.size = [1] * size
        self.dist = [0] * size

    def find(self, x: int) -> int:
        if self.pa[x] == x:
            return x
        y = self.find(self.pa[x])
        self.dist[x] = (self.dist[x] + self.dist[self.pa[x]]) % M
        self.pa[x] = y
        return y

    def unite(self, x: int, y: int, d: int) -> bool:
        self.find(x)
        self.find(y)
        d = (d + M - self.dist[y]) % M
        d = (d + self.dist[x]) % M
        x, y = self.pa[x], self.pa[y]
        if x == y:
            return d == 0
        if self.size[x] < self.size[y]:
            x, y = y, x
            d = (M - d) % M
        self.pa[y] = x
        self.size[x] += self.size[y]
        self.dist[y] = d
        return True


if __name__ == "__main__":
    n, m = map(int, input().split())
    dsu = DSU(n + 1)
    res = 0
    for _ in range(m):
        op, x, y = map(int, input().split())
        if x > n or y > n:
            res += 1
        else:
            res += not dsu.unite(x, y, 0 if op == 1 else 1)
    print(res)
Solution 2

Split each creature \(x\) into three states. In implementation, we can directly treat different states as different elements:

  • States in the same set as \(x\) are of the same species as \(x\);
  • States in the same set as \(x+n\) can be eaten by \(x\);
  • States in the same set as \(x+2n\) can eat \(x\).

Then, for a statement:

  • 1 x y is false if and only if:

    1. \(x>N\) or \(y>N\);
    2. \(y\) is in the same set as either \(x+n\) or \(x+2n\).
  • 2 x y is false if and only if:

    1. \(x>N\) or \(y>N\);
    2. \(y\) is in the same set as either \(x\) or \(x+2n\).
  • If true, merge the corresponding states.

Reference Implementation 2
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
#include <algorithm>
#include <iostream>
#include <numeric>
#include <vector>

struct DSU {
  std::vector<size_t> pa, size;

  explicit DSU(size_t size_) : pa(size_), size(size_, 1) {
    std::iota(pa.begin(), pa.end(), 0);
  }

  size_t find(size_t x) { return pa[x] == x ? x : pa[x] = find(pa[x]); }

  void unite(size_t x, size_t y) {
    x = find(x), y = find(y);
    if (x == y) return;
    if (size[x] < size[y]) std::swap(x, y);
    pa[y] = x;
    size[x] += size[y];
  }
};

int main() {
  int n, m;
  std::cin >> n >> m;
  DSU dsu(n * 3 + 1);
  int res = 0;
  for (; m; --m) {
    int op, x, y;
    std::cin >> op >> x >> y;
    if (x > n || y > n)
      ++res;
    else if (op == 1) {
      if (dsu.find(x) == dsu.find(y + n) ||
          dsu.find(x) == dsu.find(y + (n << 1))) {
        ++res;
      } else {
        dsu.unite(x, y);
        dsu.unite(x + n, y + n);
        dsu.unite(x + n * 2, y + n * 2);
      }
    } else {
      if (dsu.find(x) == dsu.find(y) || dsu.find(x) == dsu.find(y + n)) {
        ++res;
      } else {
        dsu.unite(x, y + n * 2);
        dsu.unite(x + n, y);
        dsu.unite(x + n * 2, y + n);
      }
    }
  }
  std::cout << res << std::endl;
  return 0;
}
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
class Dsu:
    def __init__(self, size):
        self.pa = list(range(size))
        self.size = [1] * size

    def find(self, x):
        if self.pa[x] != x:
            self.pa[x] = self.find(self.pa[x])
        return self.pa[x]

    def unite(self, x, y):
        x, y = self.find(x), self.find(y)
        if x == y:
            return
        if self.size[x] < self.size[y]:
            x, y = y, x
        self.pa[y] = x
        self.size[x] += self.size[y]


if __name__ == "__main__":
    n, m = map(int, input().split())
    dsu = Dsu(n * 3 + 1)
    res = 0
    for _ in range(m):
        op, x, y = map(int, input().split())
        if x > n or y > n:
            res += 1
        elif op == 1:
            if dsu.find(x) == dsu.find(y + n) or dsu.find(x) == dsu.find(y + (n << 1)):
                res += 1
            else:
                dsu.unite(x, y)
                dsu.unite(x + n, y + n)
                dsu.unite(x + n * 2, y + n * 2)
        else:
            if dsu.find(x) == dsu.find(y) or dsu.find(x) == dsu.find(y + n):
                res += 1
            else:
                dsu.unite(x, y + n * 2)
                dsu.unite(x + n, y)
                dsu.unite(x + n * 2, y + n)
    print(res)
ABC396E Min of Restricted Sum

Given integers \(N, M\) and integer sequences of length \(M\): \(X=(X_1,X_2,\ldots,X_M)\), \(Y=(Y_1,Y_2,\ldots,Y_M)\), \(Z=(Z_1,Z_2,\ldots,Z_M)\). It is guaranteed that all elements of \(X\) and \(Y\) are between \(1\) and \(N\).

Define a non-negative integer sequence \(A=(A_1,A_2,\ldots,A_N)\) of length \(N\) as a good integer sequence if and only if it satisfies the following condition:

  • For all integers \(i\) satisfying \(1 \leq i \leq M\), \(A_{X_i} \oplus A_{Y_i} = Z_i\), where \(\oplus\) denotes the XOR operation.

Determine whether such a good integer sequence exists. If it exists, find the good integer sequence that minimizes the sum of elements \(\displaystyle \sum_{i=1}^N A_i\), and output that sequence.

Solution

XOR is essentially a "same" or "different" relationship on individual binary bits. Therefore, by splitting all bits of \(A_i\), the XOR relationship can be maintained using weighted DSU (or kind DSU). Elements in the same connected component correspond to the same bit position of different numbers in \(A\). When computing the answer, elements in the same connected component are typically divided into two groups with opposite values. To minimize the total sum, assign the larger group to \(0\) and the smaller group to \(1\).

Reference Implementation
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
#include <algorithm>
#include <iostream>
#include <numeric>
#include <vector>

constexpr int M = 2;

struct DSU {
  std::vector<size_t> pa, size, dist;

  explicit DSU(size_t size_) : pa(size_), size(size_, 1), dist(size_) {
    std::iota(pa.begin(), pa.end(), 0);
  }

  size_t find(size_t x) {
    if (pa[x] == x) return x;
    size_t y = find(pa[x]);
    (dist[x] += dist[pa[x]]) %= M;
    return pa[x] = y;
  }

  bool unite(size_t x, size_t y, int d) {
    find(x), find(y);
    (d += M - dist[y]) %= M;
    (d += dist[x]) %= M;
    x = pa[x], y = pa[y];
    if (x == y) return d == 0;
    if (size[x] < size[y]) {
      std::swap(x, y);
      d = (M - d) % M;
    }
    pa[y] = x;
    size[x] += size[y];
    dist[y] = d;
    return true;
  }
};

int main() {
  int n, m;
  std::cin >> n >> m;
  DSU dsu((n + 1) << 5);
  for (; m; --m) {
    int x, y, z;
    std::cin >> x >> y >> z;
    for (int i = 0; i < 31; ++i) {
      if (!dsu.unite((x << 5) | i, (y << 5) | i, (z >> i) & 1)) {
        std::cout << -1 << std::endl;
        return 0;
      }
    }
  }
  std::vector<int> a(n + 1), cnt((n + 1) << 5);
  for (int i = 1; i < ((n + 1) << 5); ++i) {
    dsu.find(i);
    if (dsu.dist[i]) ++cnt[dsu.pa[i]];
  }
  for (int i = 1; i <= n; ++i) {
    for (int j = 0; j < 31; ++j) {
      int x = (i << 5) | j, y = dsu.pa[x];
      if ((cnt[y] > dsu.size[y] / 2) ^ dsu.dist[x]) {
        a[i] |= 1 << j;
      }
    }
  }
  for (int i = 1; i <= n; ++i) std::cout << a[i] << ' ';
  std::cout << std::endl;
  return 0;
}
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
M = 2


class DSU:
    def __init__(self, size: int):
        self.pa = list(range(size))
        self.size = [1] * size
        self.dist = [0] * size

    def find(self, x: int) -> int:
        if self.pa[x] == x:
            return x
        y = self.find(self.pa[x])
        self.dist[x] = (self.dist[x] + self.dist[self.pa[x]]) % M
        self.pa[x] = y
        return y

    def unite(self, x: int, y: int, d: int) -> bool:
        self.find(x)
        self.find(y)
        d = (d + M - self.dist[y]) % M
        d = (d + self.dist[x]) % M
        x, y = self.pa[x], self.pa[y]
        if x == y:
            return d == 0
        if self.size[x] < self.size[y]:
            x, y = y, x
            d = (M - d) % M
        self.pa[y] = x
        self.size[x] += self.size[y]
        self.dist[y] = d
        return True


if __name__ == "__main__":
    n, m = map(int, input().split())
    dsu = DSU((n + 1) << 5)
    for _ in range(m):
        x, y, z = map(int, input().split())
        for i in range(31):
            if not dsu.unite((x << 5) | i, (y << 5) | i, (z >> i) & 1):
                print(-1)
                exit()

    a = [0] * (n + 1)
    cnt = [0] * ((n + 1) << 5)

    for i in range(1, (n + 1) << 5):
        dsu.find(i)
        if dsu.dist[i]:
            cnt[dsu.pa[i]] += 1

    for i in range(1, n + 1):
        for j in range(31):
            x = (i << 5) | j
            y = dsu.pa[x]
            if (cnt[y] > dsu.size[y] // 2) ^ dsu.dist[x]:
                a[i] |= 1 << j

    print(" ".join(map(str, a[1:])))

Exercises

Other Applications

The Kruskal algorithm in Minimum Spanning Tree and the Tarjan algorithm in Lowest Common Ancestor are algorithms based on DSU.

Related topics can be found in DSU Applications.

References and Further Reading

  1. Zhihu Answer: Is there really a binary path compression optimization in DSU?
  2. Gabow, H. N., & Tarjan, R. E. (1985). A Linear-Time Algorithm for a Special Case of Disjoint Set Union. JOURNAL OF COMPUTER AND SYSTEM SCIENCES, 30, 209-221.PDF
  3. CSDN: Extended Domain DSU & Weighted DSU

  1. Tarjan, R. E., & Van Leeuwen, J. (1984). Worst-case analysis of set union algorithms. Journal of the ACM (JACM), 31(2), 245-281.ResearchGate PDF ↩

  2. Yao, A. C. (1985). On the expected performance of path compression algorithms.SIAM Journal on Computing, 14(1), 129-133. ↩