Prefix Sum & Difference
Introduction
Prefix sums and differences are commonly used techniques in competitive programming. The former is used for quickly computing interval sums, while the latter is used for efficiently performing interval modifications.
Convention
For convenience, this article assumes arrays \(\{a_i\}\) are 1-indexed by default, with the supplementary definition \(a_0 = 0\).
Prefix Sum
A prefix sum can be simply understood as "the sum of the first \(n\) terms of a sequence" and is an important preprocessing technique.
One-Dimensional Prefix Sum
For a sequence \(\{a_i\}\) of length \(n\), if you need to repeatedly query the sum of numbers in the interval \([l,r]\), you can consider using prefix sums. The prefix sum of the sequence is
It can be computed term by term using the recurrence relation
To query the sum of the sequence within the interval \([l,r]\), simply compute the difference
Thus, with \(O(n)\) time preprocessing, the complexity of a single interval sum query can be reduced to \(O(1)\).
Reference Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 | |
The C++ standard library implements the prefix sum function std::partial_sum, defined in the header <numeric>. Starting from C++17, the standard library also provides a functionally identical prefix sum function std::inclusive_scan, also defined in the header <numeric>.
Two-Dimensional/Multi-Dimensional Prefix Sum
Extending one-dimensional prefix sums to multi-dimensional cases yields multi-dimensional prefix sums. There are two common methods for computing multi-dimensional prefix sums.
Based on the Inclusion-Exclusion Principle
This method is often used for two-dimensional prefix sums. Given a two-dimensional array \(A\) of size \(m\times n\), we want to compute its prefix sum \(S\). Then \(S\) is also a two-dimensional array of size \(m\times n\), and
Analogous to the one-dimensional case, \(S_{i,j}\) should be computable based on \(S_{i-1,j}\) or \(S_{i,j-1}\) to avoid repeatedly summing the preceding terms. However, if we directly add \(S_{i-1,j}\) and \(S_{i,j-1}\) and then add \(A_{i,j}\), the overlapping prefix sum \(S_{i-1,j-1}\) would be counted twice, so we need to subtract it. This is the inclusion-exclusion principle. Thus, we obtain the following recurrence relation:
In implementation, simply iterate over \((i,j)\) to compute the sums.
Example
Consider a concrete example.
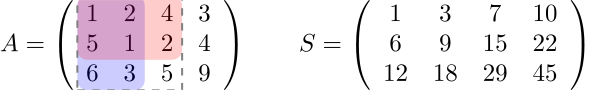
Here, \(S\) is the prefix sum of matrix \(A\). By definition, \(S_{3,3}\) is the sum of the submatrix within the dashed box in the left figure. Moreover, \(S_{3,2}\) is the sum of the blue submatrix, \(S_{2,3}\) is the sum of the red submatrix, and their overlapping sum is \(S_{2,2}\). It can be seen that directly adding \(S_{3,2}\) and \(S_{2,3}\) would double-count \(S_{2,2}\), so we should have
Similarly, after preprocessing the two-dimensional prefix sum, to query the sum of the submatrix with top-left corner \((i_1,j_1)\) and bottom-right corner \((i_2,j_2)\), compute
This can be done in \(O(1)\) time.
In the two-dimensional case, the time complexity of the above algorithm can be simply considered as \(O(mn)\), i.e., linear in the size of the given array. However, as the dimension \(k\) increases, the number of terms involved in the inclusion-exclusion principle grows exponentially, making the time complexity \(O(2^kN)\), where \(k\) is the array dimension and \(N\) is the size of the given array. Therefore, this algorithm is no longer suitable.
Luogu P1387 Largest Square
In an \(n\times m\) matrix containing only \(0\) and \(1\), find the largest square that does not contain \(0\), and output its side length.
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 | |
Dimension-by-Dimension Prefix Sum
For the general case, given a \(k\)-dimensional array \(A\) of size \(N\), we also want to compute its prefix sum \(S\). Here,
From the above equation, we can see that a \(k\)-dimensional prefix sum is equivalent to performing summation \(k\) times. Therefore, an obvious algorithm is to consider one dimension at a time, fix all other dimensions, and compute several one-dimensional prefix sums. After performing this for all \(k\) dimensions, we obtain the \(k\)-dimensional prefix sum.
Reference Implementation for 3D Prefix Sum
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 | |
Since each dimension is processed by traversing the entire array once, the complexity of this algorithm is \(O(kN)\), which is generally acceptable.
Special Case: Subset Sum DP
High-dimensional cases often appear in a class of problems called sum over subsets (SOS). This is a special case of high-dimensional prefix sums.
The problem is described as follows. Consider a function \(f\) defined on all subsets of a set of size \(n\). We want to compute its subset sum function \(g\), which satisfies
That is, \(g(S)\) equals the sum of the function values \(f(T)\) over all its subsets \(T\subseteq S\).
First, the subset sum problem can be written as a high-dimensional prefix sum. Note that subsets \(S\) can be represented as binary strings \(s\) of length \(n\) using state compression. Treating each bit of the string as a dimension of the array index, \(f\) is essentially an \(n\)-dimensional array, with each dimension's index in \(\{0,1\}\). Meanwhile, the subset inclusion relation is equivalent to the index magnitude relation, i.e.,
Thus, summing over subsets is computing the prefix sum of this \(n\)-dimensional array.
Now, we can directly use the dimension-by-dimension prefix sum method described earlier to compute the subset sum. The time complexity is \(O(n2^n)\).
Reference Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 | |
The inverse operation of subset sum requires the inclusion-exclusion principle. The subset sum problem is also a necessary step for the fast Möbius transform.
Tree Prefix Sum
One-dimensional prefix sums can also be generalized to rooted trees (with root \(1\)). By preprocessing prefix sums, we can quickly compute the sum of weights along a path on the tree.
Vertex Weights
First, consider the case where weights are stored at vertices. Let vertex \(x\) have weight \(a_x\). We can compute the sum of weights along the path from the root to vertex \(x\) using the recurrence relation
where \(\operatorname{fa}(x)\) denotes the parent of \(x\). After preprocessing the prefix sums, the sum of vertex weights along the path connecting vertices \(x\) and \(y\) can be computed via
Here, \(\operatorname{lca}(x, y)\) denotes the lowest common ancestor of vertices \(x\) and \(y\).
Edge Weights
The case where weights are stored on edges can almost be transformed into the vertex weight case. For all non-root vertices \(x\neq 1\), let \(\operatorname{edge}(x)\) denote the edge connecting vertex \(x\) and its parent \(\operatorname{fa}(x)\). Then, we can assume edge weights are stored at the vertex farther from the root. That is, vertex \(x\) stores the weight of edge \(\operatorname{edge}(x)\). The root vertex stores a weight of \(0\). Then, using the recurrence relation discussed in the previous subsection, we can similarly precompute the sum of weights of all edges along the path from the root to vertex \(x\), denoted \(S_x\).
In this case, the sum of vertex weights (which now represent edge weights) along the path connecting vertices \(x\) and \(y\) can be queried via
Note the difference from the vertex weight case: the queried sum does not include the weight at \(\operatorname{lca}(x, y)\), because the edge weight it stores is not on the path in question.
Subtree Sum
Unlike arrays, due to the asymmetry of trees (root vs. leaves), computing "prefix sums" from bottom-up (leaves to root) and top-down (root to leaves) yields different results. Typically, "tree prefix sum" refers to the top-down computed prefix sum. For convenience, this article refers to the bottom-up computed "prefix sum" as subtree sum.
The sum of vertex weights in the subtree rooted at vertex \(x\), i.e., the corresponding subtree sum, is
where \(\operatorname{desc}(x)\) denotes the set of all descendants of \(x\) (including itself).
Unlike tree prefix sums, subtree sums cannot be used for \(O(1)\) path sum queries, but they are useful for understanding tree differences discussed below.
Difference
Difference is a strategy opposite to prefix sums, serving as the inverse operation of prefix sums. In competitive programming, a more common scenario than computing the difference of a given sequence is performing multiple interval modifications by maintaining difference sequence information. After all modifications are done, the original sequence can be recovered via prefix sums to enable queries on the original sequence. Note that modifications must be performed before queries.
If mixed operations of multiple modifications and queries need to be supported, a Fenwick Tree is required, but the underlying ideas are shared.
One-Dimensional Difference
For a sequence \(\{a_i\}\), its difference sequence \(\{D_i\}\) is defined as
The C++ standard library implements the difference function std::adjacent_difference, defined in the header <numeric>.
The relationship between prefix sums and differences is as follows:
Properties
Let \(\{D_i\}\) be the difference sequence of \(\{a_i\}\). Then,
-
The sequence \(\{a_i\}\) is the prefix sum of \(\{D_i\}\), i.e.,
\[ a_i = \sum_{j=1}^i D_i. \] -
The prefix sum of \(\{a_i\}\) is
\[ S_i = \sum_{j=1}^i\sum_{k=1}^jD_k = \sum_{j=1}^i(i-j+1)D_j. \]
Difference information is often used to maintain multiple operations that add a number to an interval of a sequence, followed by one or more queries for the value at a specific position.
Suppose we want to add \(v\) to each number in the interval \([l,r]\) of sequence \(\{a_i\}\). We can perform the following operations on its difference sequence \(\{D_i\}\):
After all modifications, the updated \(\{a_i\}\) can be recovered via a prefix sum operation. A single modification is \(O(1)\). For queries, an \(O(n)\) prefix sum operation is needed first, after which each query is \(O(1)\).
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 | |
Two-Dimensional/Multi-Dimensional Difference
Difference can also be generalized to multi-dimensional cases. Treating multi-dimensional difference as the inverse of multi-dimensional prefix sums, computing the multi-dimensional difference array is equivalent to recovering the original array from its multi-dimensional prefix sum. As discussed earlier, the inclusion-exclusion principle can be used. For example, the definition of two-dimensional difference is
However, if we need to compute the entire difference array, a simpler and more efficient approach is dimension-by-dimension difference: enumerate all dimensions and compute the array's difference along each dimension.
Two-dimensional difference information is often used to maintain multiple rectangle additions on a 2D array. For example, to add \(v\) to every number in the matrix with top-left corner \((x_1,y_1)\) and bottom-right corner \((x_2,y_2)\), we can perform the following operations on its difference array \(\{D_{i,j}\}\):
After all modifications, performing a single two-dimensional prefix sum allows quick queries of the updated array's values.
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 | |
Of course, similar ideas hold for dimensions \(k>2\), but the time complexity for a single modification becomes \(O(2^k)\), which becomes impractical as \(k\) increases.
Tree Difference
Difference can be generalized to rooted trees for implementing interval addition operations along a path on the tree. Depending on whether the maintained information is stored at vertices or edges, tree difference can be divided into vertex difference and edge difference, with slight implementation differences. Additionally, compared to tree prefix sum operations, it is more common to compute subtree sums after all modifications and then query. This section discusses this scenario.
Vertex Difference
If we want to add \(v\) to all vertex weights on the path between vertices \(x\) and \(y\), we can perform the following operations on its difference sequence \(\{D_x\}\):
After all modifications, computing a subtree sum once yields the updated vertex weights.
Example
When performing an interval addition on vertex weights along the path between vertices \(S\) and \(T\), the first two operations in the above formula perform a one-dimensional difference operation on the path within the blue box, and the last two perform a one-dimensional difference operation on the path within the red box:
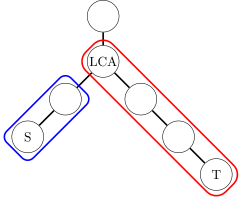
Summing from bottom-up is equivalent to computing prefix sums from bottom to top for these two intervals. Comparing with the one-dimensional difference operation described earlier confirms the correctness of the vertex difference operation.
Edge Difference
If we want to add \(v\) to all edge weights on the path between vertices \(x\) and \(y\), we can perform the following operations on its difference sequence \(\{D_x\}\):
After all modifications, computing a subtree sum once yields the updated vertex weights (which represent edge weights).
Example
As shown in the figure, edge difference operations can be used to solve interval addition problems on edge weights along the red path.
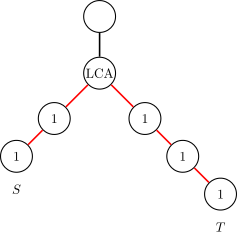
Since directly performing difference on edges is difficult, the values that should be added to the red edges are shifted down to adjacent vertices, making operations more convenient. Comparing with the vertex difference formula helps understand the edge difference formula.
Example Problems
Luogu 3128 Max Flow
FJ installed \(N-1\) pipes between the \(N(2 \le N \le 50,000)\) stalls in his barn, numbered from \(1\) to \(N\). All stalls are connected by pipes.
FJ has \(K(1 \le K \le 100,000)\) milk transport routes, with the \(i\)-th route transporting from stall \(s_i\) to stall \(t_i\). Each transport route adds one unit of transport pressure to the two endpoint stalls and all intermediate stalls along the path. You need to compute the pressure of the stall with the highest pressure.
Solution Idea
We need to count how many times each point is passed. Using tree difference, we can add one to all points on each path quickly. Here, the doubling method is used to compute LCA. Finally, perform a DFS traversal of the entire tree, and sum the difference array during backtracking to obtain the answer.
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 | |
Exercises
Prefix Sum:
- Luogu B3612【Shenjin 1. Example 1】Interval Sum
- Luogu U69096 Inverse of Prefix Sum
- AtCoder joi2007ho_a Maximum Sum
- 「USACO16JAN」Subsequences Summing to Sevens
- 「USACO05JAN」Moo Volume S
Two-Dimensional/Multi-Dimensional Prefix Sum:
- HDU 6514 Monitor
- Luogu P1387 Largest Square
- 「HNOI2003」Laser Bomb
- CF 165E Compatible Numbers
- CF 383E Vowels
- ARC 100C Or Plus Max
Tree Prefix Sum:
Difference:
- Fenwick Tree 3: Interval Modify, Interval Query
- 「Poetize6」IncDec Sequence
- Luogu P4231 Three Steps Must Kill
Two-Dimensional/Multi-Dimensional Difference:
Tree Difference:
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用