Finger Tree
Note
This chapter is optional reading. Before proceeding, ensure you have some understanding of Functional Programming.
Introduction
Finger Tree is a purely functional data structure proposed by Ralf Hinze and Ross Paterson.
Why Finger Trees Are Needed
In functional programming, lists are a very common data type. For sequence-based operations, including adding and removing elements at both ends (deque operations), inserting, concatenating, and deleting at arbitrary nodes, finding elements that meet certain requirements, and splitting sequences into subsequences, almost all functional languages provide support. However, for more efficient operations, these languages often struggle. Even if corresponding implementations exist, they are usually very complex and difficult to use in practice.
Finger trees provide a purely functional sequence data structure that can perform operations such as accessing, adding to the front and back of a sequence in amortized constant time, and concatenation and random access in logarithmic time. Besides good asymptotic runtime bounds, finger trees are also highly flexible: when combined with monoidal tags on elements (monoidal tag), finger trees can be used to implement efficient random-access sequences, ordered sequences, interval trees, and priority queues.
Basic Structure
Finger trees store data at the "fingers" (leaves) of the tree, with amortized constant-time access. A finger is a point that provides access to part of the data structure. In imperative languages, this is called a pointer. In finger trees, a "finger" is a structure pointing to the ends of the sequence or leaf nodes. Finger trees also store in each internal node the result of applying some associative operation to its descendants. The data stored in internal nodes can be used to provide functionality beyond that of typical tree data structures.
- The depth of a finger tree is calculated from bottom to top.
- The first level of a finger tree, i.e., the leaf nodes, contains only values and has depth \(0\). The second level has depth \(1\). The third level has depth \(2\), and so on.
- The closer to the root, the deeper the subtree of the original tree (the tree before it became a finger tree) that the node points to. Thus, working down the tree means moving from leaves toward the root, which is opposite to typical tree data structures. To achieve this structure, we must ensure the original tree has uniform depth. When declaring node objects, they must be parameterized by the type of their children. Nodes on the spine at depth \(1\) and above point to trees; through this parameterization, they can be represented by nested nodes.
Transforming a Tree into a Finger Tree
Note
A 2-3 tree is a tree-like data structure where each node with children (internal node) has either two children (a \(2\)-node) and one data element, or three children (a \(3\)-node) and two data elements. A 2-3 tree is a B-tree of order \(3\). Nodes outside the tree (leaf nodes) have no children and one or two data elements.
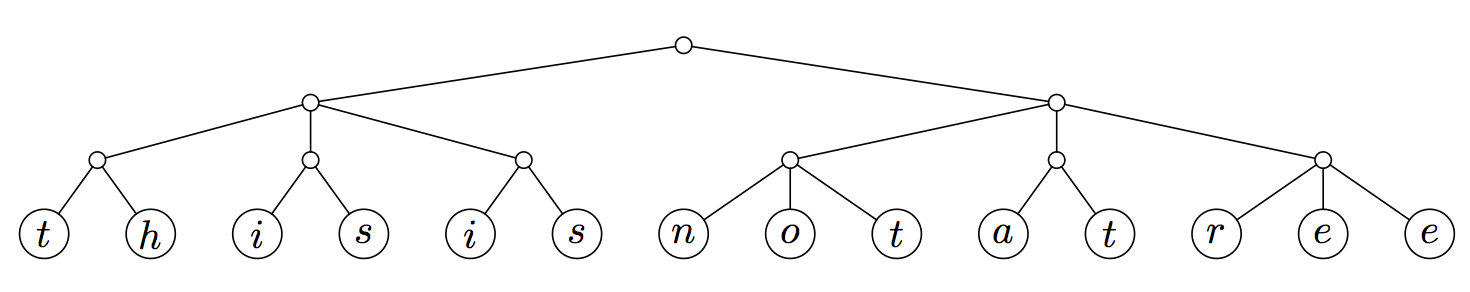
We start this process with a balanced 2-3 tree. For finger trees to work correctly, all leaf nodes need to be at the same level. As shown in the figure below (image taken from the finger tree paper):
A finger is "a structure that provides efficient access to nodes of a tree near a certain position." To create a finger tree, we need to place fingers at the left and right ends of the tree, take the leftmost and rightmost internal nodes of the tree and lift them up, leaving the rest of the tree hanging between them. This gives us amortized constant-time access to the ends of the sequence.
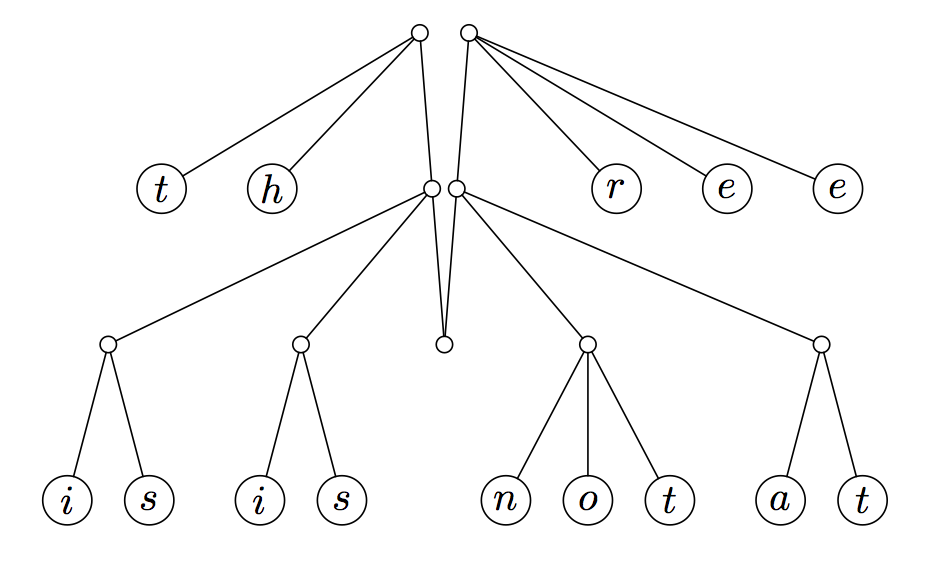
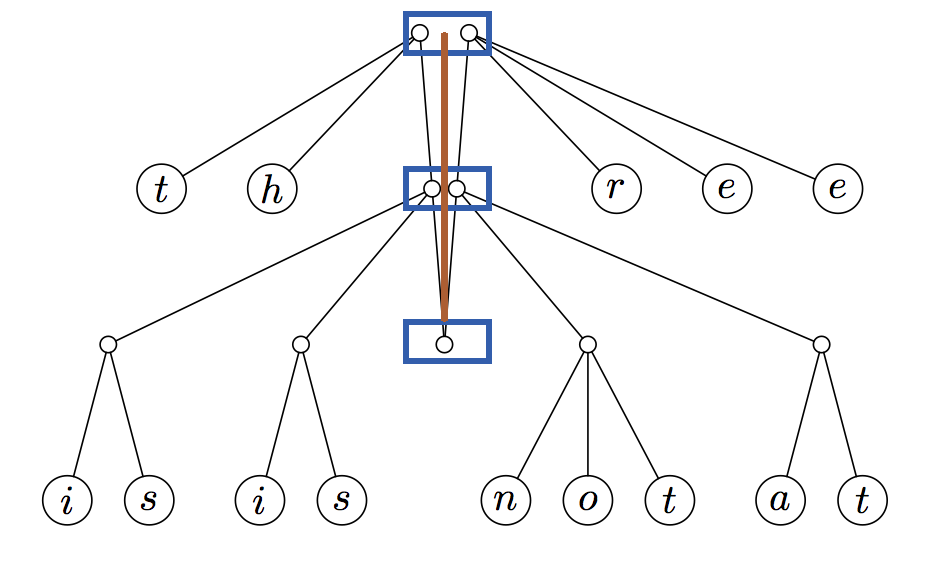
This new data structure is called a finger tree. A finger tree consists of several layers (blue boxes below) distributed along its spine (brown line):
1 2 3 4 5 6 | |
In the example, digits are nodes with letters. Each list is divided by the prefix or suffix of each node on the spine. In the transformed 2-3 tree, the digit list at the top level can have two or three elements, while lower levels have only one or two. To allow certain applications of finger trees to run so efficiently, finger trees permit \(1\) to \(4\) subtrees at each level. The digits of a finger tree can be converted into a list, such as:
1 | |
The top level has elements of type \(a\), the next level has elements of type Node \(a\) (the nodes between the spine and leaves), which generally means the \(n\)-th level of the tree has elements of type \(Node^{n}\) \(a\), or 2-3 trees of depth \(n\). This means a sequence of \(n\) elements is represented by a tree of depth Θ(log n). An element at distance \(d\) from the nearest end is stored at depth Θ(log d) in the tree.
Deque Operations
Finger trees can also be used to make efficient deques. All operations take Θ(1) time, whether the structure is persistent or not. It can be seen as an extension of implicit deques1:
- Replacing pairs with 2-3 nodes provides enough flexibility to support efficient concatenation. (To maintain constant-time deque operations, Digit must be extended to four.)
- Annotating internal nodes with a monoid allows efficient splitting.
1 2 3 4 5 | |
Time Complexity
Finger trees provide amortized constant-time access to the "fingers" (leaves) of the tree, where data is stored, and logarithmic-time concatenation and splitting in the size of the smaller part. They also store in each internal node the result of applying some associative operation to its descendants. The "summary" data stored in internal nodes can be used to provide functionality beyond that of a tree.
| Operation | Finger Tree | Annotated 2-3 Tree | List | Vector |
|---|---|---|---|---|
cons, snoc |
\(O(1)\) | \(O(\log n)\) | \(O(1)\)/\(O(n)\) | \(O(n)\) |
viewl, viewr |
\(O(1)\) | \(O(\log n)\) | \(O(1)\)/\(O(n)\) | \(O(1)\) |
measure/length |
\(O(1)\) | \(O(1)\) | \(O(n)\) | \(O(1)\) |
append |
\(O(\log \min(l1, l2))\) | \(O(\log n)\) | \(O(n)\) | \(O(m+n)\) |
split |
\(O(\log \min(n, l-n))\) | \(O(\log n)\) | \(O(n)\) | \(O(1)\) |
replicate |
\(O(\log n)\) | \(O(\log n)\) | \(O(n)\) | \(O(n)\) |
fromList, toList, reverse |
\(O(l)\)/\(O(l)\)/\(O(l)\) | \(O(l)\) | \(O(1)\)/\(O(1)\)/\(O(n)\) | \(O(n)\) |
index |
\(O(\log \min(n, l-n))\) | \(O(\log n)\) | \(O(n)\) | \(O(1)\) |
Applications
Finger trees can be used to build other trees. For example, a priority queue can be implemented by tagging internal nodes with the minimum priority among their children, or an indexed list/array can be implemented by tagging nodes with the count of leaves in their subtrees. Other applications include random-access sequences (as described below), ordered sequences, and interval trees.
Finger trees can provide average \(O(1)\) push, reverse, pop; \(O(\log n)\) append and split; and can be adapted for indexed or sorted sequences. Like all functional data structures, they are inherently persistent; that is, old versions of the tree are always preserved.
For code implementations, the finite sequence Seq in the Haskell core library uses a 2-3 finger tree (Data.Sequence), and the OCaml BatFingerTree module's implementation also uses a generic finger tree data structure. Finger trees can be implemented with or without lazy evaluation, but laziness allows for simpler implementations.
References and Further Reading
- Ralf Hinze and Ross Paterson, "Finger trees: a simple general-purpose data structure", Journal of Functional Programming 16:2 (2006) pp 197-217.
- Finger Tree - Wikipedia
-
Purely Functional Data Structures, Chris Okasaki (1999) ↩
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用