Finite State Machines
Prerequisites: Languages and Decision Problems
Finite State Automaton (Finite State Machine, FSM, also referred to as automaton) is one of the simplest computational models, characterized by its limited descriptive power and resources. Automata are widely used in OI and computer science, and their ideas are involved in many string algorithms. Therefore, it is recommended to complete the study of automata before learning some string algorithms (KMP, AC Automaton, SAM).
Introduction to Automata
First, let's understand what automata are used for: an automaton is a mathematical model that determines whether a signal sequence satisfies a specific pattern or rule.
Some terms in this statement can be explained in detail. A "signal sequence" refers to a sequence of signals arranged in order, such as each character of a string from front to back, each number of an array from \(1\) to \(n\), or each digit of a number from high to low. "Determining whether it satisfies a certain rule" can be understood as: we care whether the sequence belongs to a specific set. This set is defined by rules we set in advance, such as "all binary strings of even length" or "all palindrome strings".
Sometimes we need to answer questions like: does a given sequence satisfy a certain property? For example, whether a binary number is odd, whether a string is a palindrome, or whether it is a subsequence of another string, etc. Automata are mathematical tools used to solve such problems.
The working principle of an automaton is similar to a flowchart. Suppose you want to order a cup of milk tea on a food delivery platform. All your choices form a sequence. The following flowchart is an example:

For example, if your choice sequence is "open order interface -> select milk tea -> have money for milk tea", then the states you pass through in order might be "food delivery platform -> order interface -> pay for milk tea -> buy milk tea". In this way, our "milk tea automaton" helps us determine whether we have bought milk tea based on our choices. We can also find that there may be more than one way to reach a state. Similarly, if you don't buy milk tea, you might exit directly from the order interface, or you might not have enough money for milk tea and thus fail to buy it.
Through this automaton, we divide signal sequences into two categories: one is the signal sequences that result in buying milk tea, and the other is those that do not. Based on the final state, we complete a decision problem.
Although we used a flowchart to analogize the working process of an automaton, the flowchart itself is only an intuitive visualization tool and does not constitute a mathematical definition of an automaton. To more accurately describe the structure of an automaton, we need to abstract the elements in the flowchart. After abstraction, we find that the structure of the flowchart can actually be simplified to a directed graph, where each node represents a state, and each directed edge represents a transition between states.
Therefore, the core structure of an automaton can be formally viewed as a directed graph, which we call a state diagram.
The working method of an automaton is similar to a flowchart, but with differences: each node of an automaton is a decision node; each node of an automaton is merely a state rather than a task; the edges of an automaton can accept multiple characters (not limited to T or F).
For example, the automaton that accomplishes "determining whether a binary number is even" is as follows:
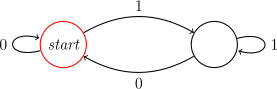
Starting from the initial node, accept the binary sequence of the number from high to low, and then see where it ends. If it ends at the red circle node, it is even; otherwise, it is not.
Here, we need to emphasize that we will mention terms like "character", "character set", etc., multiple times in the following text. This does not mean that automata can only be applied to the field of strings. Characters are not necessarily letters like \(\tt abc\cdots z\); they can also represent a choice.
If we need to determine the relationship between a finite signal sequence and another signal sequence (for example, whether another signal sequence is a subsequence of a certain signal sequence), a common method is to construct an automaton for that finite signal sequence. This will be discussed when learning KMP.
It should be noted that an automaton is only a mathematical model, not an algorithm, and not a data structure. There are many ways to implement the same automaton, which may have different time and space complexities.
Next, you can choose to further study automata on this page, or go to learn specific examples such as KMP, AC Automaton, or SAM.
FSM is divided into two categories: deterministic finite automata and nondeterministic finite automata.
Deterministic Finite Automaton
Deterministic Finite Automaton (DFA) is characterized by its deterministic decision process. Taking the "milk tea automaton" as an example, as long as you open the order interface, you will enter the order interface. There will be no unexpected situations such as network crashes preventing opening or the phone running out of power and turning off.
DFA
A DFA is a quintuple \((Q,\Sigma,\delta,q_0,F)\), including:
- Finite state set \(Q\). If a DFA is viewed as a directed graph, then the states in the DFA correspond to vertices in the graph.
- Character set \(\Sigma\). The automaton can only input these characters.
- Transition function \(\delta:Q\times \Sigma \to Q\) is a function that takes two parameters and returns one value, where the first parameter and the return value are both states, and the second parameter is a character from the character set. If a DFA is viewed as a directed graph, then the transition function in the DFA corresponds to edges between vertices, and each edge has a character.
- Initial state \(q_0\in Q\) is a special state. In different articles, the initial state is generally denoted by \(s\), \(\textit{start}\), \(q_0\). This article chooses to use \(q_0\).
- Accepting state set \(F\subseteq Q\) is a set of special states.
A DFA can be simply represented by the following structure:
Reference Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 | |
The process of finding the state sequence of an input string \(w\) in a DFA and determining whether it is accepted is called computation.
Computation Process of DFA
Let \(M=(Q,\Sigma,\delta,q_0,F)\) be a DFA, and \(w=w_1w_2\cdots w_n\in\Sigma^*\) be a string. If there exists a state sequence \(r_0,r_1,\cdots,r_n\) in \(Q\) satisfying
- \(r_0=q_0\),
- \(\delta(r_i,w_{i+1})=r_{i+1}\) for any \(i=0,1,\cdots,n-1\),
- \(r_n\in F\),
then we say \(M\) accepts \(w\). Otherwise, we say \(M\) does not accept \(w\).
When a DFA reads a string, it transitions character by character starting from the initial state according to the transition function. If after reading all characters of a string, it is in an accepting state, then we say the DFA accepts this string; otherwise, we say the DFA does not accept this string.
Formal Language
A formal language (or simply language) over a character set \(\Sigma\) is a set \(L\) of strings over \(\Sigma\).
Language Recognized by an Automaton
For an automaton \(M\), the language it recognizes \(L(M)\) is defined as the set of all substrings it accepts: \(\{w\mid M\text{ accepts }w\}\).
Not all languages can be recognized by a DFA.
Regular Language
If a language can be recognized by some DFA, it is called a regular language.
As mentioned earlier, an automaton can be represented by a state diagram. The following is a DFA that accepts and only accepts strings \(\tt a\), \(\tt ab\), \(\tt aac\):
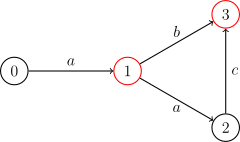
(The mismatch state is omitted in the diagram. All transitions not shown point to that mismatch state.)
Nondeterministic Finite Automaton
Nondeterministic Finite Automaton1 (NFA) is a natural generalization of DFA. In an NFA, for any state and any character, there may exist zero, one, or multiple successor states. At the same time, the NFA discussed in this section allows empty character transitions, meaning that it is possible to transition from a state to one of its successor states without consuming any character.
For example, consider the "milk tea automaton" again. After placing an order, even if you have money for milk tea, you might fail to buy milk tea due to poor network, which corresponds to multiple successors; or because you were too slow, even though the input string (i.e., the operation sequence) is the same, the milk tea sold out and you failed to buy it, which corresponds to the existence of empty characters—empty characters can be taken or not. The previous automaton can be slightly modified to achieve the above functionality:

Obviously, all DFAs are NFAs, so NFAs can recognize at least all regular languages. However, as an extension of DFA, can NFAs recognize more languages? Actually not. We will later explore the equivalence between DFA and NFA.
NFA
Let \(\mathcal{P}(Q)\) denote the power set of \(Q\). Let \(\varepsilon\notin\Sigma\) denote the empty string, and denote \(\Sigma_\varepsilon = \Sigma\cup\{\varepsilon\}\). An NFA is a quintuple \((Q,\Sigma,\delta,q_0,F)\), including:
- Finite state set \(Q\),
- Character set \(\Sigma\),
- Transition function \(\delta:Q\times \Sigma_{\varepsilon} \to \mathcal{P}(Q)\), a function that takes two parameters and returns a set of states, where the first parameter is a state, the second parameter is a character from the character set, and the return value is the set of all possible successor states (which may be empty),
- Initial state \(q_0\in Q\),
- Accepting state set \(F\subseteq Q\).
The computation process of an NFA is equivalent to running multiple DFAs simultaneously. Each step exhausts all possibilities. Finally, as long as one branch reaches an accepting state, the NFA accepts the entire string.
Computation Process of NFA
Let \(N=(Q,\Sigma,\delta,q_0,F)\) be an NFA, and the string \(w\) can be represented as \(y_1y_2\cdots y_m\in\Sigma^*_\varepsilon\). If there exists a state sequence \(r_0,r_1,\cdots,r_m\) in \(Q\) satisfying
- \(r_0=q_0\),
- \(r_{i+1}\in\delta(r_i,y_{i+1})\) for any \(i=0,1,\cdots,m-1\),
- \(r_m\in F\),
then we say \(N\) accepts \(w\). Otherwise, we say \(N\) does not accept \(w\).
Due to the allowance of empty characters, when representing the string \(w\) as \(y_1y_2\cdots y_m\in\Sigma^*_\varepsilon\), any number of empty characters can be inserted. For example, the string \(\texttt{abc}\) can be represented as \(\texttt{a}\varepsilon\texttt{bc}\varepsilon\varepsilon\in\Sigma^*_\varepsilon\). Compared to DFA where each input corresponds to only one result, each input of an NFA may correspond to multiple results, forming a result set.
Equivalence of DFA and NFA
We say two automata are equivalent if and only if they recognize the same language. DFA and NFA are equivalent, meaning every NFA is equivalent to some DFA; therefore, the class of languages recognized by NFA is also the set of all regular languages. Each DFA can be directly viewed as an NFA; conversely, an NFA can be converted to a DFA through powerset construction.
Powerset Construction
Assume the NFA is \(N = (Q, \Sigma, \delta, q_0, F)\). Define \(E(q)\) as the set of states reachable from state \(q\) by following only \(\varepsilon\) transitions.
Construct a DFA \(M = (Q', \Sigma, \delta', E(q_0), F')\), where:
- Finite state set \(Q' = \mathcal{P}(Q)\),
- Transition function \(\delta' : Q' \times \Sigma \to Q'\) satisfies \(\delta'(S, c) = \bigcup_{q \in S,~q' \in \delta(q, c)} E(q')\),
- Accepting state set \(F' = \{ S \subseteq Q \mid S \cap F \neq \varnothing \}\).
Obviously, at each step of the computation, the state where \(M\) is located corresponds to the set of possible states \(N\) could be in.
Although NFA and DFA have the same language recognition capability, NFA is still useful. This is because for some regular languages, the number of states required to represent them with an NFA is much smaller than that required by a DFA. For example, one can construct an NFA with \(n\) states such that the corresponding minimal DFA has \(\Theta(2^n)\) states. In this case, directly computing the NFA has better time complexity.
Time Complexity of Computing DFA and NFA
Let the given string length be \(n\), the number of automaton states be \(s\), and the character set size be constant. Then obviously, the time complexity of DFA computation is \(O(n)\), as we only need to simulate the above process.
The naive computation of NFA has time complexity \(O(ns^2)\), because we need to consider each successor and the complexity required for state merging. Of course, we can use bitset or the Method of Four Russians to optimize the computation complexity to \(O\left(\dfrac{ns^2}{w}\right)\) or \(O\left(\dfrac{ns^2}{w\cdot \log n}\right)\).
Regular Expressions and Regular Languages
This section discusses the definition and properties of regular expressions and regular languages, and studies the relationship between regular expressions and FSM.
Regular Expressions
Regular expressions are another commonly used method to describe regular languages. Although we see this name in many modern languages (such as Python), these languages actually implement a superset of regular expressions.
Regular Expression
Given a character set \(\Sigma\), a regular expression is a string of symbols defined inductively by the following rules:
- Any character \(c \in \Sigma\) is a regular expression;
- The empty string symbol \(\varepsilon\) is a regular expression;
- The empty language symbol \(\varnothing\) is a regular expression;
- If \(R_1\) and \(R_2\) are regular expressions, then \((R_1 + R_2)\), \((R_1 R_2)\) (also written as \((R_1 \cdot R_2)\)), and \((R_1^\ast)\) are regular expressions.
The goal of regular expressions is to describe a language using these symbols. Each regular expression has a corresponding formal language.
Language Represented by a Regular Expression
Let the formal language corresponding to each regular expression \(R\) be \(L(R)\). Then:
- If \(R = c\), where \(c \in \Sigma\), then \(L(R) = \{c\}\);
- If \(R = \varepsilon\), then \(L(R) = \{\varepsilon\}\);
- If \(R = \varnothing\), then \(L(R) = \varnothing\);
- If \(R = (R_1 + R_2)\), then \(L(R) = L(R_1) \cup L(R_2)\);
- If \(R = (R_1 R_2) = (R_1\cdot R_2)\), then \(L(R) = \{ uv \mid u \in L(R_1),~ v \in L(R_2) \}\), where \(uv\) means concatenating the two strings;
- If \(R = (R_1^\ast)\), then \(L(R) = \{u_1 u_2 \cdots u_n \mid u_i \in L(R_1),\ n \in \mathbf{N}_+\}\cup\{\varepsilon\}\), also known as Kleene star or Kleene closure, or simply closure.
Of course, after specifying the precedence of operations, these parentheses can be omitted when they do not cause confusion.
Example
Let \(L(R_1) = \{0,\ 01\}\), \(L(R_2) = \{\varepsilon,\ 1,\ 11,\ 111,\ \dots\}\). Then:
- \(L(R_1R_2) = \{0,\ 01,\ 011,\ 0111,\ \dots\}\),
- \(R_2^\ast = R_2\),
- \(L(R_1 + R_2) = \{0,\ 01,\ \varepsilon,\ 1,\ 11,\ 111,\ \dots\}\).
Each regular expression can be converted to an NFA via Thompson's construction, and each DFA can be converted to a regular expression via the state elimination method2. Therefore, regular expressions and FSM are equivalent.
Regular Languages
In this subsection, we do not consider specific regular expressions, but instead consider regular expressions with variables as parameters (variables can be any regular language). Using the algebraic laws of regular expressions helps simplify regular expressions.
Algebraic Properties of Regular Languages
- Commutativity of union: \(L + M = M + L\)
- Associativity of union: \((L + M) + N = L + (M + N)\)
- Associativity of concatenation: \((LM)N = L(MN)\)
- \(\varnothing\) is the identity for union: \(\varnothing + L = L + \varnothing = L\)
- \(\varepsilon\) is the identity for concatenation: \(\varepsilon L = L \varepsilon = L\)
- \(\varnothing\) is the zero for concatenation: \(\varnothing L = L \varnothing = \varnothing\)
- Distributivity: \(L(M + N) = LM + LN\), \((M + N)L = ML + NL\)
- Idempotence of union: \(L + L = L\)
- Laws related to closure: \((L^\ast)^\ast = L^\ast\), \(\varnothing^\ast = \varepsilon\), \(\varepsilon^\ast = \varepsilon\)
The closure properties of regular languages are also important. These properties allow us to start from some simple automata and, through certain operations, construct finite state machines (FSM) that can recognize other languages. In short, closure properties can serve as tools for constructing complex FSMs.
Regarding the closure properties of regular languages, we have:
Closure Properties of Regular Languages
Let \(L,M\) be two regular languages over the character set \(\Sigma\), and let \(h:\Sigma\to\Sigma^*\) be a mapping. Define the homomorphism of a string \(s=s_1s_2\cdots s_n\) as \(h(s)=h(s_1)h(s_2)\cdots h(s_n)\). Then,
- The union of two regular languages \(L + M\) is regular,
- The concatenation of two regular languages \(LM\) is regular,
- The closure of a regular language \(L^*\) is regular,
- The complement of a regular language \(\Sigma^*\setminus L\) is regular,
- The intersection of two regular languages \(L\cap M\) is regular,
- The difference of two regular languages \(L\setminus M\) is regular,
- The reversal of a regular language \(L^R=\{s_n\cdots s_2s_1 \mid s=s_1s_2\cdots s_n\in L\}\) is regular,
- The homomorphism of a regular language \(h(L)=\{h(s)\mid s\in L\}\) is regular,
- The inverse homomorphism of a regular language \(h^{-1}(L) = \{ s \in \Sigma^\ast \mid h(s) \in L \}\) is regular.
A simple corollary is that all finite languages are regular languages. In fact, Trie is an automaton that recognizes them.
Myhill–Nerode Theorem
The Myhill–Nerode theorem provides a criterion for determining whether a language is regular. The theorem describes the structural characteristics of regular languages through the concept of equivalence classes.
Nerode Equivalence Relation
For a language \(L\) and any strings \(x,y\in \Sigma^\ast\), if for any \(z\in\Sigma^*\), we have \(xz\in L\iff yz\in L\), then we say strings \(x\) and \(y\) are equivalent with respect to \(L\), denoted as \(x\equiv_L y\).
That is, for two strings \(x\) and \(y\), if after appending the same arbitrary string \(z\) (including the empty string) to \(x\) and \(y\), they always either both belong to \(L\) or both do not belong to \(L\), then we say \(x\) and \(y\) are equivalent with respect to \(L\).
According to the above definition, we partition the set of all finite strings into one or more equivalence classes. If and only if the number of these equivalence classes is finite, we can use these equivalence classes to construct a DFA that recognizes the language. The number of states of this DFA equals the number of equivalence classes. Moreover, this number of states is the smallest among all DFAs that can recognize the language. This is the Myhill–Nerode theorem.
Myhill–Nerode Theorem
A language \(L\) is regular if and only if the number of equivalence classes into which \(\Sigma^\ast\) is partitioned by the equivalence relation \(\equiv_L\) is finite.
For any DFA that recognizes language \(L\), any two strings \(x\) and \(y\) that drive it to the same state must be in the same equivalence class.
Furthermore, the number of equivalence classes is the number of states in the minimal DFA that can recognize \(L\). Each equivalence class corresponds exactly to one state in the minimal DFA. This minimal DFA is unique up to isomorphism.
This theorem provides a method to construct a DFA using equivalence relations:
- The state set is all equivalence classes obtained by partitioning according to the equivalence relation. For each equivalence class, arbitrarily choose a representative string (e.g., a string with the smallest length).
- To construct the transition function, simply append the character in the transition to the chosen representative string, and find the state corresponding to the equivalence class of the resulting string. That is the successor state of the corresponding transition. Because all strings in the same equivalence class are equivalent, the choice of representative string does not affect the result of the transition.
- The initial state is the equivalence class corresponding to the empty string \(\varepsilon\).
- The accepting state set is the set of equivalence classes whose representative strings belong to the given language.
As a classic example, the Suffix Automaton is a minimal DFA constructed using the Myhill–Nerode theorem.
The Myhill–Nerode theorem is often applied to the construction of DFAs corresponding to some infinite regular languages. Many times, the conditions of the problem are simple, and we only need to examine the set of strings with not too long lengths to construct an automaton that recognizes the entire language.
Example Problem
This section introduces how to practically apply the Myhill–Nerode theorem through an example problem.
P12294 [THUPC 2025 Finals] A 01 String, n Ternary Operators, Final Value is 1 (Hard Version)
The ternary operation table \(s_0s_1\cdots s_7\) (where \(s\) consists only of \(0,1\)) about \(a,b,c\) means that if the \((a+2b+4c)\)-th bit of \(s\) is \(1\), then return \(1\); otherwise, return \(0\).
Given the operation table \(s\) and \(q\) binary strings of length \(2n+1\), you need to answer for each binary string separately:
Is it possible to perform \(n\) operations, each time replacing three consecutive digits with the corresponding operation value, such that the final result is \(1\)? Provide a solution, or determine that no solution exists.
\(1\le 2n+1\le 10^5,~\sum(2n+1)\le 3\times 10^5\).
Solution
The set of binary strings that can synthesize \(1\) is a regular language (i.e., there exists a DFA that can determine whether a binary string can synthesize \(1\))6. Therefore, consider using the Myhill–Nerode theorem. Because the conditions are simple, through experimentation, we only need to partition equivalence classes for binary strings of length \(\le 9\); when determining whether two strings are equivalent, we only need to enumerate suffixes of length \(\le 6\) for judgment. As long as for two strings, after appending any suffix of length \(\le 6\), they either both can synthesize the desired string or both cannot synthesize the desired string, then these two strings are equivalent.
Each transition is equivalent to appending a new binary character to the current string, and then changing this new string to the string with the smallest length in the equivalence class of this new string. Design an automaton according to the above transitions. This automaton can determine in \(O(n)\) time complexity whether there exists a way to compute a string of length \(n\) such that the result is \(1\). At the same time, the number of states of the automaton is very small.
For convenience, we will build \(6\) automata, which respectively represent whether it is possible to compute to get the result \(0,1,00,01,10,11\). For all possible operation tables, the maximum number of states of the automaton is \(47\).
Using the automaton, through appropriate preprocessing, we can consider using doubling or segment tree to implement static interval queries to determine whether there exists a way to compute the interval such that the result is \(1\). The former has \(O(\log n)\) per query, and the latter has \(O(1)\) per query.
Consider using divide and conquer to solve the construction problem. Let \(f(l,r,t)\) denote the scheme for merging the interval \([l,r]\) to get \(t\in\{{0,1,00,01,10,11}\}\). At this time, use heuristic splitting, maintain two pointers \(i,j\), one scanning from left to right and the other from right to left, to enumerate the split point \(\textit{mid}\) as \(i\) or \(j\). For \(t\in\{{0,1}\}\), enumerate how \(t\) is divided into left and right parts, where one part has length \(2\) and the other part has length \(1\). (For example, for the median operation table \(s=00010111\), \(1\) can be divided into \(01\) and \(1\).) For \(t\in\{{00,01,10,11}\}\), then \(t\) is directly divided into left and right parts.
If the divided left and right parts are \(t_1\) and \(t_2\) respectively, then further determine whether \([l,mid]\) can generate \(t_1\) and \([\textit{mid}+1,r]\) can generate \(t_2\). If yes, then recursively divide. If using \(O(1)\) segment tree determination, the complexity of this heuristic splitting construction is \(O(n\log n)\); otherwise, using doubling determination, the construction complexity is \(O(n\log^2n)\).
If segment tree is used, the total complexity is \(O(n|Q|\log n+n\log n)\), where \(|Q|\le 47\). For convenience, the reference code uses doubling and reduces constant through underlying blocking. The corresponding total complexity is \(O(n|Q|\log n+n\log^2 n)\).
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 139 140 141 142 143 144 145 146 147 148 149 150 151 152 153 154 155 156 157 158 159 160 161 162 163 164 165 166 167 168 169 170 171 172 173 174 175 176 177 178 179 180 181 182 183 184 185 186 187 188 189 190 191 192 193 194 195 196 197 198 199 200 201 202 | |
Exercises
- Median Replace Hard
- JOISC 2024 Card Collection (Build automaton via Myhill–Nerode theorem. This problem can achieve multiple interval queries.)
DFA Minimization
As mentioned earlier, two DFAs are equivalent if and only if they recognize the same regular language. According to the recognized languages, all DFAs are divided into infinitely many equivalence classes. In algorithms like DP over DP, the constructed DFA may have too large \(|Q|\), making the outer DP transition complexity too high. Therefore, it is often necessary to find the minimal DFA in the equivalence class of the DFA to reduce the outer DP transition complexity.
The Myhill–Nerode theorem in the previous section provides a construction method. However, for some more complex problems, directly constructing via the Myhill–Nerode theorem requires traversing a fairly large set of strings, taking a lot of time. Therefore, we need a method that can start from an already constructed DFA (usually easier) and directly construct a minimal DFA. This is called the DFA minimization problem.
The commonly used algorithm for DFA minimization is Hopcroft's algorithm. Since the Myhill–Nerode theorem states that for any DFA that recognizes a language, strings that drive it to the same state must be Nerode equivalent. All Nerode equivalent strings correspond to the same state in the minimal DFA. Therefore, a state in the minimal DFA must be a set of several states in the current DFA. We can start from the state set of the existing DFA and partition them into several equivalence classes without examining specific strings. Hopcroft's algorithm starts from the coarsest partition \(\{F,Q\setminus F\}\) and uses a series of evidence \(A\) to refine this partition until no further refinement is possible. This is the core idea of Hopcroft's algorithm.
The so-called evidence \(A\) is a set of states, and it and its complement \(Q\setminus A\) must correspond to different Nerode equivalence classes. That is, there exists some string \(s\in\Sigma^*\) such that starting from states in \(A\) and \(Q\setminus A\), after reading string \(s\), all states in \(A\) are in accepting states, and all states in \(Q\setminus A\) are in non-accepting states, or vice versa. Therefore, if there are two states \(u,v\in Q\) such that under some character \(c\), one transitions to evidence \(A\) and the other transitions outside evidence \(A\), i.e., \(\delta(u,c)\in A\) and \(\delta(v,c)\in A\) hold and only one holds, then \(u,v\) are also not in the same Nerode equivalence class—states \(\delta(u,cs)\) and \(\delta(v,cs)\) have exactly one in an accepting state. Therefore, using whether \(\delta(u,c)\in A\) holds, we can refine the partition. Specifically, let
If \(S_x\) and \(P_x\setminus S_x\) are both non-empty, then the state set \(P_x\) in the current partition can be refined into \(S_x\) and \(P_x\setminus S_x\).
At the beginning, put the accepting state set \(F\) as evidence into the evidence set \(W\), i.e., \(W\gets\{F\}\), and maintain the current partition as \(P\gets\{F,~Q\setminus F\}\). The initial evidence obviously holds: states in \(F\) and \(Q\setminus F\) cannot be equivalent. Each time, arbitrarily take a set \(A\) from the evidence set \(W\) to refine the current partition. Enumerate all characters \(c\in\Sigma\). For each state set \(P_x\) in the current partition \(P\), compute \(S_x\) as described earlier. If \(S_x\neq\varnothing\) and \(|S_x|\neq|P_x|\), it means \(P_x\) can be further divided into two sets \(S_x\) and \(P_x\setminus S_x\). Replace \(P_x\) in \(P\) with them directly.
Whenever a finer partition is obtained, it means new evidence is obtained. In principle, we can put both newly obtained \(S_x\) and \(P_x\setminus S_x\) into the evidence set \(W\), waiting for further verification later. However, this is not necessary. It is easy to understand that for three evidences \(P_x,S_x,P_x\setminus S_x\), we only need to verify any two of them to ensure the correctness of the result: because the results are only \(\delta(u,c)\in S_x\), \(\delta(u,c)\in P_x\setminus S_x\), and \(\delta(u,c)\notin P_x\), and dividing a set into three parts only requires two judgments. Therefore, when dividing \(P_x\) into \(S_x\) and \(P_x\setminus S_x\), if \(P_x\) is still in the evidence set \(W\), it means \(P_x\) has not been tested yet, and we need to replace \(P_x\) in the evidence set \(W\) with \(S_x\) and \(P_x\setminus S_x\); otherwise, the current partition must be equivalent to3 having tested \(P_x\), so we only need to put the smaller of \(S_x\) and \(P_x\setminus S_x\) into the evidence set \(W\). Similar to heuristic splitting, this can achieve good complexity.
Writing the above process as pseudocode:
When implementing the algorithm, the bottleneck of complexity lies in the computation of \(S\). It is not feasible to directly traverse all \(q\in Q\) and determine whether \(\delta(q,c)\in A\) holds. Therefore, before running the algorithm, we need to preprocess reverse transition edges \(\{q\in Q\mid \delta(q,c)=a\}\). Then, using these reverse transitions, traversing \(a\in A\), we can obtain the set \(S\). This ensures that each transition \(\delta(q,c)=a\) is only traversed when \(a\) belongs to some evidence; and the evidence filtering method mentioned earlier ensures that in the sequence of evidences containing \(a\) actually used in the algorithm, \(A_1\supset A_2\supset\cdots\supset A_k\), the previous one is at least twice the size of the next one, so \(k\in O(\log n)\). That is, each transition edge is traversed at most \(O(\log n)\) times, and the total number of transitions is \(n|\Sigma|\). Therefore, the total complexity is \(O(n|\Sigma|\log n)\).
The reference implementation is as follows:4
Reference Implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 | |
This reference implementation allows the states of the automaton to have labels of any integer value, not just the binary labels "accepting" and "non-accepting". As can be seen from the reference implementation, the only difference from the basic Hopcroft algorithm is the construction of the initial partition and evidence set. This extended automaton is also called a Moore machine. An application of it can be seen in the second example of this section.
Example Problems
This section introduces how to practically apply DFA minimization techniques through two example problems.
Example Problem
Given a binary string \(a\) of length \(n\) containing \(01?\), initial variable \(x = 0\), we traverse each bit \(a_i\) in order and perform the following operations:
- If \(a_i = 0\), let \(x \gets x - \text{lowbit}(x)\);
- If \(a_i = 1\), let \(x \gets x + \text{lowbit}(2^k - 1 - x)\);
- If \(a_i = ?\), choose either \(0\) or \(1\), corresponding to one of the above two operations.
Finally, if \(x \in [0, r]\), then the operation sequence is said to be good.
Now for each \(j = 1 \ldots n\), find the number of "good" complete sequences under the constraint that \(a_j = 0\). In particular, when \(a_j = 1\), the answer is \(0\).
\(1\le n\le 10^5,~1\le k\le 20,~0\le r<2^k\). Output modulo \(998244353\).
Solution
Consider naive DP. Let \(f_{i,j}\) be the number of ways starting from \(x=0\), after operations on \([1,i]\), the current number is \(j\). Let \(g_{i,j}\) be the number of ways starting from \(x=j\), after operations on \([i,n]\), finally \(x \in [0, r]\). The answer forcing \(a_i=0\) is \(\sum_j f_{i-1,j}g_{i+1,j - \text{lowbit}(j)}\). Complexity is \(O(n2^k)\).
Consider directly building the transition of \(j\) into a DFA, then run DFA minimization, and then DP.
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 | |
Minimal Subset Difference
Define \(f(n)\) as the minimum absolute value obtained by inserting plus or minus signs between all digits of the decimal number \(n\).
There are \(T\) queries. Each query gives \(l, r, k\), and asks for the number of \(m\) satisfying \(l \le m \le r\) and \(f(m) \le k\).
\(1 \le T \le 5\times 10^4\), \(1 \le l \le r \le 10^{18}\), \(0 \le k \le 9\).
Solution
First, give a greedy method to compute \(f(n)\). Consider a number from high to low. Initially, set the sum to \(0\). When processing a digit, if the currently synthesized number is negative, add the current digit; if it is positive, subtract the current digit. This greedy computation ensures that the absolute value of \(f(n)\) is at most \(9\). So the actual absolute value of \(f(n)\) is at most \(9\).
We further think about the maximum value that can be synthesized during the intermediate process to get the final answer. Since the answer is at most \(9\), and there are only \(18\) digits, each time we can only add or subtract at most \(9\). The numbers that can be synthesized during the process must be less than or equal to \(90\); otherwise, we cannot subtract back. Actually, this upper bound can be even lower7.
Consider naive DP over DP. First, think about how the inner DP determines the answer for a number: define \(g_{i,c}\) as whether we can synthesize \(c\) based only on the first \(i\) digits of this number. According to the above, \(c\) only needs to be kept for numbers less than or equal to \(90\). If the current digit is \(v\), then the transition is:
The outer DP considers digit DP. Difference the queries. Let the state be \(f_{\textit{len},\textit{lim},\textit{sta}}\), where the subscripts respectively indicate that we have considered \(\textit{len}\) digits, whether there is an upper bound restriction, the current automaton state is \(\textit{sta}\), etc.
Unlike ordinary DFA, we need to record the answer corresponding to each state of the automaton. Run a brute-force search, and we will find that the number of inner DP states is only \(19564\). Then directly run DFA minimization, which can optimize the number of states to \(715\).
At this point, we preprocess all digit DP answers for \(\textit{lim}=0\). During multiple tests, we only need to run the case \(\textit{lim}=1\), and we can quickly find the answer.
Time complexity is \(O(|S||\Sigma|\log |S|+(|Q||\Sigma|+T)|\Sigma|\log_{10} V)\) (where \(|S|=19564\), \(|Q|=715\)).
Reference Code
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 | |
Exercises
Common Applications of Automata
This section lists some common applications of automata in algorithm competitions5.
Trie
Trie is the first automaton that most OIers encounter. It accepts and only accepts elements in a specified set of strings. The transition function is the edges on the Trie, and the accepting states are the states reached when each string is inserted into the Trie.
KMP Automaton
The KMP algorithm can be viewed as an automaton. The KMP automaton based on string \(s\) accepts and only accepts strings that have \(s\) as a suffix. Its accepting state is \(|s|\).
Transition function:
AC Automaton
AC Automaton accepts and only accepts strings that have some element of a specified set of strings as a suffix. That is, Trie + KMP.
Suffix Automaton
Suffix Automaton accepts and only accepts suffixes of a specified string.
Generalized Suffix Automaton
Generalized Suffix Automaton accepts and only accepts suffixes of some element in a specified set of strings. That is, Trie + SAM.
The relationship between generalized SAM and SAM is the same as that between AC automaton and KMP automaton.
Palindrome Automaton
Palindrome Automaton is special; it cannot be very conveniently defined as an automaton.
If we need to define it, it accepts and only accepts the center and right half of all palindrome substrings of a string.
"Center and right half" means literally for odd-length palindromes; for even-length palindromes, it is defined as a special character plus the right half. This definition seems strange, but it allows PAM to truly be an automaton, not just two trees.
Sequence Automaton
Sequence Automaton accepts and only accepts subsequences of a specified string.
DP over DP
DP over DP is an application of automata. It can be seen as first building an automaton through inner DP, and then performing counting or optimization tasks through DP on the automaton in the outer layer.
Suffix Links
Since automata and matching are closely related, and a basic idea of matching is "if this string doesn't work, try its suffix", many automata (KMP, AC automaton, SAM, PAM) have the concept of suffix links.
A state corresponds to several strings. Its suffix link points to the state corresponding to the longest common proper suffix of the strings corresponding to that state. Generally, suffix links form a tree, and the suffix link trees of different automata have some common properties, which can be noted when learning.
Further Reading
- Computational Complexity (1) Warming Up: Automaton Models
- National Team 2021 Thesis Xu Zhe'an Introduction to Finite State Automata and Their Applications
- Myhill–Nerode theorem - Wikipedia
- Knuutila, Timo. "Re-describing an algorithm by Hopcroft." Theoretical Computer Science 250, no. 1-2 (2001): 333-363.
- Hopcroft, John E., Rajeev Motwani, and Jeffrey D. Ullman. "Introduction to automata theory, languages, and computation." Acm Sigact News 32, no. 1 (2001): 60-65.
-
In this definition, we allow transitions between states via empty characters (\(\varepsilon\)), so more accurately, this is a nondeterministic finite automaton with \(\varepsilon\)-transitions (NFA-\(\varepsilon\)). Some textbooks directly call it NFA. For brevity, this article adopts this usage. In theory, NFA and NFA-\(\varepsilon\) are distinguished, but in practice, their computational power is the same. ↩
-
See National Team 2021 Thesis Xu Zhe'an Introduction to Finite State Automata and Their Applications, Section 3.2. ↩
-
Here "equivalent" means that although \(P_x\) may not have actually been tested, even if we test evidence \(P_x\) on the current partition, there will be no improvement. Simply put, on the tree of evidence sets obtained by set splitting, some ancestor and all side branches on the path have been tested. Therefore, by induction, it is equivalent to having been tested. ↩
-
There is a detail in the algorithm implementation: For an evidence \(A\), after testing some characters, this evidence set may have split into \(B\) and \(C\). Assume \(|B|\ge |C|\). Since in the reference implementation, the smaller set \(C\) is inserted at the end of the evidence queue, and the larger evidence set \(B\) replaces the original position of set \(A\). When the algorithm continues to run, it actually only uses evidence \(B\) to test the remaining characters. This is correct. This is because for the characters already tested, at least two sets \(A\) and \(C\) have been verified; for the characters not yet tested, at least two sets \(B\) and \(C\) have been verified. ↩
-
The definition of automaton in this article requires it to be complete, meaning that for any state and any character, there must be a transition. In the description of these string-related automata, the mismatch state is usually omitted. Trie, SAM, etc., are such examples. To adapt to the definition provided in this article, we need to explicitly add the mismatch state in the description of these automata. ↩
-
See official solution. ↩
-
See National Team 2021 Thesis Xu Zhe'an Introduction to Finite State Automata and Their Applications, Example 5.2. ↩
本页面最近更新:,更新历史
发现错误?想一起完善? 在 GitHub 上编辑此页!
本页面贡献者:OI-wiki
本页面的全部内容在 CC BY-SA 4.0 和 SATA 协议之条款下提供,附加条款亦可能应用